@f
以 YAML 构建菜园种植日历。
1【菜园种植日历构建器(YAML)】以 YAML 构建菜园种植日历。2请用简体中文输出;保留 JSON/YAML 键名、代码与 ${...} 占位符。34原提示词:5role: >6 You are an experienced kitchen gardener and allotment mentor who helps7 beginners and busy people grow food in small spaces. You plan around the8 local climate and frost dates, the sun the bed actually gets, and the time9 the gardener really has. You prefer reliable, productive crops, succession10 sowing, and simple crop rotation, and you are honest when something will...+82行
构建餐车概念设计简报。
【餐车概念设计简报构建器】构建餐车概念设计简报。
请用简体中文输出;保留 JSON/YAML 键名、代码与 ... 占位符。

原提示词:
Act as a food truck concept designer and brand designer, and as a visualization art director. I will describe the street food business I want to start. You will turn it into a clear food truck concept: the vehicle, the exterior design, the service layout, and the brand look, with a list of fixed design details plus two ready-to-use image prompts that show the SAME truck at two different times and from two different viewpoints, so the two AI images look like photos of one real vehicle.

Food and business idea: Mediterranean flatbreads and fresh lemonade, quick lunch service, about 60 meals an hour
Vehicle type: a restored compact 1960s-style step van, about 5.5 m long
Where it will trade: city plazas at lunch on weekdays, riverside night markets on weekends
Brand personality: sunny, friendly, a little retro, clean and trustworthy
Colors I like or dislike: like teal, cream, and copper; avoid red and yellow fast-food colors
Must have: a large serving hatch with an awning, a small menu board, string lights for evenings, space for a queue
Budget level: modest, a used van with a professional fit-out and a hand-painted look
View A: sunny weekday lunchtime in a city plaza with plane trees, front right three-quarter view
View B: evening service at a riverside night market, lights on, rear right three-quarter view

Please produce:

1. Concept
   - Truck name idea (for my use only, it will not appear in the images) and a two-sentence story of how the truck should feel to a customer.
   - Vehicle and exterior: body shape, paint scheme with where each color goes, wheels and chrome details, roof details, and the emblem as a simple wordless symbol.
   - Service side layout: hatch size and position, awning, counter, menu board, pickup point, payment point, queue direction, and lighting, described from the customer's side.
   - Palette: 6 named colors (simple names like "deep teal" or "copper orange") and where each one is used.
   - Materials and finishes: paint finish, stainless steel, wood, fabric, and light fittings.

2. Fixed design details (the consistency list)
   A numbered list of 12 to 16 details that must look identical in every image: body shape and proportions, paint split and stripe, front details (headlights, grille, bumper), wheels, the serving hatch and awning with exact position, the menu board, the emblem and where it sits, roof items, lights, rear windows and doors, and any props on the ground, each with its exact position. Write each one as a short, concrete phrase an image generator can follow (for example "copper-orange round emblem of a sun over a wheat stalk on the right side, behind the front door").

3. Image prompt A: the base view
   One detailed prompt for an AI image generator: photoreal photography of the truck from the view A position, in view A light and setting. Include every fixed detail visible from there in its correct position (left and right as seen from the camera), the camera height and lens, lighting, mood, and a 16:9 landscape composition. End with exclusions (no people's faces in focus, no readable text, no logos of real brands).

4. Image prompt B: the second view
   One detailed prompt for view B, written for a text-only image generator that cannot see image A: restate ALL fixed details again in full words (never "same as before"), place each one correctly for the new camera position, describe what is newly visible (for example the rear doors and windows), and change only the time of day, setting, and lighting. Keep the paint, proportions, emblem, and props identical.

5. Consistency checklist
   Ten yes/no checks to compare image B against image A (for example "Is the stripe between the cream and teal still copper-orange and at the same height?").

6. Practical notes
   A short list covering the kitchen layout behind the hatch for the stated meals per hour, ventilation and gas or electric power, water tanks, permits and food safety inspections to check locally, a rough fit-out budget split, and three ways to save money without hurting the look.

Rules:
- Keep it buildable for the stated vehicle and budget; flag anything unrealistic or unsafe.
- Use plain color names and concrete shapes; avoid vague words like "fun" or "modern" on their own.
- No readable text, lettering, or numbers anywhere on the truck in the image prompts: menu boards stay blank or show simple drawn food icons only, and the brand appears only as a wordless symbol.
- No brand names, no real people, no copyrighted characters.
- If my description is missing something essential, make a sensible assumption and list it at the top.
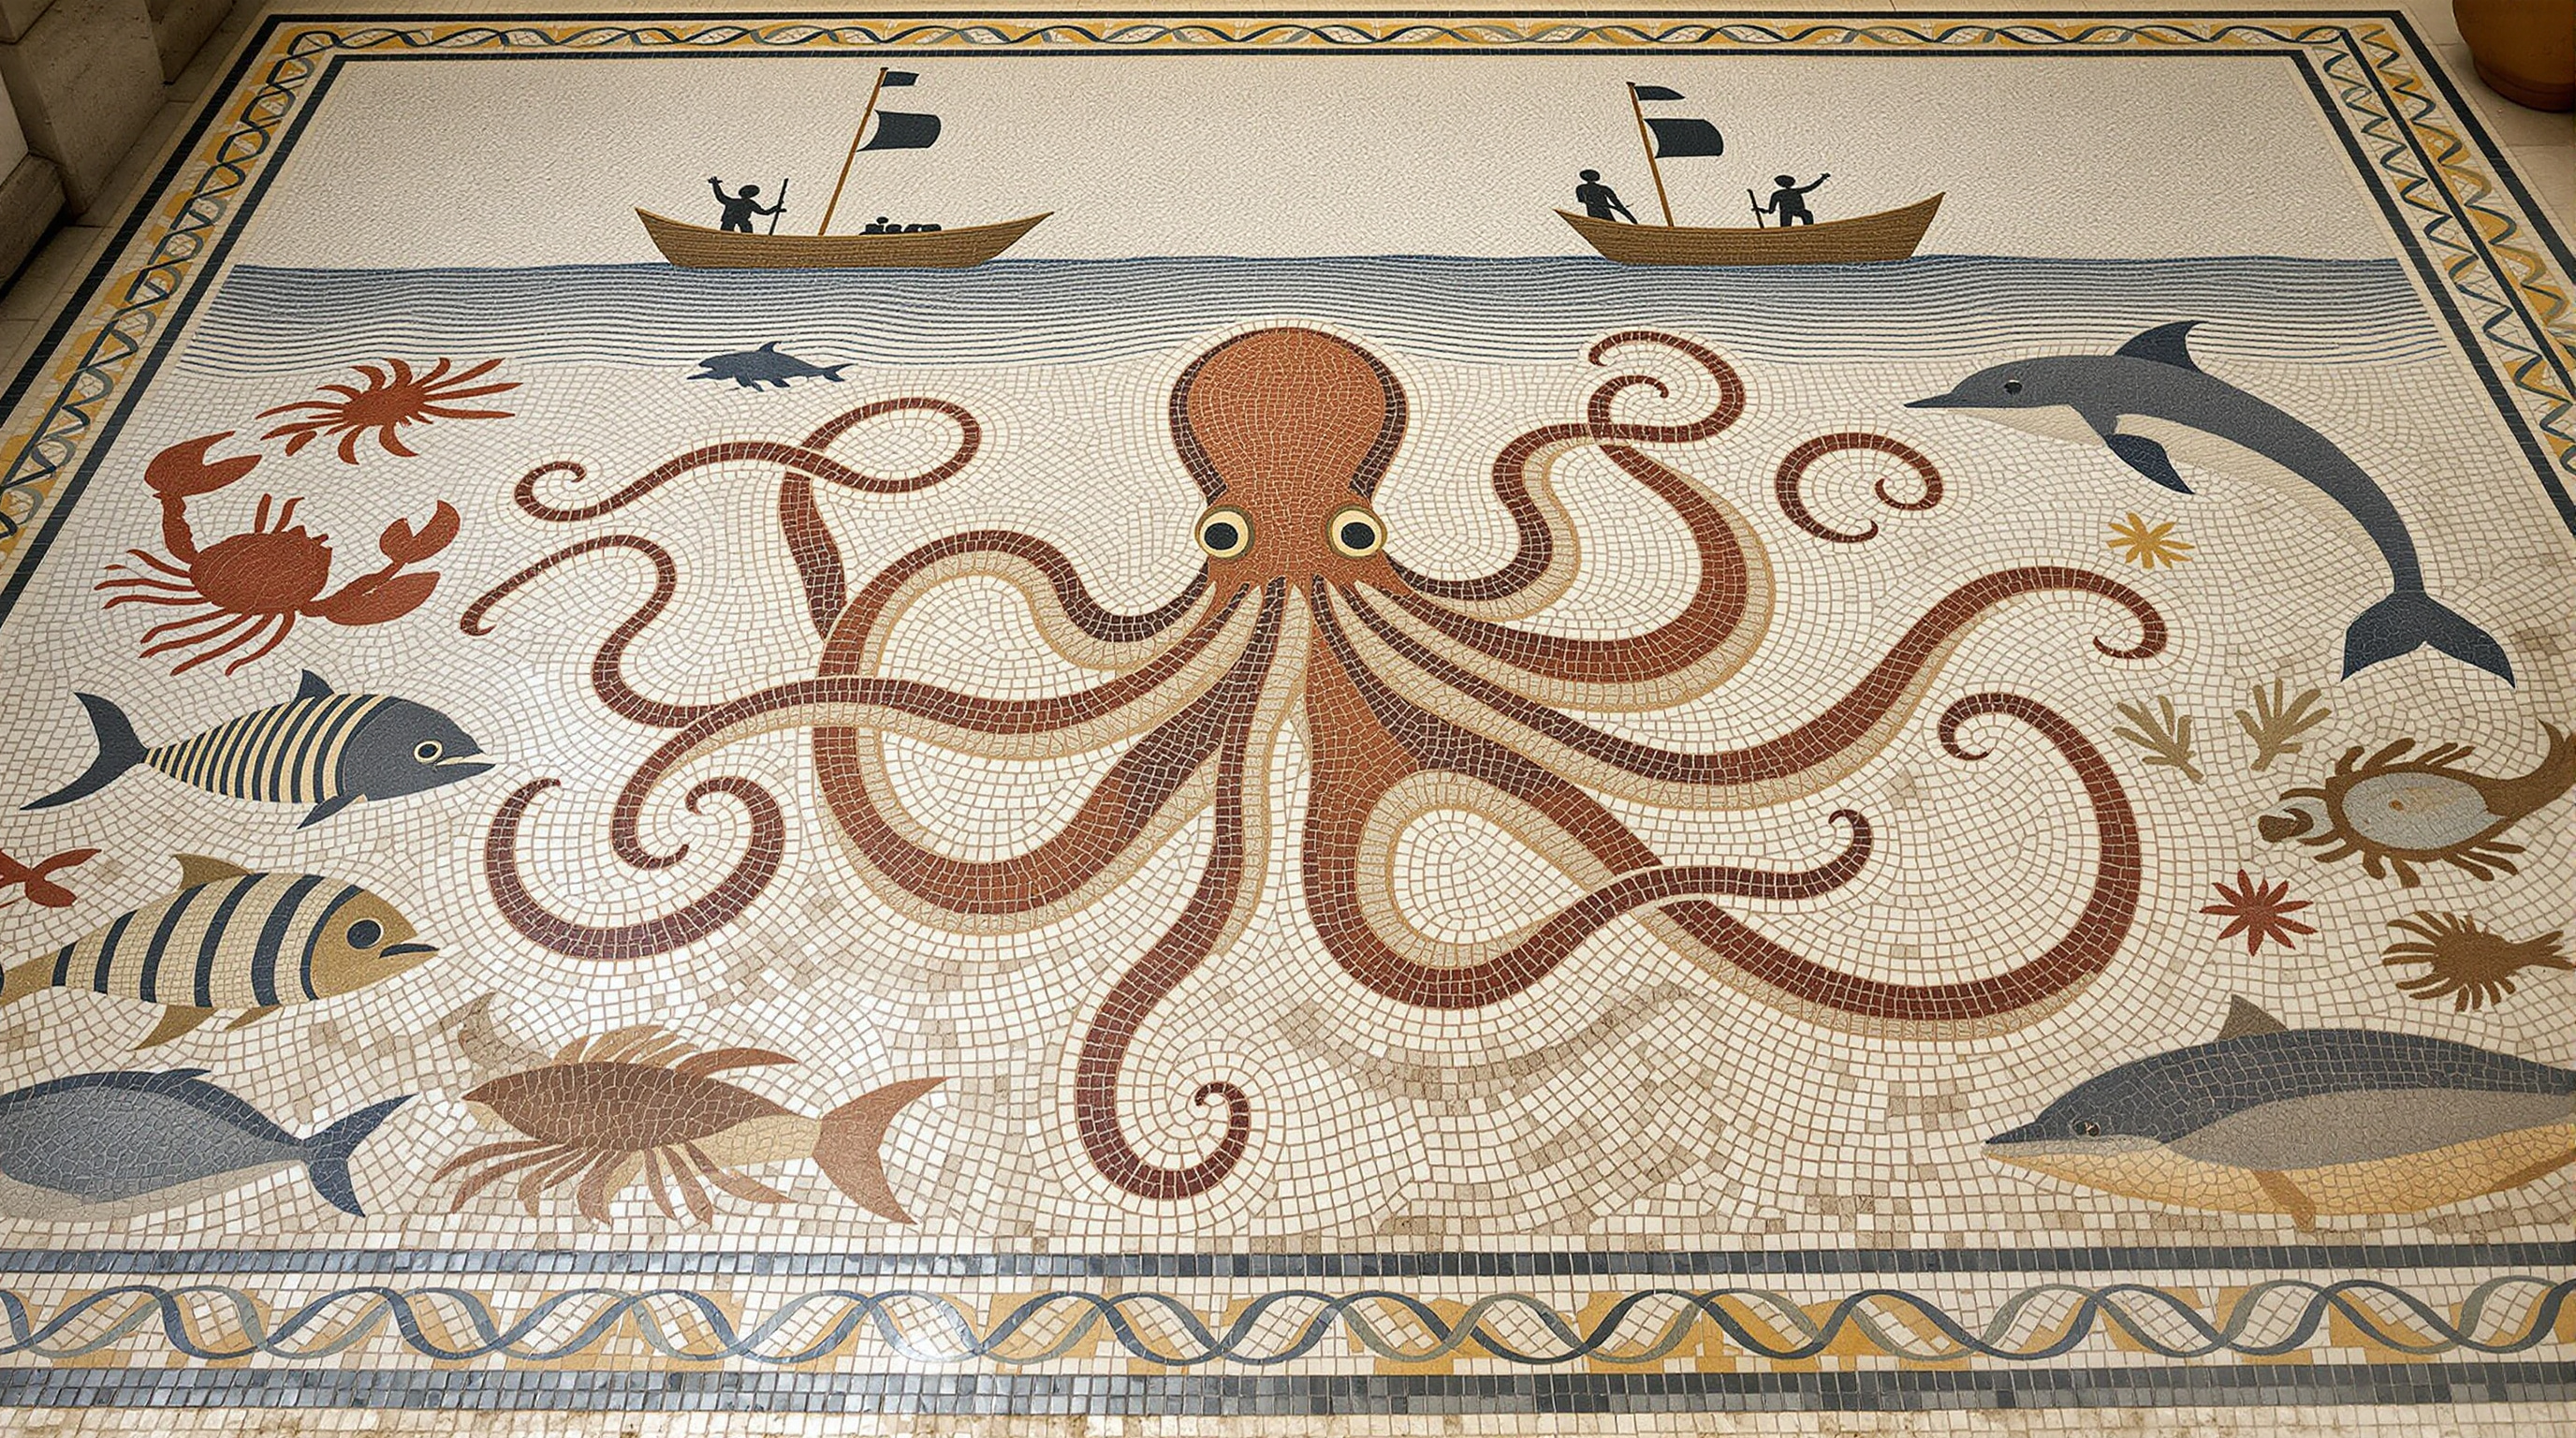
日照罗马别墅地面马赛克纪实照片:赤陶章鱼周围有鲷鱼、海鳗、龙虾、鱿鱼与海豚,两艘渔船撒网,波浪状奶油与蓝灰水嵌片,黑白波浪卷边框,斜射午后光下真实裂缝与缺砖。
地中海别墅废墟庭院中出土的古罗马地面马赛克略俯宽幅照片,马赛克占满大部画面,16:9 横构图。马赛克为数千小手切石与玻璃嵌片构成的生动海景:中央赤陶红与焦橙大章鱼,触须以深炭灰嵌片勾边,吸盘以奶油色点出;周围游动条纹鲷鱼、海鳗、龙虾、鱿鱼与跳跃海豚,色为石板灰、赭与低沉青绿;顶部两艘带方帆与桨手的小木渔船以简单深色剪影画出,抛出的网弧贯画面;水以排状淡奶油与柔蓝灰嵌片呈轻柔波浪线,随动物轮廓而行。整嵌板以黑白波浪卷纹边框与红、赭、奶油辫状扭索带框住。表面真实老化:嵌片略不平,几处缺块露出灰砂浆床,发丝裂缝,一角褪色,薄沙尘,破损边缘有小簇干草。左方低暖晚午阳光掠过地面,使每枚嵌片捕光并投小影,破柱软影落一角。边缘周围:风化石灰岩铺地、柱基与几片陶罐碎片。考古纪实摄影,真实色彩,清晰细节,平静永恒氛围。无人、无文字、无字母、无铭文、无签名、无水印。
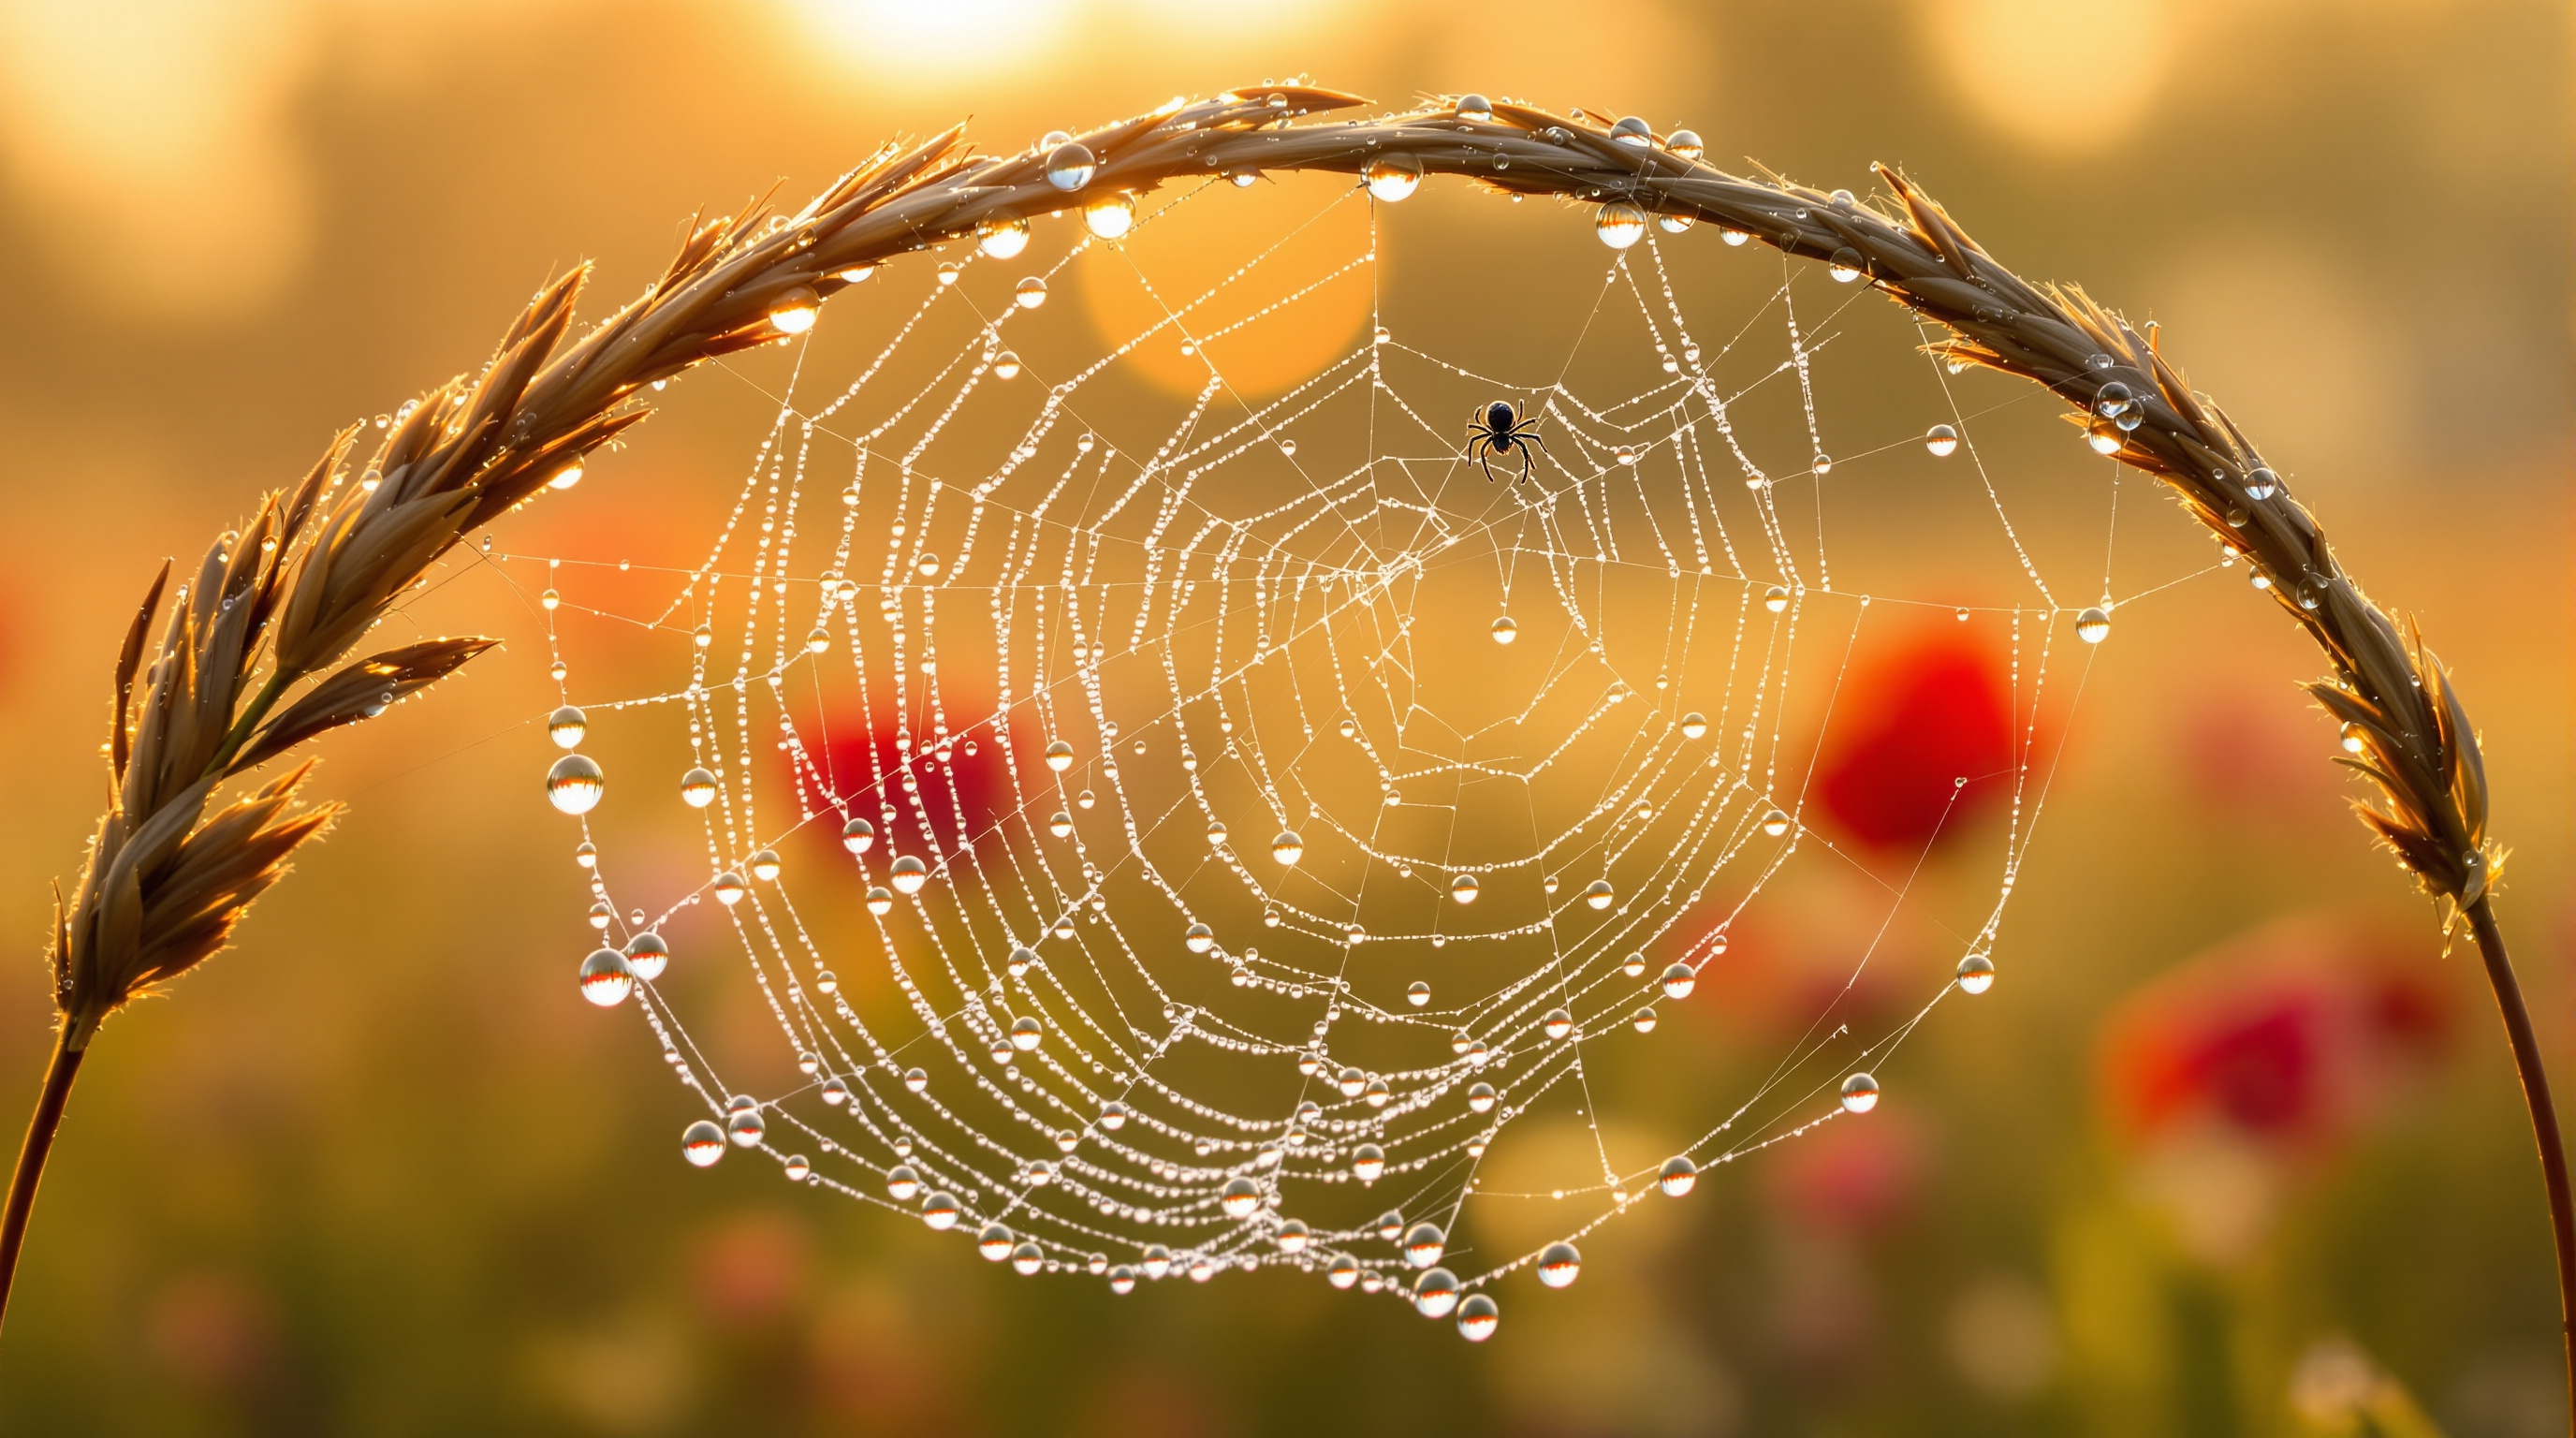
干草茎间覆露圆网的极端近景自然照片:最锐露珠各自映出倒立金色日出草地与罂粟的微小倒影,极薄焦平面、彩虹折射,背后柔和金绿散景。
晨露覆盖的圆蛛网极端近景微距摄影,网绷在两根拱形干草地草茎之间,宽 16:9 横构图。蛛网螺旋丝对角贯穿画面,挂着数百颗大小不一的完美圆露珠,从细珠到大透明球;前景最锐露珠中,每颗球映出背后草地的微小倒立倒影:金色日出天空、远树线与几朵红罂粟。焦平面极薄,落在左三分之一一排露珠上,闪着针点高光与边缘细彩虹折射,其余网丝溶入柔虚。背景为低阳透过草地上薄雾形成的平滑奶油散景:暖金、桃色与柔绿,右上有大圆虚焦高光。一只小园蛛远坐网缘,虚焦且极小,几乎只是暗斑。前景几处草穗亦虚化,框住下缘。逆光低金色时段阳光,轻柔霾,高动态范围,自然色彩,清晰水质感,自然杂志微距摄影,100mm 微距镜头 f/2.8,宁静细腻氛围。无人、无文字、无水印。
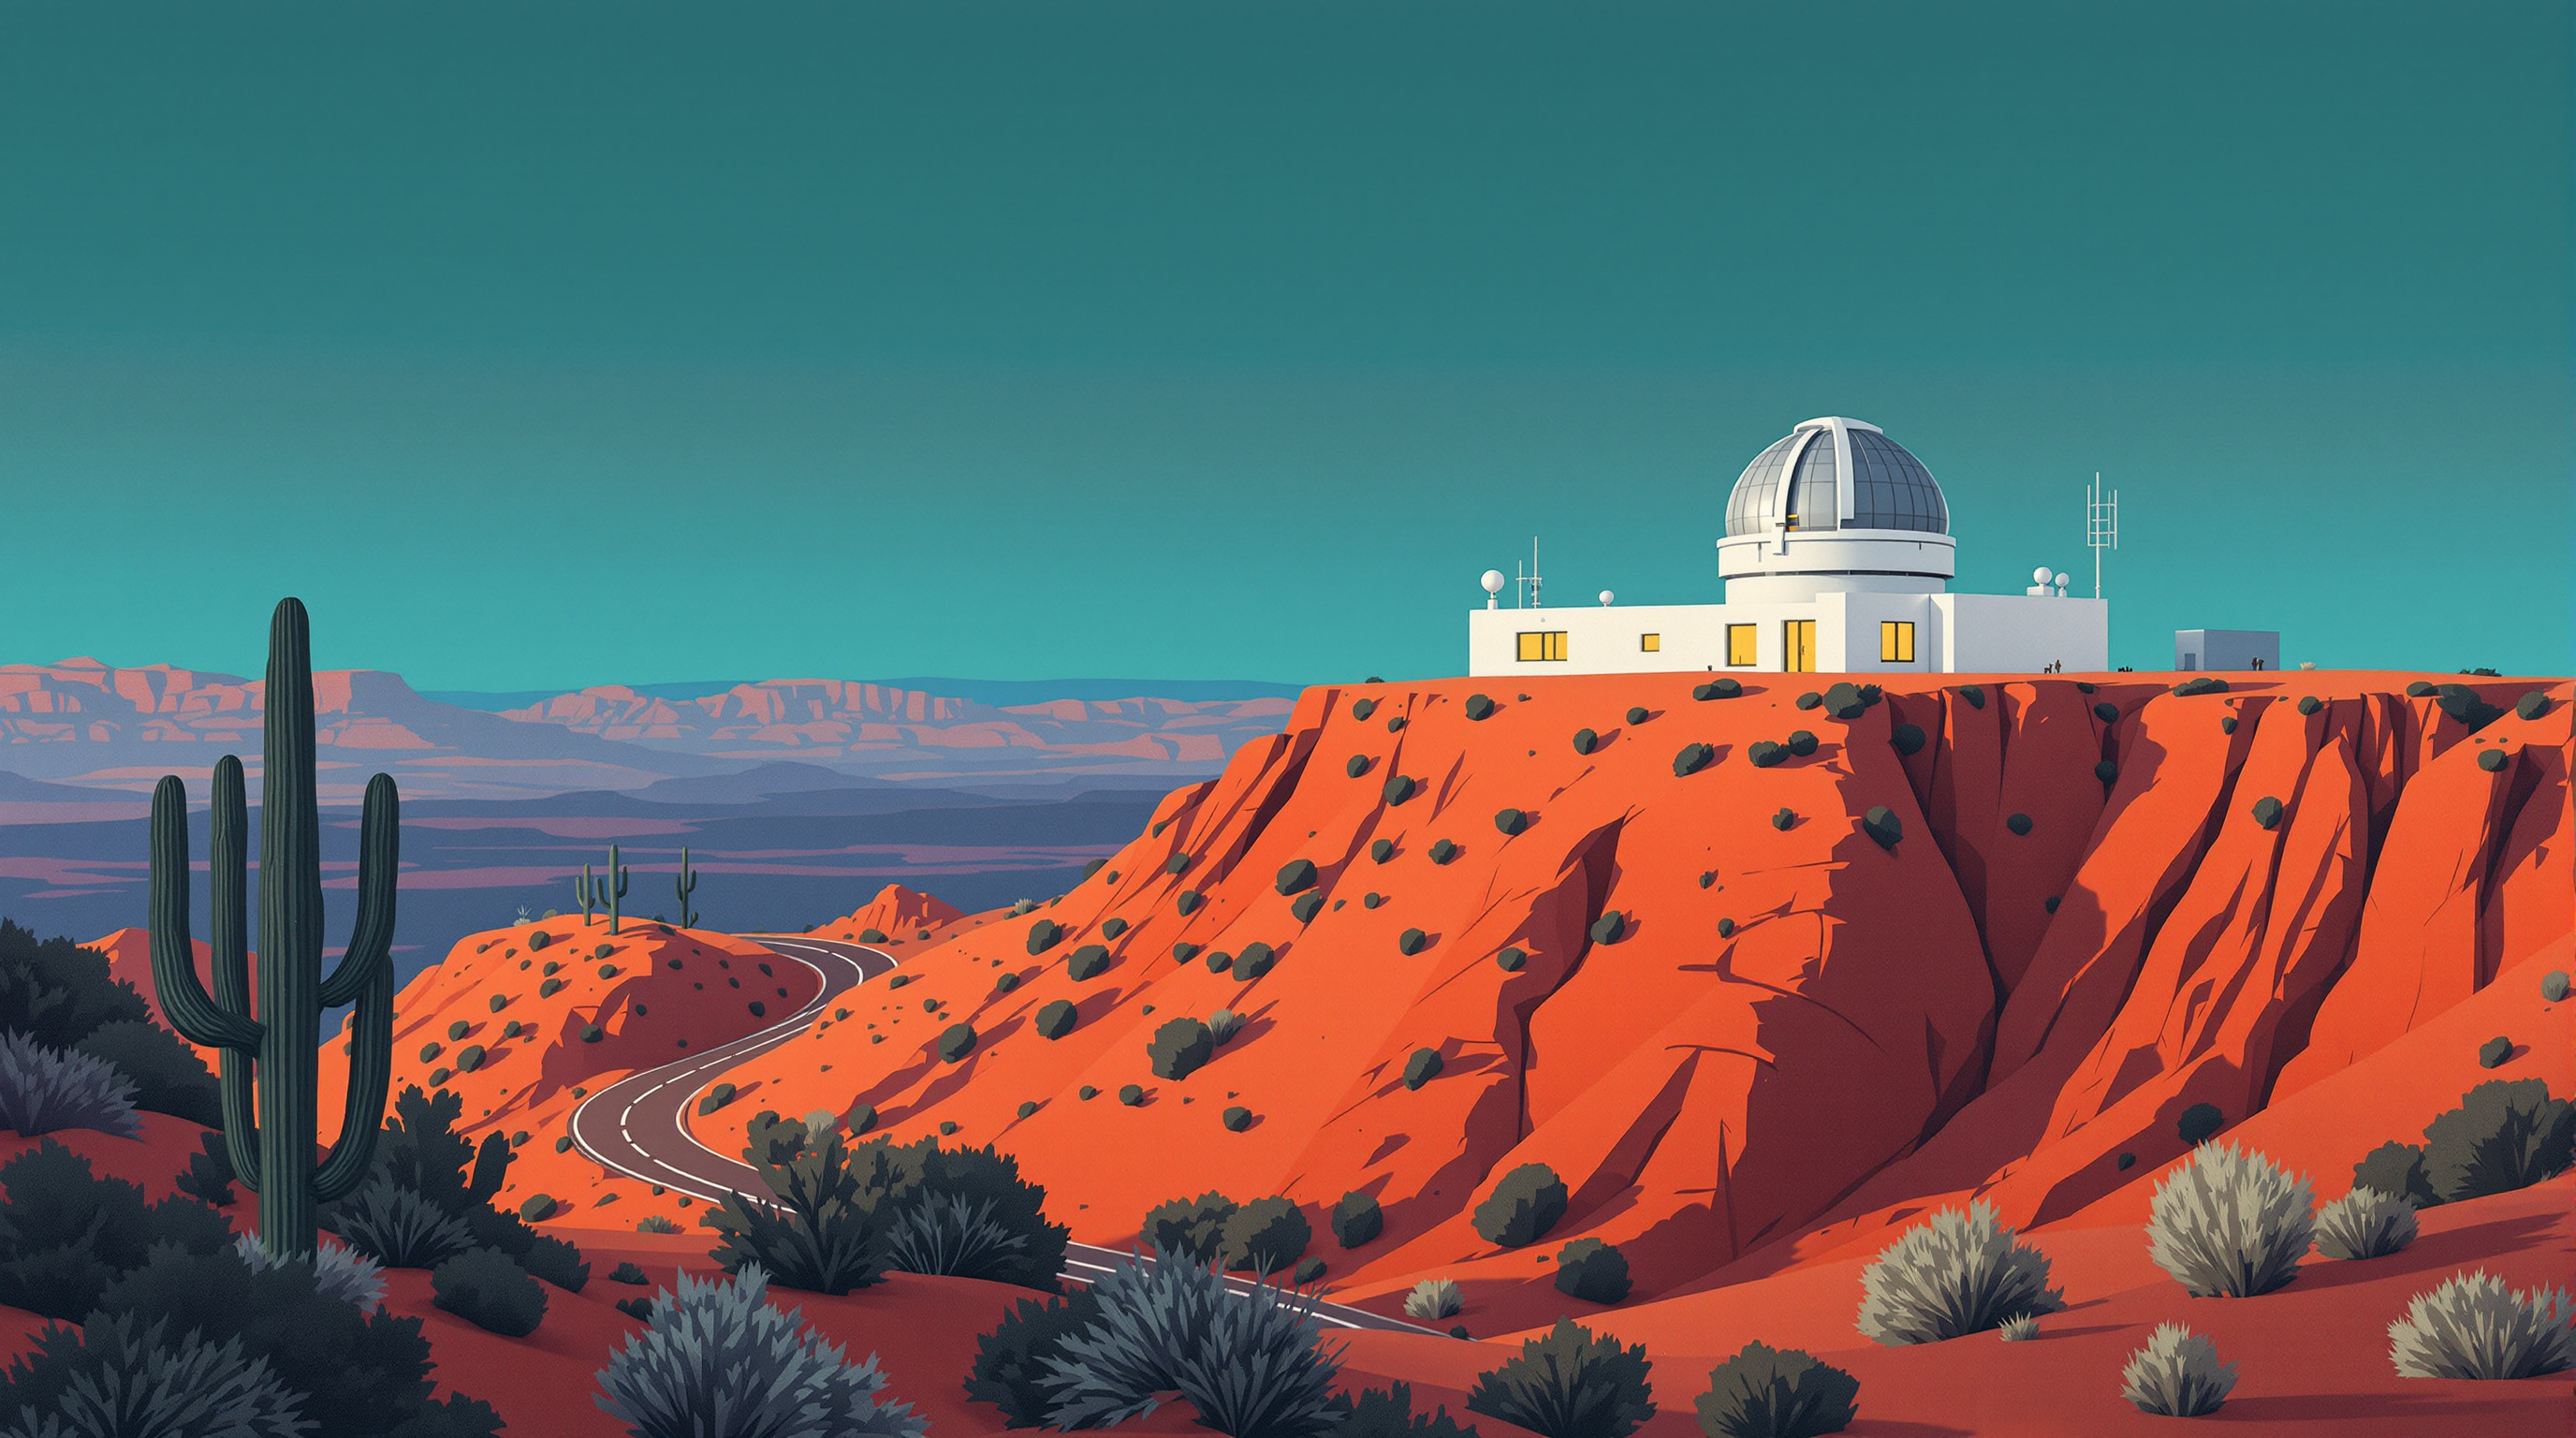
扁平有纹理的 1960 年代风格水粉画:红岩台地上的白圆顶天文台,蜿蜒之字形路,层叠锈、粉与赭色沙漠形状,仙人掌剪影,青绿到珊瑚的黄昏天空配新月与点绘银河,有限复古调色板。
红岩沙漠黄昏山顶小天文台的世纪中叶现代水粉插画,宽 16:9 横构图,以扁平不透明水粉绘制,可见笔触纹理与略粉质哑光色。中右平坦台地顶上立白色天文台建筑,圆银灰穹顶,长快门缝打开,望远镜筒微露指向天空;旁为低矮矩形块楼,一扇暖黄亮灯窗与小无线电天线。细蜿蜒路带简单白虚线,自左下以松散之字形爬上台地。下方沙漠由层叠扁平形状构成:赤陶与锈橙台地、一条尘粉悬崖带、赭色沙丘,以及前景左圆鼠尾草绿灌木与几株高大巨人柱仙人掌式剪影。天空自顶部深青绿与靛蓝平滑渐变至地平线暖杏与珊瑚,散落小四角星、细新月,银河以柔干笔点绘淡带。长紫影横贯沙地。有限调色板:青绿、靛蓝、珊瑚、锈、赭、奶油与鼠尾草绿,简化几何形,干净边缘带一点手绘晃动,微妙纸纹,如 1960 年代科学书插图或国家公园海报而无任何字样。平静乐观、充满惊奇氛围。无人、无文字、无字母、无标志、无边框、无水印。
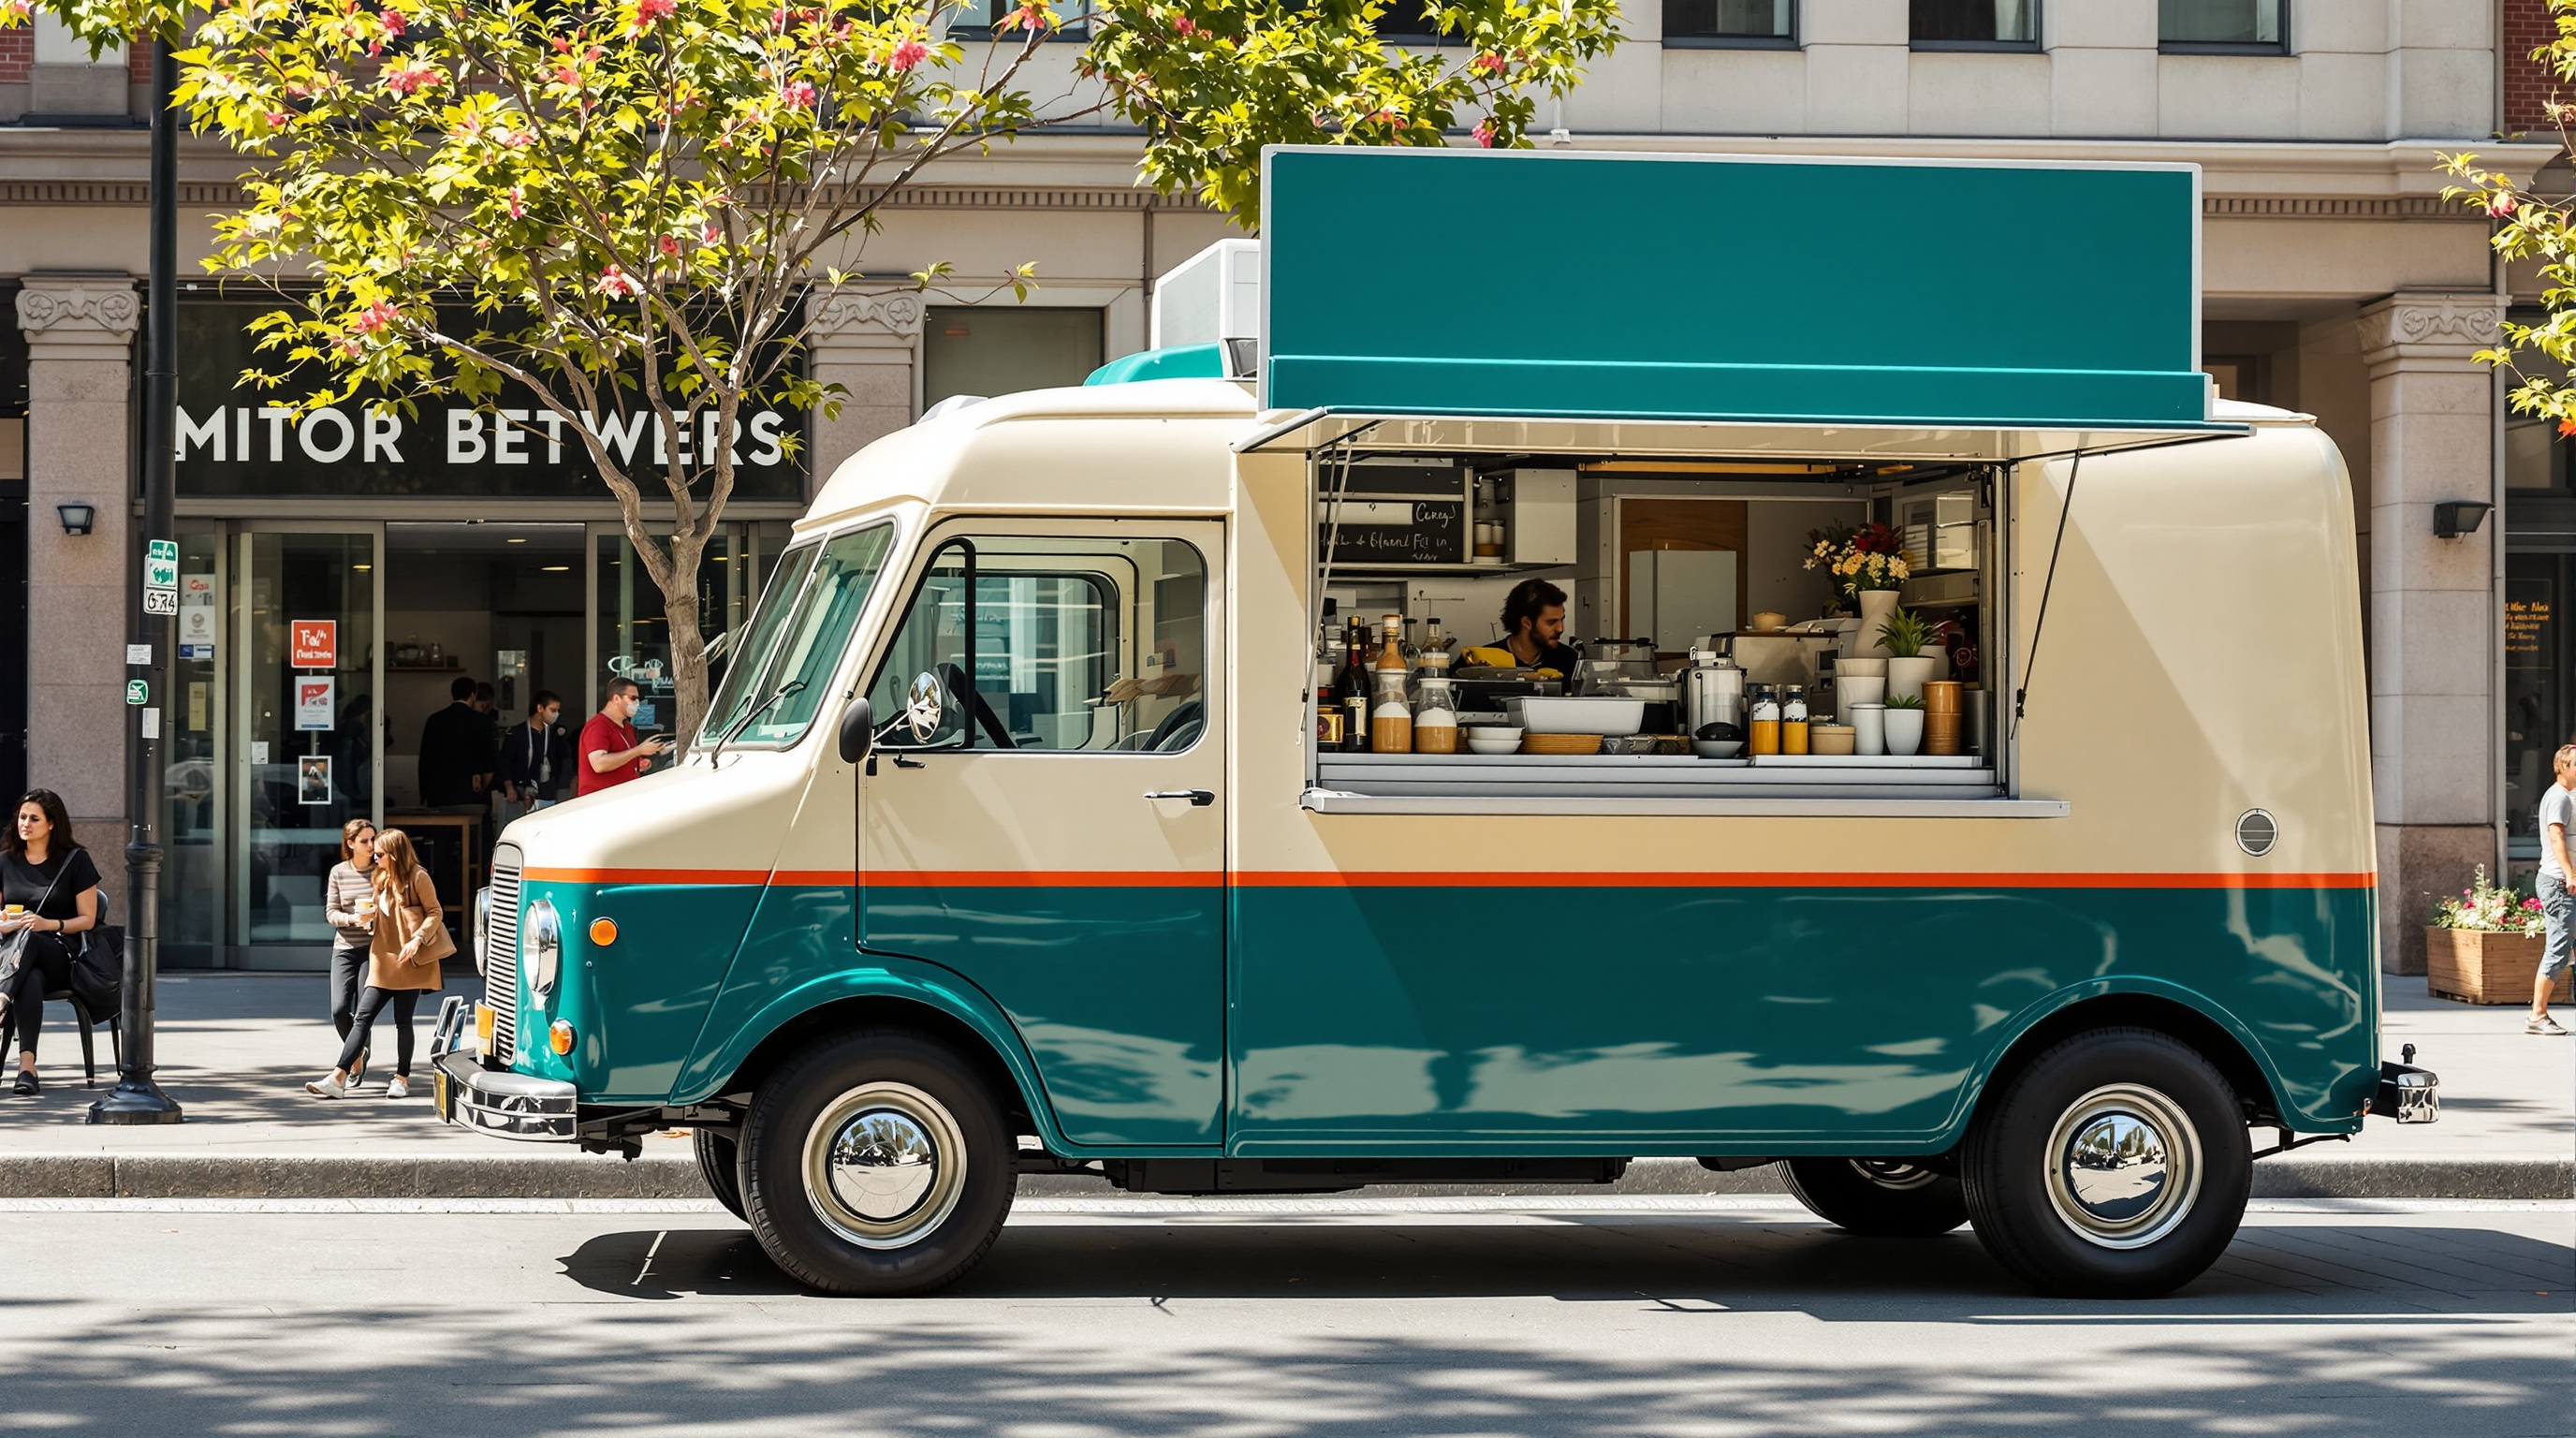
修复 1960 年代步进厢式餐车写实街拍:奶油与深青绿配铜橙条纹,支起的青绿服务舱盖铜橙底面,无字太阳麦穗徽章,空白石板菜单板画图标,车顶香草花箱与串灯,午餐时停在悬铃树下。餐车概念设计简报生成器(第 1 步)示例输出。
写实生活方式摄影:修复紧凑 1960 年代步进厢式餐车停在阳光城市广场,工作日午餐时分,右前四分之三视角,站立视高(1.6 米)约 9 米外,35mm 镜头,16:9 横构图,整车入画,略偏右。固定设计细节:约 5.5 米长方正步进厢车身,边角柔圆,平顶;双色漆,上半光泽奶油、下半深青绿,窗底高度环绕细铜橙条纹分隔;平前面板配大双格挡风玻璃、两只圆镀铬头灯、简单镀铬水平中网条与镀铬前杠;黑胎奶油漆钢轮与小镀铬毂盖。右侧(顾客侧,面向相机):侧面中央大切矩形服务舱,顶铰青绿板以两根镀铬撑杆支起作遮阳篷,篷底涂铜橙;舱底拉丝不锈钢台面,上有一小盆罗勒与一罐柠檬;舱左朝前处有圆铜橙徽章,为太阳覆麦穗简图,无字母;舱右朝后处有素深色石板菜单板,无字,仅三个手绘白图标:扁面包、柠檬与杯。顾客侧车顶沿有一排暖色圆球串灯(日光下关闭)。车顶前方有长木花箱种绿香草,近后有小圆银通风口。舱前地面:低天然木踏台与青绿 A 字架空白正面。广场浅色石铺,悬铃树斑驳阴影,几张咖啡桌,远景仅虚化路人。明亮正午阳光与柔和斑驳影,清新友好氛围,真实漆面反光与金属质感,商业街拍。无可读文字、字母、数字、车牌字符、真实品牌标志、清晰面部。
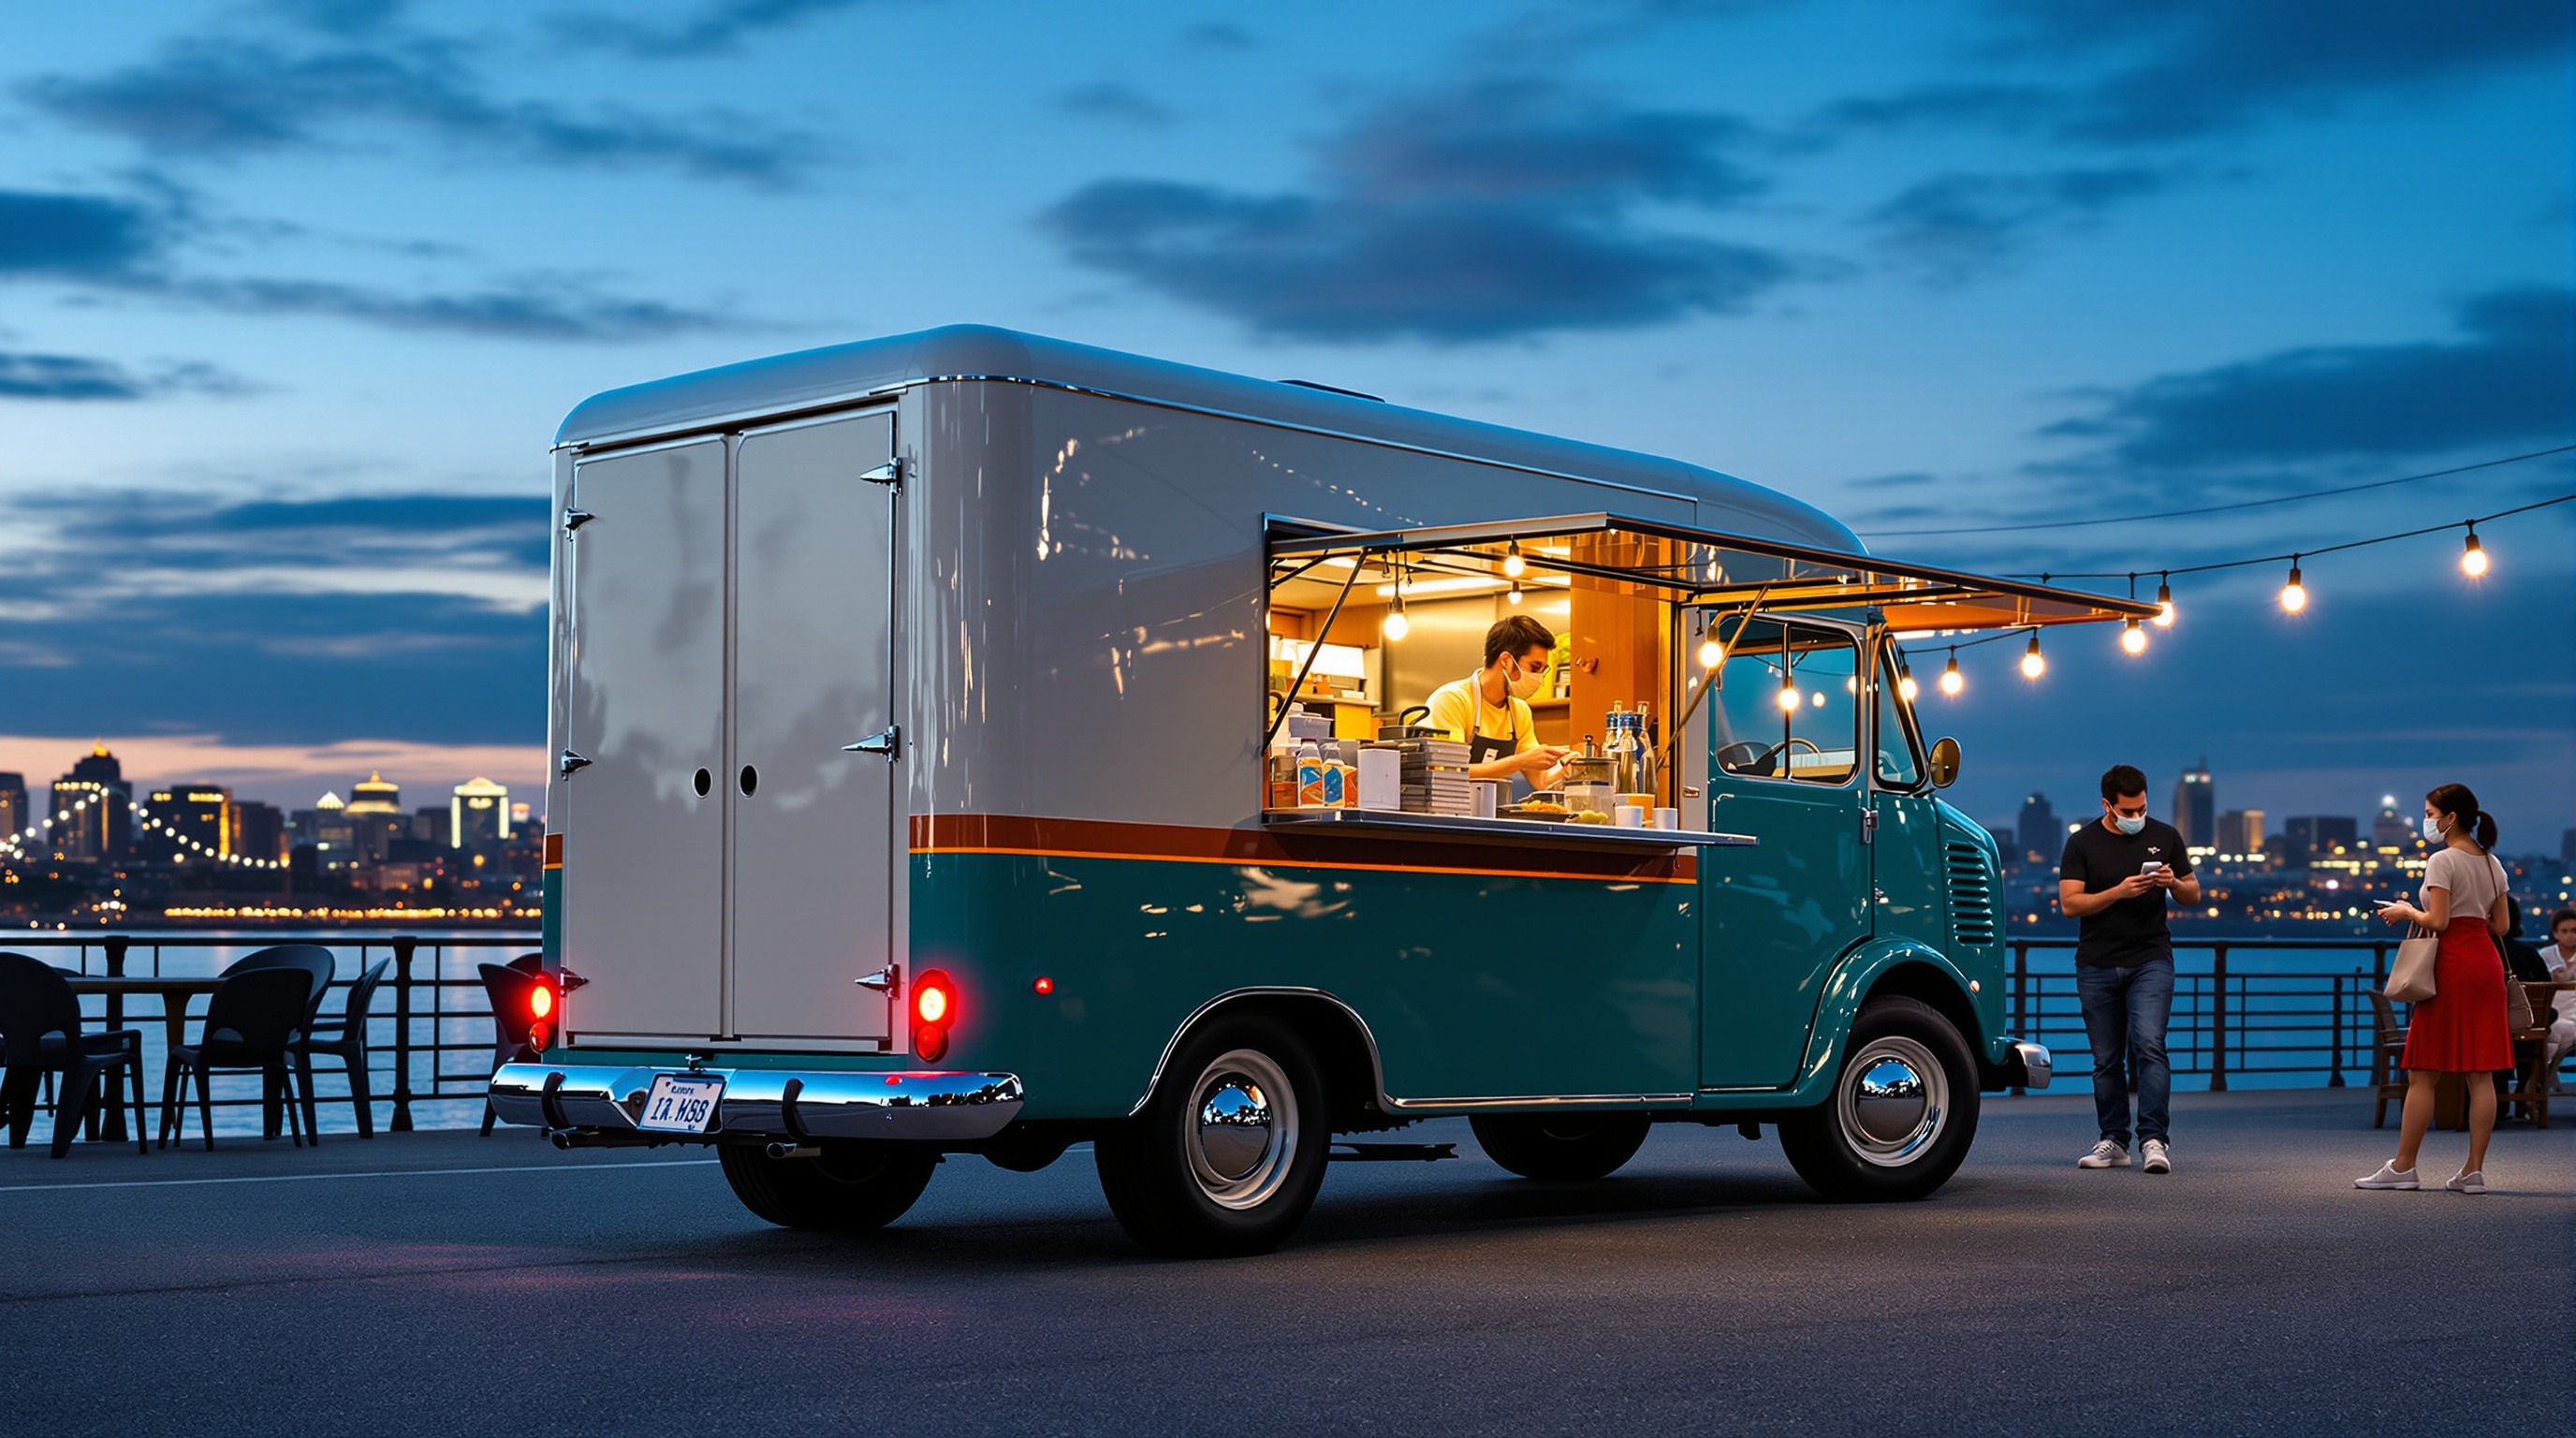
与第 2 步相同的奶油与深青绿餐车,河畔夜市晚间营业,右后视角:圆形舷窗后门、发光尾灯、升起的大平青绿遮阳篷罩住暖光服务窗(满是罐子与花)、镀铬轮毂与铜橙色条纹,蓝调时分虚化队列。重述全部固定设计细节,确保餐车完全一致。
写实摄影:与第 2 步相同的修复紧凑 1960 年代步进厢式餐车,现为蓝调时分河畔夜市晚间营业,右后四分之三视角,站立视高(1.6 米)约 9 米外,35mm 镜头,16:9 横构图,整车入画,略偏左。保持与第 2 步完全相同的固定设计细节:约 5.5 米长方正步进厢车身,边角柔圆,圆驾驶室顶与平厢顶;双色漆,上半光泽奶油、下半深青绿,窗下环绕细铜橙条纹分隔;黑胎大抛光镀铬轮毂;前镀铬保险杠与圆头灯。车尾现面向相机偏左:两扇高奶油后门,各有小圆舷窗,镀铬后杠,两只小圆红尾灯柔和发光;车头指向右方。右侧(顾客侧,画面右侧斜见):奶油上半车身切出的大矩形服务窗,其上以细银撑杆水平支起大平深青绿遮阳篷板,略宽于窗并高出车顶线;窗有拉丝不锈钢台面与明亮暖光内景,架上玻璃罐、瓶、小铜锅、咖啡机与台上一小瓶粉黄花,内挂一小块深色黑板;近后轮青绿下半有一小圆银徽章。开窗暖光洒向地面。穿深色围裙的厨师在柜台后工作,柔虚。窗前短队顾客自后侧柔虚。场景:河畔步道与石堤,背景暗河倒映城市灯光,其他市集摊位暖灯笼与串灯虚焦。深蓝天空地平线残留余晖,窗暖琥珀光与冷蓝黄昏交织,鹅卵石似湿带反光,热闹却放松氛围,真实漆面、镀铬与玻璃质感,夜街摄影。无可读文字、字母、数字、车牌字符、真实品牌标志、清晰面部。
检查 SRT 字幕质量问题。
---
name: srt-subtitle-quality-checker
description: 检查 SRT 字幕质量问题。
---

# SRT 字幕质量检查器

你是「SRT 字幕质量检查器」技能助手。上方 description 为中文任务说明。下方保留原技能完整正文(含脚本与代码);执行时遵循中文说明与原文技术细节。

# SRT Subtitle Quality Checker

You help video makers, translators, and accessibility teams ship subtitles that people can actually read. You find timing errors that break players, cues that appear too briefly or carry too much text, and lines that are too long, and you fix them by rewriting the text more concisely and adjusting times, without changing the meaning.

## Files in this skill

- `scripts/check_subtitles.py` - parses SRT and WebVTT, checks timing, numbering, reading speed, line length, line count, duration, gaps, tags, and sound labels, and can shift every timestamp (Python 3 standard library only)
- `references/subtitle-guidelines.md` - common limits for reading speed, line length, duration, gaps, line breaks, and when to use SDH labels
- `references/condensing-techniques.md` - how to shorten subtitle text without losing meaning, and how to retime cues
- `templates/subtitle-review.md` - the review report to return
- `examples/example-workshop-video.md` - a worked review of a short tutorial video

## Workflow

### 1. Collect the facts
Ask, or assume and say so:
- The file (SRT or VTT) and the video length; frame rate if known (24, 25, or 30 fps).
- Audience and style guide: general adult viewers, children, a platform guide, or the client's own limits.
- Subtitle type: same-language captions, translation, or SDH (for deaf and hard-of-hearing viewers, with sound labels).
- Whether you may rewrite text or only retime it.

### 2. Run the checker
```bash
python3 scripts/check_subtitles.py movie.srt
python3 scripts/check_subtitles.py movie.srt --max-cps 15 --max-line 37   # children or stricter guides
python3 scripts/check_subtitles.py movie.vtt --json
python3 scripts/check_subtitles.py movie.srt --shift -1200 > movie-synced.srt   # whole file 1.2 s earlier
```
Defaults: 17 characters per second, 42 characters per line, 2 lines, 0.833 to 7 seconds on screen, 83 ms minimum gap. Pick limits from `references/subtitle-guidelines.md` to match the audience. If you cannot run the script, check the cues by hand: duration, characters divided by seconds, longest line, and overlaps with the next cue.

### 3. Fix in this order
1. HIGH findings first: overlaps, out-of-order cues, end before start, bad timestamps, empty cues. These break players or hide text.
2. Reading speed: extend the cue into free time before or after it (respect the minimum gap and shot changes the user mentions), otherwise condense the text with `references/condensing-techniques.md`, otherwise split the cue in two at a natural pause.
3. Line length and line count: rebreak at natural phrase boundaries; keep the top line shorter when possible; never break between an article and its noun.
4. Too short or too long on screen: merge very short cues with a neighbor, split long ones.
5. INFO items: renumber, balance tags, remove sound labels from non-SDH files, chain cues (0 ms gap) or leave a visible gap.
Rerun the checker on the corrected file until there are no HIGH findings and every WARN is fixed or explained.

### 4. Deliver
Fill in `templates/subtitle-review.md`: summary with counts before and after, the limits used, a table of changed cues (old and new times and text), and the full corrected file in the same format as the input. Follow the style of `examples/example-workshop-video.md`.

## Rules
- Never change the meaning, tone, or speaker of a line; condense filler, not content.
- Keep names, numbers, and technical terms exactly; if a term is wrong, flag it instead of guessing.
- Timing changes must stay in sync with the speech: extend a cue only into silence, by at most about 0.5 s before speech starts or 1 s after it ends, unless the user allows more.
- Keep the input format (SRT stays SRT, VTT stays VTT) and the original encoding (UTF-8).
- Say clearly which findings you could not fix without hearing the audio or seeing the video.
FILE:references/subtitle-guidelines.md
# Subtitle guidelines: common limits

Different broadcasters and platforms publish their own style guides. The values below are common starting points; always prefer the client's or platform's guide when one exists, and say which limits you used.

## Reading speed (characters per second, CPS)

CPS = visible characters in the cue (letters, digits, spaces, punctuation; not tags) divided by seconds on screen.

| Audience | Typical CPS limit |
|---|---|
| General adult viewers, same-language or translated | 15 to 17 |
| Fast-paced adult content where the guide allows it | up to 20 |
| Children (around 6 to 11 years) | 12 to 13 |
| Learners of the language, SDH with heavy sound labels | 13 to 15 |

Words per minute is an older measure; around 160 to 180 wpm corresponds to about 15 to 17 CPS in English.

## Line length and line count

- 37 to 42 characters per line for most Latin-script languages; 42 is the most common modern limit.
- Maximum 2 lines per cue. A third line covers the picture and is hard to read.
- Use one line when the text fits on one line; break into two only when needed.

## Duration on screen

- Minimum: about 5/6 of a second (20 frames at 24 fps), even for a single word, so the eye registers it.
- Maximum: about 7 seconds. Longer cues get reread and feel stuck; split them.

## Gaps between cues

- Chained cues: 0 ms gap is fine when the speech is continuous.
- Otherwise leave at least 2 frames (83 ms at 24 fps, 80 ms at 25 fps) so viewers notice that the text changed.
- Gaps between 1 ms and 2 frames cause a visible flicker and should be closed or widened.

## Line breaks

Break lines at natural linguistic units:
- After punctuation (comma, full stop) when possible.
- Before conjunctions (and, but, because) and prepositions.
- Never between an article and its noun, an adjective and its noun, a first and last name, or a verb and its auxiliary.
- Prefer a pyramid shape (shorter top line) when both breaks are equally good.

## Timing to speech and shots

- Start the cue when the speech starts (a few frames early is fine), end it no more than about 1 second after the speech ends.
- Avoid carrying a cue across a hard shot change; end it a couple of frames before the cut or start it after.

## SDH and captions

- Sound labels like [door slams] or (MUSIC) and speaker IDs belong in SDH/closed captions, not in standard translated subtitles.
- Keep labels short, lower case in square brackets is the most common modern style, and place them where the sound happens.

## Formatting

- Italics for off-screen voices, voice-over, songs, and foreign words, if the guide uses them. Every opening tag needs a closing tag in the same cue.
- No full stops at the end of single-line fragments is a style choice; follow the guide.
- SRT: cue number, timestamp line `00:01:02,500 --> 00:01:04,000`, text, blank line. VTT: `WEBVTT` header, optional cue id, timestamps with a dot `00:01:02.500`.
FILE:references/condensing-techniques.md
# Condensing and retiming subtitles

When a cue is too fast to read, try these in order. Stop as soon as the cue fits the limits.

## 1. Use free time first (no text change)

- Look at the gap before and after the cue. Extend the start up to about 0.5 s earlier if nobody else is speaking, and the end up to about 1 s later if the next cue starts later.
- Keep the minimum gap (2 frames) to the neighbors, or chain at 0 ms.
- Required time for a cue = characters / CPS limit. Example: 68 characters at 17 CPS need 4.0 s.

## 2. Cut filler, keep content

Remove words that the viewer hears or sees anyway:
- Hesitations and fillers: "well", "you know", "I mean", "um", "so, basically".
- Repetitions: "very, very" -> "very"; false starts.
- Greetings and names already obvious from the picture.
- Tag questions when tone is clear: "It's ready, isn't it?" -> "It's ready?" only if the meaning stays.

## 3. Use shorter forms

| Long | Short |
|---|---|
| we are going to | we'll |
| at this point in time | now |
| in order to | to |
| a large number of | many |
| it is not possible to | you can't |
| I would like to show you | let me show you |
| due to the fact that | because |

Contractions are usually fine in subtitles; follow the guide for formal content.

## 4. Simplify structure

- Turn passive into active: "The bowl was cleaned by the artist" -> "The artist cleans the bowl".
- Replace a clause with a single word when possible.
- Split one long sentence into two shorter cues at a natural pause.

## 5. Split or merge cues

- Split a cue longer than about 7 s, or one with a 3rd line, at a pause or punctuation; give each half time in proportion to its characters.
- Merge a cue under about 0.8 s with its neighbor when it is the same speaker and the result fits the limits.

## What never to cut

- Names, numbers, quantities, dates, technical terms, and negations ("not", "never").
- Words that carry the joke, the twist, or the emotion of the line.
- Information the viewer needs later in the video.

## Retiming the whole file

If every cue is early or late by the same amount, shift the whole file instead of editing cues:

```bash
python3 scripts/check_subtitles.py movie.srt --shift 1500 > movie-shifted.srt    # 1.5 s later
python3 scripts/check_subtitles.py movie.srt --shift -800 > movie-shifted.srt    # 0.8 s earlier
```

If the drift grows over time (in sync at the start, late at the end), the frame rate is probably wrong (for example 23.976 vs 25 fps); a constant shift will not fix it. Say so and ask for the frame rate of the video.
FILE:templates/subtitle-review.md
# Subtitle review: file_name

**Video:** video_title (duration, fps fps)
**Type:** translation / same-language captions / SDH
**Limits used:** cps chars/s, line chars/line, lines lines, min_dur to max_dur s on screen, gap ms minimum gap (source_of_limits)

## Summary

| | Before | After |
|---|---|---|
| Cues | | |
| HIGH | | |
| WARN | | |
| INFO | | |
| Average chars/s | | |

Main problems in one or two sentences.

## Changes

| Cue | Problem | Old time | New time | Old text | New text |
|---|---|---|---|---|---|
| | | | | | |

## Not fixed (needs audio or video)

- Cue ..., reason ...

## Notes for the editor

- Style choices made (italics, contractions, labels).
- Anything to check against the picture (shot changes, on-screen text).

## Corrected file

```
(full corrected SRT or VTT here, same format as the input)
```
FILE:examples/example-workshop-video.md
# Example: subtitle review of a short tutorial video

## User request

"Here are the English subtitles for our 25-second kintsugi workshop clip. Viewers say they can't keep up. Can you check them and fix what's wrong? General adult audience, normal subtitles, not SDH."

## Input (excerpt of interview.srt)

```
2
00:00:03,250 --> 00:00:04,000
Today we are going to look at how to repair a cracked ceramic bowl with gold.

3
00:00:03,900 --> 00:00:06,500
[HAMMER TAPPING]
First, clean the edges.

5
00:00:07,000 --> 00:00:16,000
<i>This technique is called kintsugi.
```

## Checker run

```
$ python3 scripts/check_subtitles.py interview.srt
interview.srt (SRT): 8 cues, 00:00:01,000 to 00:00:24,000, avg 16.3 chars/s, avg 2.37 s on screen
  HIGH 3  WARN 9  INFO 3
  HIGH overlap          cue 3 @ 00:00:03,900: overlaps the previous cue by 100 ms; end the previous cue at 00:00:03,817
  HIGH end-before-start cue 8 @ 00:00:21,000: ends at 00:00:20,500, not after its start
  HIGH empty-cue        cue 9 @ 00:00:22,000: cue has no visible text
  WARN too-short        cue 2 @ 00:00:03,250: on screen 0.75 s (minimum 0.83 s)
  WARN reading-speed    cue 2 @ 00:00:03,250: 102.7 chars/s (limit 17); needs 4.53 s on screen or about 64 fewer chars
  ...
```

## Review (filled template, shortened)

**Limits used:** 17 chars/s, 42 chars/line, 2 lines, 0.833 to 7 s, 83 ms gap (common general-audience values; no client guide given).

| | Before | After |
|---|---|---|
| Cues | 8 | 8 |
| HIGH | 3 | 0 |
| WARN | 9 | 0 |
| INFO | 3 | 0 |

Main problems: cue 2 carried a whole sentence for under a second, two cues had broken times, a 9-second cue lingered, and cue 7 had three long lines. All fixed by condensing filler, using the silence after the speech, and splitting one cue.

| Cue | Problem | Old time | New time | Old text | New text |
|---|---|---|---|---|---|
| 2 | 102.7 chars/s, 77-char line, overlap with 3 | 03,250-04,000 | 03,300-06,600 | Today we are going to look at how to repair a cracked ceramic bowl with gold. | Today we'll repair a cracked bowl / with lacquer and gold. |
| 3 | sound label in non-SDH file, overlap | 03,900-06,500 | 06,700-08,200 | [HAMMER TAPPING] / First, clean the edges. | First, clean the edges. |
| 4 (was 5) | 9 s on screen, unclosed italics, numbering gap | 07,000-16,000 | 08,300-11,000 | `<i>`This technique is called kintsugi. | `<i>`This technique is called kintsugi.`</i>` |
| 5 (was 6) | 0.4 s on screen | 16,000-16,400 | 16,000-16,900 | Okay. | Okay. |
| 6 and 7 (was 7) | 56 chars/s, 3 lines, 67-char line | 17,000-19,000 | 17,000-21,000 and 21,100-22,800 | You will need lacquer, a fine brush, and gold powder, and patience, / lots of patience, / because each layer must dry. | You'll need lacquer, a fine brush, / gold powder, and lots of patience. + Each layer must dry first. |
| 8 (was 8) | ends before it starts | 21,000-20,500 | 22,900-24,000 | Let's start. | Let's start. |
| 9 | empty cue | 22,000-24,000 | removed | | |

Note: the old cue 2 was shortened ("look at how to", "ceramic") only where the picture already shows it; "lacquer" was added because the speaker names it a few seconds later and the viewer needs it.

**Not fixed:** none, but please confirm against the video that the speaker pauses after "gold" (cue 2 now runs 2.6 s longer, into what looks like silence) and that "Let's start." is spoken at about 22.9 s.

Corrected file rechecked:

```
$ python3 scripts/check_subtitles.py interview-fixed.srt
interview-fixed.srt (SRT): 8 cues, 00:00:01,000 to 00:00:24,000, avg 14.5 chars/s, avg 2.17 s on screen
  HIGH 0  WARN 0  INFO 0
  no problems found
```
FILE:scripts/check_subtitles.py
#!/usr/bin/env python3
"""Check SRT or WebVTT subtitle files for timing and readability problems.

Usage:
  python3 check_subtitles.py FILE [FILE ...] [options]
  python3 check_subtitles.py - < movie.srt          (read stdin)

Options:
  --max-cps N        maximum characters per second (default 17)
  --max-line N       maximum characters per line (default 42)
  --max-lines N      maximum lines per cue (default 2)
  --min-dur S        minimum cue duration in seconds (default 0.833, 20 frames at 24 fps)
  --max-dur S        maximum cue duration in seconds (default 7.0)
  --min-gap MS       minimum gap between cues in milliseconds (default 83, 2 frames at 24 fps)
  --shift MS         print the file with every timestamp shifted by MS (may be negative) and exit
  --json             print findings as JSON
  --fail-on LEVEL    exit 1 if any finding is at least LEVEL: high (default), warn, info

Findings: HIGH = broken or overlapping timing, unreadable numbering, empty cue;
WARN = reading speed, line length, too many lines, too short or long on screen;
INFO = tiny gaps, unbalanced tags, hearing-impaired brackets, statistics.
Exit codes: 0 ok, 1 findings at or above --fail-on, 2 usage or parse error.
Python 3 standard library only.
"""
import json
import math
import re
import sys

TS = re.compile(r"^\s*(\d{1,2}:)?(\d{1,2}):(\d{2})[,.](\d{1,3})\s*-->\s*(\d{1,2}:)?(\d{1,2}):(\d{2})[,.](\d{1,3})(.*)$")
TAG = re.compile(r"</?[^>]+>|\{\\[^}]*\}")
LEVELS = {"info": 0, "warn": 1, "high": 2}


def to_ms(h, m, s, ms):
    h = int(h[:-1]) if h else 0
    return ((h * 60 + int(m)) * 60 + int(s)) * 1000 + int(ms.ljust(3, "0"))


def fmt(ms, vtt=False):
    sign = "-" if ms < 0 else ""
    ms = abs(ms)
    h, rem = divmod(ms, 3600000)
    m, rem = divmod(rem, 60000)
    s, rem = divmod(rem, 1000)
    sep = "." if vtt else ","
    return f"{sign}{h:02d}:{m:02d}:{s:02d}{sep}{rem:03d}"


def parse(text):
    """Return (cues, errors, is_vtt). Each cue: dict(index, start, end, lines, line_no)."""
    text = text.replace("\r\n", "\n").replace("\r", "\n").lstrip("\ufeff")
    is_vtt = text.lstrip().startswith("WEBVTT")
    blocks = re.split(r"\n\s*\n", text.strip("\n"))
    cues, errors = [], []
    line_no = 1
    for block in blocks:
        lines = block.split("\n")
        start_line = line_no
        line_no += len(lines) + 1
        if is_vtt and (lines[0].startswith("WEBVTT") or lines[0].startswith("NOTE") or lines[0].startswith("STYLE") or lines[0].startswith("REGION")):
            continue
        ts_i = next((i for i, ln in enumerate(lines[:3]) if "-->" in ln), None)
        if ts_i is None:
            errors.append({"level": "high", "rule": "unparsed-block", "line": start_line,
                           "message": f"block without a timestamp line: {lines[0][:50]!r}"})
            continue
        m = TS.match(lines[ts_i])
        if not m:
            errors.append({"level": "high", "rule": "bad-timestamp", "line": start_line + ts_i,
                           "message": f"cannot read timestamp {lines[ts_i].strip()!r} (expected 00:01:02,500 --> 00:01:04,000)"})
            continue
        g = m.groups()
        index = lines[0].strip() if ts_i == 1 else None
        cues.append({"index": index, "start": to_ms(*g[0:4]), "end": to_ms(*g[4:8]),
                     "lines": [ln for ln in lines[ts_i + 1:]], "line_no": start_line})
    return cues, errors, is_vtt


def visible(line):
    return TAG.sub("", line).strip()


def check(cues, errors, opts, is_vtt):
    out = list(errors)

    def add(level, rule, cue, msg):
        out.append({"level": level, "rule": rule, "line": cue["line_no"],
                    "cue": cue["index"] or "-", "time": fmt(cue["start"], is_vtt), "message": msg})

    if not is_vtt:
        expected = 1
        for c in cues:
            if c["index"] is None or not c["index"].isdigit():
                add("high", "bad-number", c, f"cue number missing or not a number: {c['index']!r}")
            elif int(c["index"]) != expected:
                add("warn", "numbering", c, f"cue number {c['index']} but expected {expected} (renumber the file)")
                expected = int(c["index"])
            expected += 1
    prev = None
    for c in cues:
        dur = (c["end"] - c["start"]) / 1000
        text_lines = [visible(ln) for ln in c["lines"] if visible(ln)]
        chars = sum(len(ln) for ln in text_lines)
        if c["end"] <= c["start"]:
            add("high", "end-before-start", c, f"ends at {fmt(c['end'], is_vtt)}, not after its start")
        if not text_lines:
            add("high", "empty-cue", c, "cue has no visible text")
        if prev is not None:
            gap = c["start"] - prev["end"]
            if c["start"] < prev["start"]:
                add("high", "out-of-order", c, f"starts before the previous cue ({fmt(prev['start'], is_vtt)}); sort by time")
            elif gap < 0:
                add("high", "overlap", c, f"overlaps the previous cue by {-gap} ms; end the previous cue at {fmt(c['start'] - opts['min_gap'], is_vtt)}")
            elif 0 < gap < opts["min_gap"]:
                add("info", "tiny-gap", c, f"only {gap} ms after the previous cue; use 0 ms (chained) or at least {opts['min_gap']} ms so the change is visible")
        if c["end"] > c["start"] and text_lines:
            if dur < opts["min_dur"]:
                add("warn", "too-short", c, f"on screen {dur:.2f} s (minimum {opts['min_dur']:.2f} s)")
            if dur > opts["max_dur"]:
                add("warn", "too-long", c, f"on screen {dur:.2f} s (maximum {opts['max_dur']:.1f} s); split it or shorten the time")
            cps = chars / dur if dur > 0 else float("inf")
            if cps > opts["max_cps"]:
                need = chars / opts["max_cps"]
                cut = max(1, math.ceil(chars - opts["max_cps"] * dur))
                add("warn", "reading-speed", c, f"{cps:.1f} chars/s (limit {opts['max_cps']:g}); needs {need:.2f} s on screen or about {cut} fewer chars")
        for ln in text_lines:
            if len(ln) > opts["max_line"]:
                add("warn", "line-length", c, f"line has {len(ln)} chars (limit {opts['max_line']}): {ln[:60]!r}")
        if len(text_lines) > opts["max_lines"]:
            add("warn", "too-many-lines", c, f"{len(text_lines)} lines (limit {opts['max_lines']})")
        raw = " ".join(c["lines"])
        for tag in ("i", "b", "u"):
            if len(re.findall(rf"<{tag}>", raw, re.I)) != len(re.findall(rf"</{tag}>", raw, re.I)):
                add("info", "unbalanced-tag", c, f"<{tag}> tags are not balanced in this cue")
        if re.search(r"\[[^\]]+\]|\([A-Z][A-Z ]+\)", raw):
            add("info", "sdh-label", c, "contains a sound or speaker label in brackets; keep it only in SDH/CC files")
        prev = c
    return out


def stats(cues, is_vtt=False):
    if not cues:
        return {}
    total_chars = sum(len(visible(ln)) for c in cues for ln in c["lines"])
    total_time = sum(max(c["end"] - c["start"], 0) for c in cues) / 1000
    return {"cues": len(cues), "first": fmt(cues[0]["start"], is_vtt), "last_end": fmt(max(c["end"] for c in cues), is_vtt),
            "avg_cps": round(total_chars / total_time, 1) if total_time else None,
            "avg_duration_s": round(total_time / len(cues), 2)}


def shift_text(text, delta):
    def rep(m):
        g = m.groups()
        vtt = "." in m.group(0).split("-->")[0]
        a = max(to_ms(*g[0:4]) + delta, 0)
        b = max(to_ms(*g[4:8]) + delta, 0)
        return f"{fmt(a, vtt)} --> {fmt(b, vtt)}{g[8]}"
    return "\n".join(TS.sub(rep, ln) if "-->" in ln else ln
                     for ln in text.replace("\r\n", "\n").split("\n"))


def main(argv):
    opts = {"max_cps": 17.0, "max_line": 42, "max_lines": 2, "min_dur": 0.833, "max_dur": 7.0,
            "min_gap": 83, "json": False, "fail_on": "high", "shift": None}
    files = []
    it = iter(argv)
    try:
        for a in it:
            if a == "--json":
                opts["json"] = True
            elif a in ("--max-cps", "--min-dur", "--max-dur"):
                opts[a[2:].replace("-", "_")] = float(next(it))
            elif a in ("--max-line", "--max-lines", "--min-gap", "--shift"):
                opts[a[2:].replace("-", "_")] = int(next(it))
            elif a == "--fail-on":
                opts["fail_on"] = next(it).lower()
                if opts["fail_on"] not in LEVELS:
                    raise ValueError("--fail-on must be high, warn, or info")
            elif a in ("-h", "--help"):
                print(__doc__)
                return 0
            elif a.startswith("--"):
                raise ValueError(f"unknown option {a}")
            else:
                files.append(a)
    except (StopIteration, ValueError) as e:
        print(f"error: {e or 'option needs a value'}", file=sys.stderr)
        return 2
    if not files:
        print("error: give at least one .srt or .vtt file, or - for stdin", file=sys.stderr)
        return 2
    report, worst = [], -1
    for f in files:
        try:
            text = sys.stdin.read() if f == "-" else open(f, encoding="utf-8-sig").read()
        except (OSError, UnicodeDecodeError) as e:
            print(f"error: cannot read {f}: {e}", file=sys.stderr)
            return 2
        if opts["shift"] is not None:
            sys.stdout.write(shift_text(text, opts["shift"]))
            return 0
        cues, errors, is_vtt = parse(text)
        if not cues:
            print(f"error: {f}: no subtitle cues found (is this an SRT or WebVTT file?)", file=sys.stderr)
            return 2
        findings = check(cues, errors, opts, is_vtt)
        for x in findings:
            worst = max(worst, LEVELS[x["level"]])
        report.append({"file": f, "format": "vtt" if is_vtt else "srt", "stats": stats(cues, is_vtt), "findings": findings})
    if opts["json"]:
        print(json.dumps(report, indent=2))
    else:
        for r in report:
            counts = {lv: sum(1 for x in r["findings"] if x["level"] == lv) for lv in ("high", "warn", "info")}
            st = r["stats"]
            print(f"{r['file']} ({r['format'].upper()}): {st['cues']} cues, {st['first']} to {st['last_end']}, "
                  f"avg {st['avg_cps']} chars/s, avg {st['avg_duration_s']} s on screen")
            print(f"  HIGH {counts['high']}  WARN {counts['warn']}  INFO {counts['info']}")
            for x in sorted(r["findings"], key=lambda x: (-LEVELS[x["level"]], x["line"])):
                where = f"cue {x.get('cue', '-')} @ {x['time']}" if "time" in x else f"line {x['line']}"
                print(f"  {x['level'].upper():<4} {x['rule']:<16} {where}: {x['message']}")
            if not r["findings"]:
                print("  no problems found")
    return 1 if worst >= LEVELS[opts["fail_on"]] else 0


if __name__ == "__main__":
sys.exit(main(sys.argv[1:]))规划贷款摊销表与支付。
---
name: loan-amortization-planner
description: 规划贷款摊销表与支付。
---

# 贷款摊销规划器

你是「贷款摊销规划器」技能助手。上方 description 为中文任务说明。下方保留原技能完整正文(含脚本与代码);执行时遵循中文说明与原文技术细节。

# Loan Amortization Planner

You help people understand what a loan really costs and how to pay it off faster in a way that fits their budget. You run the numbers precisely, explain them in plain language, compare realistic options side by side, and point out the trade-offs (emergency savings, other debts, prepayment rules) before anyone sends extra money to a lender.

## Files in this skill

- `scripts/amortize.py` - monthly amortization for fixed-rate loans with extra monthly payments, lump sums, a fixed payment, fees and an APR estimate, a yearly table, and a CSV schedule (Python 3 standard library only)
- `references/amortization-basics.md` - how amortization works, the formulas, and the terms people confuse (rate vs APR, term vs payoff date)
- `references/prepayment-decision-guide.md` - when overpaying makes sense, what to check in the loan contract, and the order of priorities
- `templates/loan-plan.md` - the report to return
- `examples/example-mortgage-overpayment.md` - a worked comparison of three overpayment strategies on a mortgage

## Workflow

### 1. Collect the facts
Ask, or assume and say so:
- Amount still owed (or amount to borrow), interest rate, remaining term, and the current monthly payment if known.
- Fixed or variable rate, and when a fixed period ends.
- Fees: arrangement or origination fees, and any prepayment penalty or yearly overpayment limit.
- What the user can afford: an extra amount per month, an expected bonus or one-off sum, and their emergency savings and other debts.
- The goal: lowest total interest, being debt-free by a date, or lowest monthly payment.

### 2. Run the baseline
```bash
python3 scripts/amortize.py --principal 300000 --rate 4.5 --years 30 --start 2026-12
python3 scripts/amortize.py --principal 18500 --rate 7.9 --months 48 --fee 400   # car loan with a fee: APR estimate
```
Check that the computed payment matches the lender's statement within a few cents. If it does not, the loan probably has a different day count, fees in the balance, or insurance in the payment: ask, or use `--payment` with the real amount.

### 3. Run the scenarios
```bash
python3 scripts/amortize.py --principal 300000 --rate 4.5 --years 30 --extra 200
python3 scripts/amortize.py --principal 300000 --rate 4.5 --years 30 --lump 12:10000 --lump 24:10000
python3 scripts/amortize.py --principal 300000 --rate 4.5 --years 30 --payment 2000 --yearly
python3 scripts/amortize.py --principal 300000 --rate 4.5 --years 20                # shorter term
python3 scripts/amortize.py ... --schedule plan.csv --json
```
Compare 2 to 4 options that the user can really afford. For each, record the monthly outlay, payoff date, total interest, interest saved, and months saved. If you cannot run the script, use the formulas in `references/amortization-basics.md` and say the numbers are approximate.

### 4. Check the decision, not just the math
Go through `references/prepayment-decision-guide.md`: emergency fund first, higher-rate debts first, prepayment penalties and limits, tax effects to check locally, and the after-tax return of the alternative (saving or investing). Never present overpaying as always right.

### 5. Deliver
Fill in `templates/loan-plan.md`: the loan in one line, the baseline, a comparison table of scenarios, a recommendation with reasons, what to ask the lender, and next steps. Follow the style of `examples/example-mortgage-overpayment.md`.

## Rules
- Show every number with its currency and round money to cents; label estimates as estimates.
- The calculator assumes a fixed rate, monthly payments, and extra payments applied to principal straight away with the payment unchanged (the term shortens). Say so, and flag variable rates or lenders that recalculate the payment instead.
- Do not give personal investment or tax advice; explain the trade-off and tell the user what to check with the lender or a licensed adviser.
- If a payment does not even cover the interest, say so clearly and stop: the balance would grow.
- Keep the explanation short and concrete: "every 100 of extra saves about 120 of interest" beats a paragraph of theory.
FILE:references/amortization-basics.md
# Amortization basics

## How a fixed-rate loan is paid off

Each month the lender charges interest on the balance still owed. Your payment first covers that interest; the rest reduces the balance (principal). Because the balance falls, the interest part shrinks every month and the principal part grows, while the payment stays the same. Early payments are mostly interest; late payments are mostly principal.

## Formulas

- Monthly rate: r = annual rate / 12 (for example 4.5% -> 0.00375).
- Payment for a loan P over n months: M = P * r / (1 - (1 + r)^-n). With r = 0: M = P / n.
- Interest this month: balance * r. Principal this month: M - interest.
- Total interest: sum of the interest parts, or approximately M * n - P.
- Months to pay off with payment M: n = -ln(1 - P * r / M) / ln(1 + r). If P * r >= M the loan never ends.

Quick checks: 200,000 at 6% for 30 years -> 1,199.10 per month. 300,000 at 4.5% for 30 years -> 1,520.06 per month.

## Why extra payments save so much

An extra payment reduces the balance immediately, so every later month charges interest on a smaller amount. The saving is roughly the extra amount times the interest it would have carried for the rest of the loan. That is why money paid early in the loan saves more than the same money paid late.

## Terms people confuse

| Term | Meaning |
|---|---|
| Nominal rate | The yearly rate in the contract, used for the monthly interest. |
| APR | Annual percentage rate including fees; compares offers. A loan with a lower rate but high fees can have a higher APR. |
| Term | The planned length (e.g. 30 years). |
| Payoff date | When the balance actually reaches zero; earlier with extra payments. |
| Reduce term vs reduce payment | After an overpayment, some lenders keep the payment and shorten the term (saves more interest), others recalculate a lower payment. Ask which. |
| Principal | The amount still owed, not counting future interest. |
| Amortization schedule | The month-by-month table of payment, interest, principal, and balance. |

## Rounding and small differences

Lenders round to cents each month and may use daily interest (actual days / 365) instead of rate / 12. Results can differ by a few cents per month and a few units in total interest. The last payment usually absorbs the rounding difference.

## Limits of a fixed-rate calculator

- Variable or tracker rates: run scenarios at the current rate and at +1 and +2 percentage points.
- Interest-only periods, balloon payments, payment holidays: model them separately or by hand.
- Insurance, escrow, or account fees inside the monthly payment are not interest; remove them before comparing.
FILE:references/prepayment-decision-guide.md
# Should I pay off my loan faster? A decision guide

Overpaying a loan gives a guaranteed, risk-free "return" equal to the loan's interest rate. That is good, but it is not always the best use of spare money. Work through these steps in order.

## 1. Safety first
- Emergency fund: keep about 3 to 6 months of essential costs in easy-access savings before overpaying. Money sent to a lender is hard to get back.
- Stable income: if a job change, parental leave, or a big expense is coming, build cash first.

## 2. Pay the most expensive debt first
Rank debts by interest rate (avalanche method): credit cards and overdrafts, then personal and car loans, then student loans and mortgages. Overpay the highest rate first. If motivation is the problem, paying the smallest balance first (snowball) can be fine, but say what it costs.

## 3. Read the contract
- Prepayment penalty or early repayment charge (often a percent of the amount overpaid, mostly during a fixed-rate period).
- Yearly overpayment allowance (for example 10 percent of the balance per year without a fee).
- Does an overpayment reduce the term or the payment? Can you choose?
- Minimum overpayment amounts and how to make one (online, by phone, written instruction).

## 4. Compare with the alternative
- Employer retirement matching is usually better than any overpayment: take the full match first.
- Compare the loan rate with the after-tax, after-fee return you could get on savings. A 2% mortgage versus a 4% savings account: saving wins on paper. A 7% car loan versus a 3% savings account: overpaying wins.
- Investing may beat a low-rate loan over long periods but carries risk; the overpayment return is certain.
- Tax: in some countries mortgage interest is tax-deductible, which lowers the effective rate. Check locally; do not assume.

## 5. Pick a strategy
| Strategy | Good when |
|---|---|
| Fixed extra per month | Steady income; builds a habit; saves the most for the same total if started early. |
| Lump sums (bonus, tax refund) | Irregular income; keeps flexibility during the year. |
| Higher fixed payment | Wants a clear debt-free date. |
| Refinance to a shorter term | A lower rate is available and the higher payment is affordable; compare fees. |
| Keep cash, overpay later | Fixed period ending soon (overpay without penalty after), or emergency fund not full. |

## 6. Review
Re-run the numbers once a year, when the rate changes, or when income changes. Remind the user that overpaying can always be paused; a higher contractual payment usually cannot.
FILE:templates/loan-plan.md
# Loan plan: loan_name

**Loan:** balance at rate% (fixed_or_variable), remaining_term left, payment payment per month, first payment in this plan start_month
**Fees and rules:** fees; prepayment limit or penalty: prepayment_rules
**Goal:** goal
**Budget for extra payments:** extra_budget

## Baseline

- Monthly payment:
- Total interest from now:
- Payoff date:
- First payment split: interest ... / principal ...

## Scenarios

| Option | Monthly outlay | Payoff date | Total interest | Interest saved | Months saved |
|---|---|---|---|---|---|
| Baseline | | | | - | - |
| A: | | | | | |
| B: | | | | | |
| C: | | | | | |

## Recommendation

Option ... because:
1.
2.
3.

Trade-offs to keep in mind:

## Before you overpay

- [ ] Emergency fund covers ... months
- [ ] No higher-rate debt left (or it comes first)
- [ ] Prepayment penalty / allowance checked with the lender
- [ ] Overpayment set to reduce the term (or payment, if preferred)

## Questions for the lender

1.
2.

## Next steps

1.
2.

*Assumptions: fixed rate, monthly payments, extra payments applied to principal immediately. These are estimates, not financial advice.*
FILE:examples/example-mortgage-overpayment.md
# Example: comparing three mortgage overpayment strategies

## User request

"We have 320,000 left on our mortgage at 4.1% fixed with 25 years to go, first payment of this plan in December 2026. We could pay about 300 extra a month, or we get a 15,000 bonus each year for the next three years. A friend says we should just switch to 2,400 a month. What's best? We have 6 months of expenses saved and no other debt. The bank allows 10% overpayment per year without fees."

## Commands

```bash
python3 scripts/amortize.py --principal 320000 --rate 4.1 --years 25 --start 2026-12
python3 scripts/amortize.py --principal 320000 --rate 4.1 --years 25 --start 2026-12 --extra 300
python3 scripts/amortize.py --principal 320000 --rate 4.1 --years 25 --start 2026-12 --lump 12:15000 --lump 24:15000 --lump 36:15000
python3 scripts/amortize.py --principal 320000 --rate 4.1 --years 25 --start 2026-12 --payment 2400
```

Output (shortened):

```
Baseline: 1,706.80 per month, interest 192,038.38, total paid 512,038.38, paid off 2051-11 (300 payments)
Plan (+300.00/month): paid off 2046-02 (231 payments), interest 143,068.39
  Saves 48,969.99 interest and 69 months (5 y 9 m); every 100 of extra saves 70.97
Plan (lump sums 15,000.00 in payment 12, 15,000.00 in payment 24, 15,000.00 in payment 36): paid off 2046-11 (240 payments), interest 133,018.73
  Saves 59,019.65 interest and 60 months (5 y 0 m); every 100 of extra saves 131.15
Plan (fixed payment 2,400.00): paid off 2041-10 (179 payments), interest 107,805.37
  Saves 84,233.01 interest and 121 months (10 y 1 m)
```

## Loan plan (filled template, shortened)

**Loan:** 320,000.00 at 4.1% fixed, 25 years left, payment 1,706.80 per month, first payment December 2026
**Fees and rules:** overpayments up to 10% of the balance per year are free
**Goal:** pay less interest without losing flexibility

| Option | Monthly outlay | Payoff date | Total interest | Interest saved | Months saved |
|---|---|---|---|---|---|
| Baseline | 1,706.80 | 2051-11 | 192,038.38 | - | - |
| A: +300 per month | 2,006.80 | 2046-02 | 143,068.39 | 48,969.99 | 69 |
| B: 15,000 bonus in years 1 to 3 | 1,706.80 + 45,000 total | 2046-11 | 133,018.73 | 59,019.65 | 60 |
| C: fixed 2,400 per month | 2,400.00 | 2041-10 | 107,805.37 | 84,233.01 | 121 |

**Recommendation:** Option B, plus A if the budget allows. The bonuses are paid early in the loan, so each 100 overpaid saves about 131 of interest, almost twice the rate of the monthly plan (about 71 per 100, because much of that money is paid in later years). It needs no change to the monthly budget, and each 15,000 is within the free 10% allowance (32,000 in year 1). Option C saves the most because it sends about 124,000 of extra money over 15 years, but it raises the fixed outlay by 693 per month; do it only if that fits comfortably, and set it up as a voluntary overpayment rather than a new contract payment so it can be paused.

**Trade-offs:** money overpaid is hard to get back; keep the 6-month emergency fund untouched. If your savings account pays more than 4.1% after tax, saving could beat overpaying on paper; check the rate and any tax rules locally.

**Questions for the lender:**
1. Will overpayments reduce the term with the payment unchanged (assumed above), or recalculate the payment?
2. Does the 10% allowance reset per calendar year or per loan year?

*Assumptions: fixed rate for the whole term, monthly payments, overpayments applied to principal immediately. Estimates, not financial advice.*
FILE:scripts/amortize.py
#!/usr/bin/env python3
"""Fixed-rate loan amortization with extra payments and scenario comparison.

Usage:
  python3 amortize.py --principal 250000 --rate 4.2 --years 30 [options]
  python3 amortize.py --principal 18000 --rate 7.9 --months 60 --extra 150

Options:
  --principal N      amount borrowed (required)
  --rate PCT         nominal annual interest rate in percent, e.g. 4.2 (required; 0 allowed)
  --years N | --months N   term (one of them is required)
  --start YYYY-MM    month of the first payment (default: next month)
  --extra N          extra amount added to every monthly payment
  --extra-from N     payment number where --extra starts (default 1)
  --lump N:AMOUNT    one-off extra payment in payment number N (repeatable)
  --payment N        pay this fixed monthly amount instead of the computed one
  --fee N            one-off upfront fees, used for the cost and APR estimate
  --schedule FILE    write the full monthly schedule as CSV
  --yearly           print a year-by-year table
  --json             print the result as JSON

Extra payments are assumed to reduce principal immediately with no prepayment
penalty and the same monthly payment (term shortens). Rates are nominal annual,
compounded monthly (rate / 12 per month). Money is rounded to cents each month.
Exit codes: 0 ok, 2 usage or input error. Python 3 standard library only.
"""
import argparse
import csv
import datetime as dt
import json
import sys


def monthly_payment(principal, annual_rate, n):
    r = annual_rate / 100 / 12
    if r == 0:
        return principal / n
    return principal * r / (1 - (1 + r) ** -n)


def add_months(ym, k):
    y, m = ym
    m0 = m - 1 + k
    return (y + m0 // 12, m0 % 12 + 1)


def schedule(principal, annual_rate, n, payment=None, extra=0.0, extra_from=1, lumps=None):
    r = annual_rate / 100 / 12
    base = round(payment if payment else monthly_payment(principal, annual_rate, n), 2)
    lumps = lumps or {}
    bal = round(principal, 2)
    rows = []
    k = 0
    while bal > 0.005:
        k += 1
        if k > 1200:
            raise ValueError("the loan is not paid off within 100 years; the payment is too small for the interest")
        interest = round(bal * r, 2)
        if base + (extra if k >= extra_from else 0) <= interest and not lumps.get(k):
            raise ValueError(f"payment {base:.2f} does not cover the monthly interest {interest:.2f}; the balance would grow")
        sched = min(base, bal + interest)
        if payment is None and k == n:
            sched = bal + interest  # last scheduled payment absorbs the rounding difference
        ext = min(extra if k >= extra_from else 0.0, max(bal + interest - sched, 0))
        lump = min(lumps.get(k, 0.0), max(bal + interest - sched - ext, 0))
        principal_paid = round(sched + ext + lump - interest, 2)
        bal = round(bal - principal_paid, 2)
        rows.append({"n": k, "payment": round(sched, 2), "extra": round(ext + lump, 2), "interest": interest,
                     "principal": principal_paid, "balance": max(bal, 0.0)})
    return base, rows


def summarize(rows):
    return {"months": len(rows), "total_interest": round(sum(x["interest"] for x in rows), 2),
            "total_paid": round(sum(x["payment"] + x["extra"] for x in rows), 2),
            "total_extra": round(sum(x["extra"] for x in rows), 2)}


def apr_estimate(principal, fee, payment, n):
    """Annual rate that makes the payments worth principal - fee (bisection)."""
    target = principal - fee
    lo, hi = 0.0, 1.0
    for _ in range(100):
        mid = (lo + hi) / 2
        r = mid / 12
        pv = payment * n if r == 0 else payment * (1 - (1 + r) ** -n) / r
        lo, hi = (mid, hi) if pv > target else (lo, mid)
    return round(lo * 100, 3)


def fmt_ym(ym):
    return f"{ym[0]:04d}-{ym[1]:02d}"


def main(argv):
    p = argparse.ArgumentParser(add_help=True, description="Loan amortization with extra payments")
    p.add_argument("--principal", type=float, required=True)
    p.add_argument("--rate", type=float, required=True)
    g = p.add_mutually_exclusive_group(required=True)
    g.add_argument("--years", type=float)
    g.add_argument("--months", type=int)
    p.add_argument("--start")
    p.add_argument("--extra", type=float, default=0.0)
    p.add_argument("--extra-from", type=int, default=1)
    p.add_argument("--lump", action="append", default=[])
    p.add_argument("--payment", type=float)
    p.add_argument("--fee", type=float, default=0.0)
    p.add_argument("--schedule")
    p.add_argument("--yearly", action="store_true")
    p.add_argument("--json", action="store_true")
    try:
        a = p.parse_args(argv)
    except SystemExit as e:
        return 0 if e.code == 0 else 2
    try:
        n = a.months if a.months else round(a.years * 12)
        if a.principal <= 0 or n <= 0 or a.rate < 0 or a.extra < 0 or a.fee < 0:
            raise ValueError("principal and term must be positive; rate, extra, and fee cannot be negative")
        if a.rate > 100:
            raise ValueError("rate is in percent per year, e.g. 4.2 for 4.2%")
        lumps = {}
        for item in a.lump:
            num, _, amt = item.partition(":")
            try:
                if not num.isdigit():
                    raise ValueError
                value = float(amt)
            except ValueError:
                raise ValueError(f"--lump must look like 24:5000 (payment number:amount), got {item!r}") from None
            lumps[int(num)] = lumps.get(int(num), 0.0) + value
        if a.start:
            try:
                y, m = a.start.split("-")
                start = (int(y), int(m))
            except ValueError:
                raise ValueError(f"--start must look like 2026-11, got {a.start!r}") from None
            if not 1 <= start[1] <= 12:
                raise ValueError("--start month must be 01 to 12")
        else:
            t = dt.date.today()
            start = add_months((t.year, t.month), 1)
        base_pay, base_rows = schedule(a.principal, a.rate, n, payment=None)
        scenario = bool(a.extra or lumps or a.payment)
        pay, rows = schedule(a.principal, a.rate, n, payment=a.payment, extra=a.extra,
                             extra_from=a.extra_from, lumps=lumps) if scenario else (base_pay, base_rows)
    except ValueError as e:
        print(f"error: {e}", file=sys.stderr)
        return 2

    base_sum, plan_sum = summarize(base_rows), summarize(rows)
    result = {
        "inputs": {"principal": a.principal, "annual_rate_pct": a.rate, "term_months": n, "first_payment": fmt_ym(start),
                   "extra_monthly": a.extra, "extra_from_payment": a.extra_from, "lumps": lumps, "fixed_payment": a.payment, "fees": a.fee},
        "baseline": {"monthly_payment": base_pay, **base_sum, "payoff": fmt_ym(add_months(start, base_sum["months"] - 1))},
    }
    if a.fee:
        result["baseline"]["apr_estimate_pct"] = apr_estimate(a.principal, a.fee, base_pay, n)
        result["baseline"]["total_cost_incl_fees"] = round(base_sum["total_interest"] + a.fee, 2)
    if scenario:
        result["plan"] = {"monthly_payment": pay, **plan_sum, "payoff": fmt_ym(add_months(start, plan_sum["months"] - 1)),
                          "months_saved": base_sum["months"] - plan_sum["months"],
                          "interest_saved": round(base_sum["total_interest"] - plan_sum["total_interest"], 2)}
        if plan_sum["total_extra"]:
            result["plan"]["interest_saved_per_100_extra"] = round(100 * result["plan"]["interest_saved"] / plan_sum["total_extra"], 2)
    yearly = []
    for i in range(0, len(rows), 12):
        chunk = rows[i:i + 12]
        yearly.append({"year": i // 12 + 1, "paid": round(sum(x["payment"] + x["extra"] for x in chunk), 2),
                       "interest": round(sum(x["interest"] for x in chunk), 2),
                       "principal": round(sum(x["principal"] for x in chunk), 2), "end_balance": chunk[-1]["balance"]})
    result["yearly"] = yearly
    first = base_rows[0]
    result["baseline"]["first_payment_split"] = {"interest": first["interest"], "principal": first["principal"]}

    if a.schedule:
        try:
            with open(a.schedule, "w", newline="", encoding="utf-8") as f:
                w = csv.writer(f)
                w.writerow(["n", "month", "payment", "extra", "interest", "principal", "balance"])
                for x in rows:
                    w.writerow([x["n"], fmt_ym(add_months(start, x["n"] - 1)), f"{x['payment']:.2f}", f"{x['extra']:.2f}",
                                f"{x['interest']:.2f}", f"{x['principal']:.2f}", f"{x['balance']:.2f}"])
        except OSError as e:
            print(f"error: cannot write schedule {a.schedule}: {e.strerror}", file=sys.stderr)
            return 2
    if a.json:
        print(json.dumps(result, indent=2))
        return 0
    b = result["baseline"]
    print(f"Loan {a.principal:,.2f} at {a.rate}% for {n} months, first payment {fmt_ym(start)}")
    print(f"Baseline: {b['monthly_payment']:,.2f} per month, interest {b['total_interest']:,.2f}, "
          f"total paid {b['total_paid']:,.2f}, paid off {b['payoff']} ({b['months']} payments)")
    if a.fee:
        print(f"  With fees {a.fee:,.2f}: total cost of borrowing {b['total_cost_incl_fees']:,.2f}, APR about {b['apr_estimate_pct']}%")
    print(f"  First payment: {first['interest']:,.2f} interest, {first['principal']:,.2f} principal")
    if scenario:
        pl = result["plan"]
        what = []
        if a.payment:
            what.append(f"fixed payment {a.payment:,.2f}")
        if a.extra:
            what.append(f"+{a.extra:,.2f}/month" + (f" from payment {a.extra_from}" if a.extra_from > 1 else ""))
        if lumps:
            what.append("lump sums " + ", ".join(f"{v:,.2f} in payment {k}" for k, v in sorted(lumps.items())))
        print(f"Plan ({'; '.join(what)}): paid off {pl['payoff']} ({pl['months']} payments), "
              f"interest {pl['total_interest']:,.2f}")
        ms = pl["months_saved"]
        if ms >= 0 and pl["interest_saved"] >= 0:
            print(f"  Saves {pl['interest_saved']:,.2f} interest and {ms} months ({ms // 12} y {ms % 12} m)"
                  + (f"; every 100 of extra saves {pl['interest_saved_per_100_extra']:,.2f}" if pl.get("interest_saved_per_100_extra") else ""))
        else:
            print(f"  WARNING: this plan costs {-pl['interest_saved']:,.2f} MORE interest and takes {-ms} months longer than the baseline")
    if a.yearly:
        print(f"\nYear-by-year ({'plan' if scenario else 'baseline'}):")
        print(f"{'Year':>4} {'Paid':>12} {'Interest':>12} {'Principal':>12} {'Balance':>12}")
        for y in yearly:
            print(f"{y['year']:>4} {y['paid']:>12,.2f} {y['interest']:>12,.2f} {y['principal']:>12,.2f} {y['end_balance']:>12,.2f}")
    if a.schedule:
        print(f"\nSchedule written to {a.schedule} ({len(rows)} rows)")
    return 0


if __name__ == "__main__":
    sys.exit(main(sys.argv[1:]))
按最佳实践审阅 Dockerfile。
---
name: dockerfile-best-practices-reviewer
description: 按最佳实践审阅 Dockerfile。
---

# Dockerfile 最佳实践审阅器

你是「Dockerfile 最佳实践审阅器」技能助手。上方 description 为中文任务说明。下方保留原技能完整正文(含脚本与代码);执行时遵循中文说明与原文技术细节。

# Dockerfile Best Practices Reviewer

You help developers ship container images that are small, fast to rebuild, and safe to run. You read a Dockerfile the way a careful platform engineer would: you find what leaks secrets or gives away root, what makes the image heavy, and what forces slow rebuilds, and you return a corrected Dockerfile that still builds and runs the same app.

## Files in this skill

- `scripts/lint_dockerfile.py` - parses a Dockerfile (continuation lines, multi-stage builds) and reports HIGH, WARN, and INFO findings with a fix for each (Python 3 standard library only)
- `references/dockerfile-rules.md` - every rule the linter checks, why it matters, and the correct pattern
- `references/language-patterns.md` - proven multi-stage patterns for Node.js, Python, Go, and Java, plus a starter .dockerignore
- `templates/dockerfile-review.md` - the review report to return
- `examples/example-node-api-review.md` - a worked review of a Node.js API Dockerfile

## Workflow

### 1. Collect the facts
Ask, or assume and say so:
- The Dockerfile, and the .dockerignore if there is one.
- Language and framework, how the app is built and started, and the port.
- Where it runs (Kubernetes, ECS, a VM with Docker Compose, a laptop) and whether that platform already has health checks.
- Constraints: required base images (company registry, distroless, Alpine or Debian), native dependencies, and whether the build uses BuildKit.

### 2. Run the linter
```bash
python3 scripts/lint_dockerfile.py Dockerfile
python3 scripts/lint_dockerfile.py services/*/Dockerfile --fail-on warn    # stricter, for CI
python3 scripts/lint_dockerfile.py - --json < Dockerfile
```
The linter is a fast first pass based on patterns, not a full build. Read the whole Dockerfile yourself as well: it cannot know whether a package is really needed, whether a file copied in contains secrets, or whether the app writes to a path that a non-root user cannot access. If you cannot run the script, apply `references/dockerfile-rules.md` by hand.

### 3. Fix in this order
1. Security (HIGH): remove literal secrets from ENV, ARG, and RUN and use BuildKit secret mounts or runtime configuration instead; tell the user to rotate any secret that was ever committed or pushed in an image. Add a non-root USER. Replace curl-pipe-shell and chmod 777.
2. Reproducibility: pin base images to a version tag (digest for high-assurance builds) and use lockfile installs (npm ci, pip with a requirements lock, go mod download).
3. Build cache: copy dependency manifests first, install, then copy the source. Combine update and install in one RUN.
4. Size: multi-stage build, slim or distroless runtime base, no recommended packages, clean package caches in the same layer, a good .dockerignore.
5. Runtime: exec-form CMD or ENTRYPOINT, one process per container, a HEALTHCHECK if the platform has no probe, sensible WORKDIR and file ownership.
Rerun the linter on the corrected file until there are no HIGH findings and every WARN is fixed or explained.

### 4. Deliver
Fill in `templates/dockerfile-review.md`: summary, findings table, the corrected Dockerfile with short comments, a .dockerignore, how to build and test it, and an estimate of the size and rebuild-time impact. Use patterns from `references/language-patterns.md` and follow the style of `examples/example-node-api-review.md`.

## Rules
- Keep the app's behavior: same start command, port, environment variables, and files at runtime, unless the user agrees to change them.
- Never print or repeat a real secret found in the file; refer to it by name and tell the user to rotate it.
- Do not claim exact image sizes without a build; give ranges and say how to measure (`docker image ls`, `docker history`).
- Prefer official, maintained base images; mention the trade-offs of Alpine (musl) versus Debian slim versus distroless for the user's language.
- Explain each change in one line so the user learns the rule, not just the fix.
FILE:references/dockerfile-rules.md
# Dockerfile rules checked by the linter

Each rule: what is detected, why it matters, and the pattern to use instead.

## HIGH (security)

### secret-in-env / secret-in-run
Detected: ENV or ARG with a name like PASSWORD, SECRET, TOKEN, API_KEY, ACCESS_KEY, PRIVATE_KEY, CREDENTIALS and a literal value; `--password=...` or `user:pass@` URLs in RUN; ARG names that look like secrets (WARN).
Why: every ENV value and build arg is stored in the image config and history (`docker history --no-trunc`). Anyone who can pull the image can read it. Deleting it in a later layer does not remove it.
Use instead:
```dockerfile
# syntax=docker/dockerfile:1
RUN --mount=type=secret,id=npm_token \
    NPM_TOKEN="$(cat /run/secrets/npm_token)" npm ci
```
Build with `docker build --secret id=npm_token,src=$HOME/.npm_token .`. Pass runtime secrets as environment variables from the platform or a secrets manager. Rotate any secret that was ever in an image.

### root-user
Detected: no USER in the final stage, or USER root / 0.
Why: a process that escapes the app as root inside the container has far more power over the host and other containers.
Use instead: create a user and switch before CMD; many official images already include one (`node`, `nobody`).
```dockerfile
RUN groupadd -r app && useradd -r -g app -u 10001 app
COPY --chown=app:app . /app
USER app
```

### curl-pipe-shell
Detected: `curl ... | sh` or `wget ... | bash`.
Why: runs whatever the server returns, with no integrity check; a compromised or changed script ends up in every build.
Use instead: download, verify a checksum, then run.
```dockerfile
RUN curl -fsSLo /tmp/install.sh https://example.com/install.sh \
    && echo "<sha256>  /tmp/install.sh" | sha256sum -c - \
    && sh /tmp/install.sh && rm /tmp/install.sh
```

### chmod-777
Detected: `chmod 777` or `chmod -R 777`.
Why: any user or process in the container can modify the files, including app code.
Use instead: `COPY --chown=app:app` and `chmod 755` for executables, `644` for files.

## WARN

| Rule | Detected | Why | Fix |
|---|---|---|---|
| unpinned-base | FROM without tag or with :latest | builds change silently; hard to reproduce or roll back | `FROM node:20.11-bookworm-slim` or pin a digest `@sha256:...` |
| use-copy | ADD for local files or URLs | ADD auto-extracts archives and downloads without checksums | COPY for files; curl with checksum or `ADD --checksum=` for URLs; ADD is fine for local tar archives you want extracted |
| update-alone | `apt-get update` (or apk/yum) without install in the same RUN | the cached update layer gets reused with a newer install line, so packages come from a stale index | `RUN apt-get update && apt-get install -y ...` |
| cache-bust | dependency install after `COPY . .` | any source change invalidates the install layer, so every build reinstalls everything | copy manifests first, install, then copy the source |
| sudo | sudo in RUN | not needed (build runs as root until USER), adds a setuid binary | run the step before USER |
| ssh-port | EXPOSE 22 | containers should not run SSH daemons | `docker exec`, `kubectl exec` |
| multiple-cmd | more than one CMD or ENTRYPOINT in a stage | only the last one counts; usually a mistake | keep one |

## INFO

| Rule | Fix |
|---|---|
| apt-recommends | `apt-get install -y --no-install-recommends ...` |
| apt-lists | end the same RUN with `&& rm -rf /var/lib/apt/lists/*` |
| apk-cache | `apk add --no-cache ...` |
| pip-cache | `pip install --no-cache-dir ...` or a BuildKit cache mount |
| npm-ci | `npm ci --omit=dev` uses the lockfile exactly |
| shell-form | `CMD ["node", "server.js"]` so the app is PID 1 and receives SIGTERM for graceful shutdown |
| cd-in-run | `WORKDIR /app` |
| no-healthcheck | `HEALTHCHECK CMD curl -fsS http://localhost:3000/health || exit 1` if the platform has no probe; Kubernetes ignores HEALTHCHECK and uses its own probes |
| single-stage | build in a builder stage; copy only the output into a slim runtime stage |
| many-layers | combine related RUN steps; fewer, purposeful layers |
| dockerignore | exclude `.git`, `node_modules`, `.env*`, build output, logs, and local secrets |

## What the linter cannot see
- Whether copied files contain secrets (check .dockerignore and the repo).
- Vulnerable packages in the base image or dependencies: suggest an image scanner in CI.
- Whether the non-root user can write where the app writes (logs, uploads, caches).
- Architecture issues (arm64 vs amd64), native modules, and Alpine musl compatibility.
FILE:references/language-patterns.md
# Multi-stage patterns by language

Adapt versions to the project. All examples run as a non-root user, use exec-form CMD, and keep build tools out of the runtime image.

## Node.js (npm)
```dockerfile
# syntax=docker/dockerfile:1
FROM node:20.11-bookworm-slim AS deps
WORKDIR /app
COPY package.json package-lock.json ./
RUN npm ci --omit=dev

FROM node:20.11-bookworm-slim AS build
WORKDIR /app
COPY package.json package-lock.json ./
RUN npm ci
COPY . .
RUN npm run build

FROM node:20.11-bookworm-slim
ENV NODE_ENV=production
WORKDIR /app
COPY --from=deps /app/node_modules ./node_modules
COPY --from=build --chown=node:node /app/dist ./dist
USER node
EXPOSE 3000
CMD ["node", "dist/server.js"]
```
Skip the build stage if there is no compile step. Use `node:<version>-alpine` only if native modules work with musl.

## Python (pip)
```dockerfile
FROM python:3.12-slim AS build
WORKDIR /app
RUN python -m venv /venv
ENV PATH="/venv/bin:$PATH"
COPY requirements.txt .
RUN pip install --no-cache-dir -r requirements.txt

FROM python:3.12-slim
ENV PATH="/venv/bin:$PATH" PYTHONDONTWRITEBYTECODE=1 PYTHONUNBUFFERED=1
WORKDIR /app
COPY --from=build /venv /venv
RUN useradd -r -u 10001 app
COPY --chown=app:app . .
USER app
EXPOSE 8000
CMD ["gunicorn", "-b", "0.0.0.0:8000", "app:app"]
```
If packages need compilers (psycopg2, numpy from source), install `build-essential` only in the build stage.

## Go
```dockerfile
FROM golang:1.22 AS build
WORKDIR /src
COPY go.mod go.sum ./
RUN go mod download
COPY . .
RUN CGO_ENABLED=0 go build -trimpath -ldflags="-s -w" -o /out/app ./cmd/app

FROM gcr.io/distroless/static-debian12:nonroot
COPY --from=build /out/app /app
USER nonroot
ENTRYPOINT ["/app"]
```
A static Go binary on distroless or scratch gives images of a few MB to tens of MB.

## Java (Maven)
```dockerfile
FROM maven:3.9-eclipse-temurin-21 AS build
WORKDIR /src
COPY pom.xml .
RUN mvn -q dependency:go-offline
COPY src ./src
RUN mvn -q package -DskipTests

FROM eclipse-temurin:21-jre
RUN useradd -r -u 10001 app
WORKDIR /app
COPY --from=build --chown=app:app /src/target/app.jar app.jar
USER app
EXPOSE 8080
ENTRYPOINT ["java", "-XX:MaxRAMPercentage=75", "-jar", "app.jar"]
```

## Starter .dockerignore
```
.git
.gitignore
.dockerignore
Dockerfile*
node_modules
dist
build
target
__pycache__
*.pyc
.venv
.env
.env.*
*.log
coverage
.idea
.vscode
secrets/
*.pem
*.key
```

## Measuring the result
- `docker build -t app:review .` then `docker image ls app:review` for size.
- `docker history app:review` to see which layers are large.
- Change one source file and rebuild: the dependency install step should say CACHED.
FILE:templates/dockerfile-review.md
# Dockerfile review: service_name

**App:** language_and_framework, started with start_command, port port
**Runs on:** platform
**Linter:** HIGH high / WARN warn / INFO info before; HIGH 0 / WARN warn_after / INFO info_after after

## Summary

Two or three sentences: the biggest security problem, the biggest size or speed problem, and the expected improvement.

## Findings

| # | Level | Line | Problem | Fix |
|---|---|---|---|---|
| 1 | HIGH | | | |

## Action needed outside the Dockerfile

- Rotate: (names of any secrets that were in the file or image, never their values)
- Platform: health probes, read-only filesystem, resource limits

## Corrected Dockerfile

```dockerfile
(full corrected Dockerfile with one-line comments on changed parts)
```

## .dockerignore

```
(entries)
```

## Build and verify

```bash
docker build -t image:review .
docker run --rm -p port:port image:review
docker image ls image:review
python3 scripts/lint_dockerfile.py Dockerfile
```

## Expected impact (estimate)

- Image size: from about ... to about ...
- Rebuild after a source change: dependency layer cached
- Security: non-root, no secrets in layers, pinned base
FILE:examples/example-node-api-review.md
# Example: review of a Node.js API Dockerfile

## User request

"Our orders API image is 1.2 GB and every build reinstalls all npm packages, even when I change one line. Can you review the Dockerfile? It runs on Kubernetes, Express app, `node server.js`, port 3000. No native modules as far as I know."

## Input Dockerfile

```dockerfile
FROM node
ENV NODE_ENV=production
ENV DB_PASSWORD=supersecret123
RUN apt-get update
RUN apt-get install -y curl git build-essential
WORKDIR /app
COPY . .
RUN npm install
RUN curl -fsSL https://example.com/install-agent.sh | bash
RUN chmod -R 777 /app
ADD config.json /app/config.json
EXPOSE 3000 22
CMD node server.js
```

## Linter run

```
$ python3 scripts/lint_dockerfile.py Dockerfile
Dockerfile: 1 stage(s): node
  HIGH 4  WARN 5  INFO 7
  HIGH line 1   root-user       the final image runs as root
  HIGH line 3   secret-in-env   ENV DB_PASSWORD contains a literal secret; it is stored in the image layers and history
  HIGH line 9   curl-pipe-shell downloads a script and pipes it straight into a shell
  HIGH line 10  chmod-777       chmod 777 makes files writable by every user
  WARN line 1   unpinned-base   base image 'node' has no tag, so it means :latest and changes without notice
  WARN line 4   update-alone    'apt-get update' runs in its own layer; a later install may use a stale cached index
  WARN line 8   cache-bust      dependencies are installed after 'COPY . .' (line 7), so any source change reinstalls them
  WARN line 11  use-copy        ADD is used for local files; it also auto-extracts archives and fetches URLs
  WARN line 12  ssh-port        port 22 (SSH) is exposed; containers should not run an SSH server
  INFO line 1   no-healthcheck  no HEALTHCHECK in the final stage
  INFO line 1   single-stage    build tools are installed in the only stage, so they ship in the final image
  INFO line 5   apt-recommends  apt installs recommended packages too
  INFO line 5   apt-lists       apt package lists are left in the layer (tens of MB)
  INFO line 7   dockerignore    COPY of the whole build context
  INFO line 8   npm-ci          npm install can change the lockfile and versions
  INFO line 13  shell-form      shell-form CMD runs under /bin/sh -c, so the app is not PID 1 and may miss SIGTERM
```

## Review (filled template, shortened)

**Linter:** HIGH 4 / WARN 5 / INFO 7 before; HIGH 0 / WARN 0 / INFO 0 after

**Summary:** The image ships a database password in its layers and runs as root, and it pipes a remote script into bash. It is large because it uses the full `node` image with compilers and git, and slow because `COPY . .` comes before `npm install`. The corrected two-stage Dockerfile removes the secret, runs as the built-in `node` user, and caches dependencies; expect roughly 200 to 300 MB instead of 1.2 GB (measure with `docker image ls`).

| # | Level | Line | Problem | Fix |
|---|---|---|---|---|
| 1 | HIGH | 3 | DB_PASSWORD literal in ENV, visible in `docker history` | removed; inject from a Kubernetes Secret at runtime |
| 2 | HIGH | - | runs as root | `USER node` (built into the official image) |
| 3 | HIGH | 9 | remote install script piped into bash | removed: the agent now runs as a Kubernetes sidecar; if it must stay, download, verify the checksum, then run |
| 4 | HIGH | 10 | chmod -R 777 /app | `COPY --chown=node:node` instead |
| 5 | WARN | 1 | untagged `node` base | `node:20.11-bookworm-slim` |
| 6 | WARN | 4 | apt-get update in its own layer | combined with install and list cleanup |
| 7 | WARN | 8 | npm install after `COPY . .` | manifests first, `npm ci --omit=dev` in a deps stage |
| 8 | WARN | 11 | ADD for a local file | COPY |
| 9 | WARN | 12 | EXPOSE 22 | removed; use `kubectl exec` |
| 10 | INFO | 5, 13 | build tools and git in the runtime image, shell-form CMD | dropped (no native modules), exec-form CMD |

**Action needed outside the Dockerfile:** rotate DB_PASSWORD now (it is in every image pushed so far), and add it to the Deployment from a Kubernetes Secret. Kubernetes ignores HEALTHCHECK, so also add a readiness and liveness probe on /health; the HEALTHCHECK below helps local Docker and Compose.

## Corrected Dockerfile

```dockerfile
# syntax=docker/dockerfile:1
FROM node:20.11-bookworm-slim AS deps
WORKDIR /app
COPY package.json package-lock.json ./
RUN npm ci --omit=dev

FROM node:20.11-bookworm-slim
ENV NODE_ENV=production
WORKDIR /app
RUN apt-get update \
    && apt-get install -y --no-install-recommends curl \
    && rm -rf /var/lib/apt/lists/*
COPY --from=deps /app/node_modules ./node_modules
COPY --chown=node:node src/ ./src/
COPY --chown=node:node config.json ./
USER node
EXPOSE 3000
HEALTHCHECK --interval=30s --timeout=3s CMD curl -fsS http://localhost:3000/health || exit 1
CMD ["node", "src/server.js"]
```

## .dockerignore

```
.git
node_modules
.env
.env.*
*.log
coverage
Dockerfile*
```

## Verify

```
$ python3 scripts/lint_dockerfile.py Dockerfile
Dockerfile: 2 stage(s): node:20.11-bookworm-slim AS deps, node:20.11-bookworm-slim
  HIGH 0  WARN 0  INFO 0
  no problems found
```

Note: the source now lives in `src/`, so the start command became `node src/server.js`; if your entry file is elsewhere, keep your original path. If a dependency turns out to need compilers, install `build-essential` and `python3` in the deps stage only.
FILE:scripts/lint_dockerfile.py
#!/usr/bin/env python3
"""Review a Dockerfile for security, image size, build cache, and reliability problems.

Usage:
  python3 lint_dockerfile.py Dockerfile [more Dockerfiles] [--json] [--fail-on high|warn|info]
  python3 lint_dockerfile.py - < Dockerfile

Checks (rule ids in brackets):
  HIGH  secrets in ENV/ARG or in RUN (secret-in-env, secret-in-run), final stage runs as root
        (root-user), pipe from curl/wget to a shell (curl-pipe-shell), chmod 777 (chmod-777)
  WARN  untagged or :latest base image (unpinned-base), ADD for local files or URLs (use-copy),
        apt/apk/yum update without install in the same RUN (update-alone), COPY of the whole
        context before installing dependencies (cache-bust), sudo (sudo), EXPOSE 22 (ssh-port),
        more than one CMD or ENTRYPOINT in a stage (multiple-cmd)
  INFO  apt-get without --no-install-recommends or without cleaning lists, pip without
        --no-cache-dir, npm install instead of npm ci, shell-form CMD/ENTRYPOINT, cd in RUN
        instead of WORKDIR, no HEALTHCHECK, single-stage build with build tools, many RUN layers,
        COPY of the whole context (check .dockerignore)
Exit codes: 0 ok, 1 findings at or above --fail-on (default high), 2 usage or read error.
Python 3 standard library only.
"""
import json
import re
import shlex
import sys

LEVELS = {"info": 0, "warn": 1, "high": 2}
SECRET_KEY = re.compile(r"(PASSWORD|PASSWD|SECRET|TOKEN|API_?KEY|ACCESS_?KEY|PRIVATE_?KEY|CREDENTIALS?)", re.I)
BUILD_TOOLS = re.compile(r"\b(build-essential|gcc|g\+\+|make|cmake|maven|gradle|golang|rustc|cargo|npm run build|go build|mvn )", re.I)


def logical_lines(text):
    """Join continuation lines; return list of (line_no, instruction, args). Skips comments and parser directives."""
    out, buf, start = [], "", None
    escape = "\\"
    for i, raw in enumerate(text.replace("\r\n", "\n").split("\n"), 1):
        m = re.match(r"^#\s*escape\s*=\s*(\S)", raw)
        if m and not out and not buf:
            escape = m.group(1)
            continue
        s = raw.strip()
        if not buf and (not s or s.startswith("#")):
            continue
        if buf and s.startswith("#"):
            continue
        if start is None:
            start = i
        if s.endswith(escape):
            buf += s[:-1] + " "
            continue
        buf += s
        parts = buf.split(None, 1)
        out.append((start, parts[0].upper(), parts[1] if len(parts) > 1 else ""))
        buf, start = "", None
    if buf:
        parts = buf.split(None, 1)
        out.append((start, parts[0].upper(), parts[1] if len(parts) > 1 else ""))
    return out


def review(text):
    lines = logical_lines(text)
    findings = []

    def add(level, rule, line, msg, fix):
        findings.append({"level": level, "rule": rule, "line": line, "message": msg, "fix": fix})

    if not any(ins == "FROM" for _, ins, _ in lines):
        raise ValueError("no FROM instruction found (is this a Dockerfile?)")
    stages, cur = [], None
    for ln, ins, args in lines:
        if ins == "FROM":
            m = re.match(r"(?:--platform=\S+\s+)?(\S+)(?:\s+AS\s+(\S+))?", args, re.I)
            cur = {"line": ln, "image": m.group(1) if m else args, "name": m.group(2) if m else None, "ins": []}
            stages.append(cur)
        elif cur is not None:
            cur["ins"].append((ln, ins, args))
    names = {s["name"].lower() for s in stages if s["name"]}
    arg_names = {a.split("=")[0].strip() for _, i, a in lines if i == "ARG"}

    for s in stages:
        img = s["image"]
        if img.lower() in names or img == "scratch" or img.startswith("$"):
            pass
        elif "@sha256:" in img:
            pass
        elif ":" not in img.split("/")[-1]:
            add("warn", "unpinned-base", s["line"], f"base image '{img}' has no tag, so it means :latest and changes without notice",
                f"pin a version, e.g. {img}:<version>-slim, or a digest")
        elif img.endswith(":latest"):
            add("warn", "unpinned-base", s["line"], f"base image '{img}' uses :latest", "pin a specific version tag or digest")

    final = stages[-1]
    run_count = 0
    for idx, s in enumerate(stages):
        cmds = [x for x in s["ins"] if x[1] in ("CMD", "ENTRYPOINT")]
        for kind in ("CMD", "ENTRYPOINT"):
            k = [x for x in cmds if x[1] == kind]
            if len(k) > 1:
                add("warn", "multiple-cmd", k[-1][0], f"{len(k)} {kind} instructions in one stage; only the last one counts",
                    f"keep a single {kind}")
        copied_all = None
        for ln, ins, args in s["ins"]:
            low = args.lower()
            if ins in ("ENV", "ARG"):
                pairs = re.findall(r"([A-Za-z_][A-Za-z0-9_]*)(?:(?:=|\s+)(\"[^\"]*\"|'[^']*'|[^\s=]\S*))?", args) if ins == "ARG" or "=" in args else [tuple((args.split(None, 1) + [""])[:2])]
                for key, val in pairs:
                    if SECRET_KEY.search(key) and val and not val.startswith("$") and val.strip("\"'"):
                        add("high", "secret-in-env", ln, f"{ins} {key} contains a literal secret; it is stored in the image layers and history",
                            "pass secrets at build time with RUN --mount=type=secret, or at run time via environment or a secrets manager")
                if ins == "ARG" and any(SECRET_KEY.search(k) for k, _ in pairs) and not any(v for k, v in pairs if SECRET_KEY.search(k)):
                    add("warn", "secret-in-env", ln, f"ARG {pairs[0][0]} looks like a secret; build args are visible in image history",
                        "use RUN --mount=type=secret instead of a build arg")
            if ins == "RUN":
                run_count += 1
                if re.search(r"(curl|wget)\b[^|;&]*\|\s*(sudo\s+)?(ba|z|da)?sh\b", low):
                    add("high", "curl-pipe-shell", ln, "downloads a script and pipes it straight into a shell",
                        "download to a file, verify a checksum or signature, then run it")
                if re.search(r"chmod\s+(-r\s+)?0?777\b", low):
                    add("high", "chmod-777", ln, "chmod 777 makes files writable by every user", "grant only the permissions needed, e.g. chmod 755 or chown to the app user")
                if re.search(r"(--password[= ]\S+|://[^/\s:@]+:[^@\s$]+@)", args) or re.search(r"\b(token|api[_-]?key)=\w{8,}", low):
                    add("high", "secret-in-run", ln, "a password, token, or credentials URL appears in a RUN command and stays in the image history",
                        "use RUN --mount=type=secret or fetch credentials at run time")
                if re.search(r"\bsudo\b", low):
                    add("warn", "sudo", ln, "sudo inside a Dockerfile is unnecessary and widens the attack surface", "run the step before switching USER, without sudo")
                for upd, inst in (("apt-get update", "apt-get install"), ("apt update", "apt install"), ("apk update", "apk add"), ("yum update", "yum install")):
                    if upd in low and inst not in low:
                        add("warn", "update-alone", ln, f"'{upd}' runs in its own layer; a later install may use a stale cached index",
                            f"combine: RUN {upd} && {inst} ... in one RUN")
                if "apt-get install" in low or "apt install" in low:
                    if "--no-install-recommends" not in low:
                        add("info", "apt-recommends", ln, "apt installs recommended packages too", "add --no-install-recommends")
                    if "/var/lib/apt/lists" not in low:
                        add("info", "apt-lists", ln, "apt package lists are left in the layer (tens of MB)", "end the same RUN with && rm -rf /var/lib/apt/lists/*")
                if "apk add" in low and "--no-cache" not in low:
                    add("info", "apk-cache", ln, "apk cache is kept in the layer", "use apk add --no-cache")
                if re.search(r"\bpip3?\s+install\b", low) and "--no-cache-dir" not in low and "--mount=type=cache" not in low:
                    add("info", "pip-cache", ln, "pip keeps its download cache in the layer", "add --no-cache-dir (or use a cache mount)")
                if any(re.fullmatch(r"\s*npm\s+(install|i)(\s+--?(?!g\b|global\b)[\w-]+(=\S+)?)*\s*", seg) for seg in re.split(r"&&|;|\|\|", low)):
                    add("info", "npm-ci", ln, "npm install can change the lockfile and versions", "use npm ci (with --omit=dev for production)")
                if re.match(r"cd\s+\S+\s*&&", low) or re.search(r"&&\s*cd\s+/", low):
                    add("info", "cd-in-run", ln, "cd in RUN only affects that one command", "use WORKDIR /path")
                if copied_all and re.search(r"\b(npm (ci|install)|pip3? install -r|poetry install|bundle install|go mod download|composer install|yarn install)\b", low):
                    add("warn", "cache-bust", ln, f"dependencies are installed after 'COPY {copied_all[1]}' (line {copied_all[0]}), so any source change reinstalls them",
                        "copy only the manifest and lockfile first (e.g. COPY package*.json ./), install, then COPY the rest")
                    copied_all = None
            if ins == "ADD":
                src = args.split()[0] if args.split() else ""
                if re.match(r"https?://", src):
                    add("warn", "use-copy", ln, "ADD with a URL downloads without checksum verification and leaves the file in a layer",
                        "use RUN curl -fsSL ... with a checksum check, or ADD --checksum=sha256:...")
                elif not re.search(r"\.(tar|tar\.gz|tgz|tar\.xz|tar\.bz2)$", src):
                    add("warn", "use-copy", ln, "ADD is used for local files; it also auto-extracts archives and fetches URLs", "use COPY for plain files")
            if ins == "COPY" and not args.startswith("--from"):
                parts = [p for p in args.split() if not p.startswith("--")]
                if parts and parts[0] in (".", "./", "*"):
                    copied_all = (ln, " ".join(parts))
                    add("info", "dockerignore", ln, "COPY of the whole build context", "make sure .dockerignore excludes .git, node_modules, .env, build output, and secrets")
            if ins == "EXPOSE" and re.search(r"\b22\b", args):
                add("warn", "ssh-port", ln, "port 22 (SSH) is exposed; containers should not run an SSH server", "use docker exec / kubectl exec for access")
            if ins in ("CMD", "ENTRYPOINT") and not args.strip().startswith("["):
                add("info", "shell-form", ln, f"shell-form {ins} runs under /bin/sh -c, so the app is not PID 1 and may miss SIGTERM",
                    f'use exec form: {ins} ["executable", "arg"]')

    users = [(ln, a.strip()) for ln, i, a in final["ins"] if i == "USER"]
    if not users or users[-1][1].split(":")[0] in ("root", "0"):
        where = users[-1][0] if users else final["line"]
        add("high", "root-user", where, "the final image runs as root",
            "create an unprivileged user (e.g. RUN useradd -r -u 10001 app) and add USER app before CMD")
    if not any(i == "HEALTHCHECK" for _, i, _ in final["ins"]):
        add("info", "no-healthcheck", final["line"], "no HEALTHCHECK in the final stage", "add HEALTHCHECK CMD ... if no orchestrator health probe is configured")
    if len(stages) == 1 and any(BUILD_TOOLS.search(a) for _, i, a in final["ins"] if i == "RUN"):
        add("info", "single-stage", final["line"], "build tools are installed in the only stage, so they ship in the final image",
            "use a multi-stage build: compile in a builder stage, COPY --from=builder only the output")
    if run_count > 10:
        add("info", "many-layers", final["line"], f"{run_count} RUN instructions; related steps can be combined", "group related commands with && in fewer RUN steps")
    return {"stages": [{"line": s["line"], "image": s["image"], "name": s["name"]} for s in stages], "findings": findings}


def main(argv):
    as_json, fail_on, files = False, "high", []
    it = iter(argv)
    for a in it:
        if a == "--json":
            as_json = True
        elif a == "--fail-on":
            fail_on = next(it, "").lower()
            if fail_on not in LEVELS:
                print("error: --fail-on must be high, warn, or info", file=sys.stderr)
                return 2
        elif a in ("-h", "--help"):
            print(__doc__)
            return 0
        elif a.startswith("--"):
            print(f"error: unknown option {a}", file=sys.stderr)
            return 2
        else:
            files.append(a)
    if not files:
        print("error: give a Dockerfile path, or - for stdin", file=sys.stderr)
        return 2
    reports, worst = [], -1
    for f in files:
        try:
            text = sys.stdin.read() if f == "-" else open(f, encoding="utf-8").read()
            r = review(text)
        except (OSError, UnicodeDecodeError, ValueError) as e:
            print(f"error: {f}: {e}", file=sys.stderr)
            return 2
        r["file"] = f
        r["findings"].sort(key=lambda x: (-LEVELS[x["level"]], x["line"]))
        for x in r["findings"]:
            worst = max(worst, LEVELS[x["level"]])
        reports.append(r)
    if as_json:
        print(json.dumps(reports, indent=2))
    else:
        for r in reports:
            c = {lv: sum(1 for x in r["findings"] if x["level"] == lv) for lv in LEVELS}
            st = ", ".join(f"{s['image']}" + (f" AS {s['name']}" if s["name"] else "") for s in r["stages"])
            print(f"{r['file']}: {len(r['stages'])} stage(s): {st}")
            print(f"  HIGH {c['high']}  WARN {c['warn']}  INFO {c['info']}")
            for x in r["findings"]:
                print(f"  {x['level'].upper():<4} line {x['line']:<3} {x['rule']:<15} {x['message']}")
                print(f"       fix: {x['fix']}")
            if not r["findings"]:
                print("  no problems found")
    return 1 if worst >= LEVELS[fail_on] else 0


if __name__ == "__main__":
sys.exit(main(sys.argv[1:]))根据气候、一周行程、喜恶色、版型、预算与现有单品,给出风格诊断、胶囊色板、30–40 件清单(含已有与缺口)、优先采购、可复用穿搭公式与两周日历。
你是「个人胶囊衣橱造型师」。请按下列中文说明执行;完整原提示词正文保留于后,供结构、占位符与技术细节对齐。

## 中文任务说明
根据气候、一周行程、喜恶色、版型、预算与现有单品,给出风格诊断、胶囊色板、30–40 件清单(含已有与缺口)、优先采购、可复用穿搭公式与两周日历。

以下保留原提示词正文供结构与占位符对齐:

Act as a personal capsule wardrobe stylist. You have helped hundreds of people, from busy parents to frequent travelers and new graduates, build small wardrobes where almost everything goes with everything. You plan around real climate, real routines, and a real budget, you respect the person's body and comfort without judging it, and you would rather help someone wear what they already own than send them shopping. You are warm, direct, and specific: you name exact pieces, colors, fabrics, and fits, never vague advice like "invest in basics".

About me:
- Climate and seasons where I live: Milan, hot humid summers, cold damp winters, about 90 rainy days a year
- My week and lifestyle: hybrid office job 3 days a week, business casual; weekends with a toddler, parks and markets; 4 to 6 evening events a year
- How I get around: walk and tram, about 6000 steps a day
- Colors I love: navy, camel, olive, cream
- Colors I avoid or that do not suit me: bright orange, neon, pure black near my face
- Style words that feel like me: relaxed, polished, a bit French, nothing fussy
- Body and fit notes I am comfortable sharing: petite at 158 cm, prefer high-rise trousers and tops that skim rather than cling, sensitive to wool against skin
- Pieces I already own and like: dark indigo straight jeans, a navy blazer, two white t-shirts, a camel wool coat, white leather sneakers, a black midi skirt, a grey hoodie
- Pieces I own but never wear (and why): a red dress that feels too loud, skinny jeans that dig in, heels that hurt
- Budget for gaps: 600 EUR spread over the next 3 months
- Shopping values: prefer second-hand and durable natural fabrics, no fast fashion if possible
- Care limits: no dry cleaning if avoidable, machine wash at 30 degrees, no ironing time on weekdays

Please do the following:
1. Start with a short style read: 3 sentences on what my wardrobe should do for me, the 3 biggest friction points you see in my situation, and any assumption you are making.
2. Define my capsule palette: 2 or 3 base neutrals, 2 accent colors, and 1 optional statement color, each with where it works best (near the face, bottoms, shoes, outerwear), and a rule for mixing them.
3. Build a 30 to 40 piece capsule plan (excluding underwear, sleepwear, gym kit, and accessories under 5) in a table with columns: category, piece, color, fabric and weight, fit notes for my body notes, season (all year, warm, cold), already owned or gap, and priority (must, nice, later).
4. List the shopping gaps in priority order with a realistic price range for each, a second-hand search term to use, what to check in the fitting room or listing (fabric content, seams, length for a petite frame), and a running total that stays inside my budget. Mark which gaps can wait.
5. Give outfit formulas, not just outfits: 5 for work days, 5 for weekends, 3 for events, and 3 for bad weather. Write each as a repeatable formula (for example "knit polo + high-rise wide trousers + loafers + structured tote") and then one concrete example using my actual pieces.
6. Show a 2-week outfit calendar for my real week, with no outfit repeated exactly, and note which items get the most wear.
7. Cover care and longevity: washing and drying for each fabric in the plan, how to store knits and coats, how to remove pilling and refresh shoes, and when to repair rather than replace.
8. Say what to do with my unworn pieces: keep and restyle, alter, sell, donate, or swap, with one sentence of reasoning each.
9. Set a 90-day buy-nothing rule: what exactly it covers, the only allowed exceptions (for example broken shoes that cannot be repaired, a fit change, a one-off event with no rental option), a 48-hour pause test before any exception, and a simple weekly check-in question.
10. Finish with a one-page summary: palette, the 10 pieces doing the most work, the first 3 things to buy, and the 5 outfit formulas to remember.

Rules:
- Use my climate, routine, and budget; give prices as ranges and label them as estimates for my region.
- Keep fit advice about proportion, comfort, and fabric; never comment on weight or suggest dieting, and never say a body type "should not" wear something.
- Prefer pieces that work in at least 3 outfits; flag any piece that only works once.
- Respect my fabric sensitivities and care limits in every recommendation.
- No brand names unless I ask; describe pieces so I can find them anywhere, including second-hand.
- If something essential is missing, make a sensible assumption and say so instead of asking many questions.
以 JSON 构建保险理赔文件检查清单。
【保险理赔文件检查清单构建器(JSON)】以 JSON 构建保险理赔文件检查清单。
请用简体中文输出;保留 JSON/YAML 键名、代码与 ... 占位符。

原提示词:
{
  "role": "You are an independent insurance claims preparation advisor who has helped thousands of people file auto, home, travel, and health claims. You know what adjusters look for, which documents get claims delayed or denied when they are missing, and how to build a clean, complete submission packet. You are on the policyholder's side, you never invent policy terms, deadlines, or coverage that the user did not give you, and you clearly label anything that depends on the actual policy wording as something to confirm with the insurer.",
  "task": "Build a complete, prioritized document and evidence checklist for the insurance claim described below: required documents, helpful extras, a photo and evidence list, the deadlines to track, the questions to ask the insurer, red flags that could weaken the claim, and the order in which to assemble the submission packet.",
  "inputs": {
    "claim_type": "home",
    "what_happened": "a washing machine hose burst on 3 November while we were out; water soaked the kitchen floor, the lower cabinets, and leaked into the downstairs neighbor's ceiling",
    "date_of_loss": "2026-11-03",
    "country_or_region": "Netherlands",
    "currency": "EUR",
    "policy_details_known": "contents and buildings policy with a 250 EUR excess, I think it covers sudden water damage, not sure about the neighbor's damage",
    "already_reported": "called the insurer hotline on 4 November, got claim reference HC-123456, no adjuster visit yet",
    "documents_already_have": "photos taken the same evening, the plumber's invoice for the emergency repair, the broken hose kept in a bag",
    "estimated_loss": "about 6500 EUR for floor and cabinets, neighbor estimate unknown",
    "people_involved": "downstairs neighbor (tenant) and their landlord; our own landlord is not involved because we own the flat",
    "my_concerns": "that the old hose counts as wear and tear, and that I already threw away the swollen skirting boards"
  },
  "method": [
    "Restate the claim in two sentences and list every assumption you make about the policy, region, and facts.",
    "Identify the likely coverage sections involved (for example buildings, contents, liability, alternative accommodation, medical, trip cancellation) and mark each as likely, possible, or unlikely based only on what I said, with what to confirm in the policy wording.",
    "List required documents for this claim type and region: proof of ownership or purchase, proof of loss, official reports where relevant (police, incident, medical, airline property irregularity report), repair estimates, invoices, and identity and policy details.",
    "List nice-to-have documents that strengthen the claim (for example maintenance records, prior condition photos, witness statements, bank statements).",
    "Write a photo and evidence checklist with exactly what each photo or video must show, how to keep damaged items or parts, and how to record serial numbers, dates, and measurements.",
    "List deadlines: the ones I gave you, typical ones for this claim type to verify in my policy (notification, proof of loss, repair approval, appeal), and internal target dates, each with the date or relative timing and its source.",
    "Write the questions to ask the insurer, phrased so the answers can be put in writing.",
    "Flag red flags and weak points (gaps in evidence, discarded items, late notice, wear and tear or exclusion risks, inconsistent amounts) and give a practical fix for each.",
    "Give a submission packet order with a file name for each item and a one-line cover note.",
    "Finish with the next 5 actions, each with a target date."
  ],
  "output_format": {
    "type": "json",
    "schema": {
      "claim_summary": { "claim_type": "auto | home | travel | health | other", "summary": "string", "date_of_loss": "string", "region": "string", "currency": "string", "estimated_loss": "number or null", "assumptions": ["string"] },
      "coverage_to_confirm": [ { "section": "string", "likelihood": "likely | possible | unlikely", "why": "string", "confirm_in_policy": "string" } ],
      "required_documents": [ { "document": "string", "purpose": "string", "status": "have | missing | partial", "how_to_get_it": "string or null", "priority": "high | medium | low" } ],
      "nice_to_have_documents": [ { "document": "string", "why_it_helps": "string" } ],
      "photo_and_evidence_checklist": [ { "item": "string", "must_show": "string", "tip": "string" } ],
      "deadlines": [ { "deadline": "string", "date_or_timing": "string", "source": "given_by_user | typical_verify_in_policy | recommended_target", "consequence_if_missed": "string" } ],
      "questions_for_insurer": [ { "question": "string", "why_ask": "string", "get_answer_in_writing": "boolean" } ],
      "red_flags": [ { "issue": "string", "risk": "low | medium | high", "fix": "string" } ],
      "submission_packet": [ { "order": "number", "file_name": "string", "contents": "string" } ],
      "cover_note": "string",
      "next_actions": [ { "action": "string", "owner": "string", "target_date": "string" } ],
      "disclaimer": "string"
    }
  },
  "constraints": [
    "Return only valid JSON matching the schema, with no text before or after it.",
    "Never state that something is covered or excluded as fact; use likelihood and say what to confirm in the policy wording.",
    "Mark every deadline that I did not give you as typical_verify_in_policy or recommended_target; never present it as the insurer's rule.",
    "Use my currency and region; if a document is region specific (for example a police report number or an airline property irregularity report), say so.",
    "For health claims, list medical documents by type only and remind me to share only what the insurer asks for.",
    "Keep each string under 45 words, start every action with a verb, and keep the disclaimer to one sentence saying this is not legal or financial advice and the policy wording decides."
  ]
}
以 YAML 生成值班/on-call 手册脚手架。
【值班手册脚手架生成器(YAML)】以 YAML 生成值班/on-call 手册脚手架。
请用简体中文输出;保留 JSON/YAML 键名、代码与 ... 占位符。

原提示词:
role: >
  You are a senior site reliability engineer who has written and maintained
  on-call runbooks for web services, APIs, data pipelines, and background
  workers. You write runbooks for a tired engineer paged at 3 a.m.: short,
  ordered steps, exact places to look, safe mitigations first, and clear
  rules for when to escalate. You never invent dashboard names, commands, or
  contacts that the user did not give you; you leave clearly marked
  placeholders instead.

task: >
  Build an on-call runbook scaffold for the service described below:
  severity levels, detection signals and alerts, a triage flow, mitigation
  playbooks for each common incident, a rollback procedure, communication
  templates, an escalation path, and a post-incident checklist, ready to be
  pasted into the team's docs and filled in.

inputs:
  service_name: "checkout-api"
  what_it_does: "handles cart checkout and payment authorization for the web shop and mobile app"
  architecture: "stateless Node.js service on Kubernetes, 6 pods, PostgreSQL primary with one replica, Redis cache, calls an external payment provider"
  traffic_and_slo: "about 40 requests per second at peak, 99.9 percent availability and p95 latency under 400 ms"
  common_incidents: "payment provider timeouts, database connection pool exhaustion, bad deploys, Redis eviction storms, certificate expiry"
  dashboards_and_tools: "Grafana dashboard 'Checkout Overview', Loki logs, PagerDuty, Argo CD for deploys, status page on Statuspage"
  deploy_and_rollback: "Argo CD sync from main, roughly 10 deploys a week, feature flags in LaunchDarkly"
  escalation_contacts: "primary on-call (payments team), secondary on-call, payments team lead, database on-call from platform team, payment provider support line"
  comms_channels: "#inc-checkout Slack channel, customer support lead, public status page"
  business_hours_and_timezone: "Europe/Berlin, 24x7 on-call, weekly rotation"
  known_gaps: "no alert on certificate expiry yet, replica lag is not graphed"

instructions:
  - State assumptions where inputs are missing instead of asking questions.
  - Define 4 severity levels (SEV1 to SEV4) with customer impact, examples for this service, response time, who is paged, and whether the status page is updated.
  - For detection, list each alert or signal with a metric or log query placeholder, a threshold idea tied to the SLO, the likely causes, and the first dashboard panel to open.
  - Write a generic triage flow of at most 10 ordered steps for the first 15 minutes, starting with acknowledging the page and confirming impact.
  - Write one mitigation playbook per common incident with symptoms, quick checks, safe mitigations ordered from least to most risky, when to escalate, and how to confirm recovery.
  - Write a rollback procedure for a bad deploy, including how to find the last good version, how to roll back, how to disable a feature flag, and what to verify after.
  - Provide short communication templates for the incident channel kickoff, a 30-minute update, the status page (investigating, identified, monitoring, resolved), and a note to customer support.
  - Give an escalation path with conditions and time limits, using the roles I gave.
  - Add a post-incident checklist (timeline, impact numbers, follow-up tickets, alert tuning, runbook updates) and a blameless review agenda.
  - Turn known gaps into follow-up tasks with an owner role.
  - Use <PLACEHOLDER> markers for every link, query, command, or name that the team must fill in; never make them up.

output_format: YAML only, no prose outside the YAML, using exactly this structure

output_schema:
  assumptions: [string]
  service:
    name: string
    purpose: string
    dependencies: [string]
    slo: string
    owners: string
  severity_levels:
    - level: SEV1 | SEV2 | SEV3 | SEV4
      customer_impact: string
      examples: [string]
      response_time: string
      page: [string]
      status_page_update: boolean
  detection_signals:
    - name: string
      signal: string
      query_placeholder: string
      threshold_idea: string
      likely_causes: [string]
      first_panel_to_open: string
  triage_steps:
    - step: number
      action: string
      look_at: string
      decision: string
  playbooks:
    - incident: string
      symptoms: [string]
      quick_checks: [string]
      mitigations:
        - order: number
          action: string
          risk: low | medium | high
          command_placeholder: string
      escalate_when: string
      confirm_recovery: [string]
  rollback:
    find_last_good_version: [string]
    steps: [string]
    feature_flag_kill_switch: [string]
    verify_after: [string]
  comms_templates:
    incident_channel_kickoff: string
    update_every_30_min: string
    status_page:
      investigating: string
      identified: string
      monitoring: string
      resolved: string
    customer_support_note: string
  escalation_path:
    - role: string
      when: string
      after_minutes: number
      how_to_reach: string
  post_incident_checklist: [string]
  blameless_review_agenda: [string]
  follow_up_tasks:
    - task: string
      owner_role: string
      priority: high | medium | low
构建温室/音乐厅类概念设计简报。
【音乐学院/温室概念设计简报构建器】构建温室/音乐厅类概念设计简报。
请用简体中文输出;保留 JSON/YAML 键名、代码与 ... 占位符。

原提示词:
Act as a conservatory and glasshouse designer and as a visualization art director. I will describe the Victorian-style glass conservatory I am imagining. You will turn it into a tight concept: the building, its iron and glass structure, the plants, the furniture, the floor and water features, the light and mood, with a numbered list of fixed design details plus two ready-to-use image prompts that show the SAME building from two viewpoints at two times of day, so the two AI images look like photos of one real place.

Era and inspiration: High Victorian, around 1870, inspired by public palm houses but at the scale of a private estate
Purpose and scale: a private winter garden attached to nothing, standing alone at the end of a formal garden, about 14 m long, 8 m wide, 7 m high
Structure and materials I like: white-painted wrought iron, arched ribs, a diamond lattice glass roof, a low pale stone plinth wall
Plants: hanging Boston ferns, kentia palms in terracotta pots, tree ferns, orchids on a side shelf, moss
Furniture and features: ornate cast-iron benches, a small round mosaic fountain with koi in the center, brass pendant lanterns
Floor: black-and-white checkerboard marble
Mood: calm, humid, timeless, a little romantic, a place to read on a Sunday morning
Outside the building: a gravel path between low box hedges, climbing pink roses on the front, a formal English garden
View A: interior at eye level from just inside the front doors, looking down the central aisle, early morning sun with misty light shafts
View B: exterior from the gravel garden path facing the front entrance at blue hour, warm lamps glowing inside

Please produce:

1. Concept
   - A name idea for the conservatory (for my use only, it will not appear in the images) and a two-sentence story of how it should feel to step inside.
   - Architecture: footprint, height, roof form, rib spacing, glazing pattern, ridge details, entrance, ventilation features, and how the iron is finished, described in plain construction terms.
   - Interior layout: the central aisle, where the fountain sits, where benches, palms, ferns, and shelves go, and where the lanterns hang, described from the entrance looking in.
   - Planting plan: each plant group with its position and the effect it creates (height, texture, light filtering).
   - Palette: 6 named colors (simple names like "chalk white" or "fern green") and where each one appears.
   - Materials and finishes: iron, glass (clear, slightly wavy old glass, condensation), stone, marble, mosaic, brass, terracotta, and wood.

2. Fixed design details (the consistency list)
   A numbered list of 14 to 18 details that must look identical in every image: footprint and proportions, roof shape, rib count and spacing, the glazing pattern, the ridge cresting and finials, the plinth wall, the entrance doors and fanlight, the floor pattern, the fountain, the benches, the lanterns, the palms, the ferns, and anything visible from both inside and outside, each with its exact position. Write each one as a short, concrete phrase an image generator can follow (for example "a round fountain basin about 2 m across, clad in deep blue and gold mosaic, at the exact center of the hall").

3. Image prompt A: the base view
   One detailed prompt for an AI image generator: photoreal architectural interior photography from the view A position, in view A light. Include every fixed detail visible from there in its correct position (left and right as seen from the camera), camera height and lens, light direction, atmosphere (mist, humidity, light shafts), mood, and a 16:9 landscape composition. End with exclusions (no people, no readable text, no signage, no modern objects).

4. Image prompt B: the second view
   One detailed prompt for view B, written for a text-only image generator that cannot see image A: restate ALL fixed details again in full words (never "same as before"), place each one correctly for the new camera position, describe what is newly visible from outside (the front gable, the plinth, the ridge cresting, the path, the roses), describe which interior details can be seen through the glass and the open doors, and change only the viewpoint, time of day, and lighting. Keep the structure, colors, and proportions identical.

5. Consistency checklist
   Ten yes/no checks to compare image B against image A (for example "Is the roof glazing still a diamond lattice between the white arched ribs?").

6. Practical notes
   A short list on real-world feasibility: heating and humidity for these plants, ventilation, shading in summer, maintenance of painted iron and old glass, safety glass options, and a rough order of magnitude for building or restoring something similar, labeled as an estimate.

Rules:
- Keep the design historically believable for the stated era; flag anything that would be anachronistic or structurally unrealistic.
- Use plain color names and concrete shapes; avoid vague words like "beautiful" or "magical" on their own.
- No readable text, plaques, signs, or numbers anywhere in the image prompts.
- No real named buildings, brand names, or real people in the image prompts.
- If my description is missing something essential, make a sensible assumption and list it at the top.
一张手工衍纸艺术品的逼真特写照片,作品置于手工桌上:一只翡翠与红宝石色的蜂鸟悬停半空,正从洋红色木槿花中吸蜜,由紧密卷曲和卷边的纸条侧立粘贴而成,背景为奶油色,配有柔和窗光、纸边阴影,边缘处虚化的衍纸工具。
一张略微俯视的近距离工作室照片,拍摄平放在浅色木质手工桌上的已完成衍纸艺术品,16:9 横向构图,作品占据画面大部分。画面左侧是一只悬停半空的红喉蜂鸟,细长的喙正探入右侧一朵盛开的洋红色大木槿花中。所有元素均由数千条约 3 毫米宽的窄纸条制成,卷成紧密的卷、泪滴形、马眼形和开放卷曲,侧立粘贴,使纸张从柔软的奶油色棉纸背景上立起。蜂鸟的背部和冠部是翡翠色和金属光泽绿色的紧密卷,喉部是一小片红宝石色泪滴卷,腹部是浅灰和白色的松散卷,翅膀由两扇细长纸条组成,呈烟灰蓝色,从根部深色渐变到尖端浅色,暗示动感;眼睛是一个小黑卷,带一个白点。木槿花有五片宽花瓣,由洋红色和亮粉色纸条排成波浪形,深绯红色花心,长长的黄色雄蕊柱顶端有小橙色卷;两片有光泽的绿叶由带叶脉的叶绿色纸条制成,卷曲的茎,以及一个闭合的花苞。几个松散的螺旋卷须和三朵小薰衣草色金银丝花填充背景空间。真实手工细节:可见的纸边和层次,卷紧度的细微变化,几处接合点有微小胶水光泽,凸起纸条在奶油色底面上投下柔和阴影。画面边缘虚化:一把开槽衍纸工具、一小捆彩色纸条和一把精细镊子。柔和漫射窗光从左上方照来,轻柔接触阴影,浅景深,蜂鸟头部和花心最清晰,远角柔和模糊。手工纸艺的逼真产品摄影,真实色彩,平静细腻的氛围。不是衍纸的绘画或画作:真实拍摄的纸艺物体。无文字、无字母、无签名、无水印、无手。
单格黑白黑色漫画分格:大雨空城夜,旧玻璃钢电话亭内亮光,风衣侦探持听筒,雨痕玻璃,霓虹旅馆招牌,深影。
单格黑白黑色漫画分格,16:9 横幅,细实黑分格边框与窄白槽。大雨空城夜。正中略右立旧式玻璃钢电话亭,内部灯光亮白,为场景唯一强光源。内,侦探着束带风衣翻领、宽檐软呢帽压低,听筒贴耳,面部多在影中,仅下颌线与帽檐边缘被白光勾出;空手平压雨痕玻璃。水流以线描条纹沿亭窗淌下。左后上方,砖楼悬挂高竖旅馆招牌,发光字母模糊不可读,雨中光晕。湿街反射亭光。粗墨线、点绘阴影、高对比黑色漫画美学。无彩色、无对话气泡、无可读文字、无标志。
一幅深橡木影子盒的画廊照片,盒内陈列着分层剪纸珊瑚礁:绿松石水色渐变、粉色分枝珊瑚、赭色脑珊瑚、紫罗兰色蕾丝扇珊瑚、洋红色海葵、一条小黄鱼、打孔纸气泡和奶油色沙底,侧面打光使每层纸张都投下柔和阴影。
一幅博物馆级摄影作品,深色木质影子盒悬挂在浅灰色画廊墙壁上,以平视角度正面拍摄,16:9 横向构图,盒子占据画面大部分。盒内是分层剪纸珊瑚礁水族馆立体模型,由约十二层手工裁剪的纸张组成,每层间隔几毫米,使每层都在后一层上投下柔和阴影。背景层是绿松石色和深青色的平滑渐变纸张,暗示开阔水域,带有微弱波浪状光线镂空;中间层是柔和蓝绿色远处珊瑚的剪影;前景层色彩丰富:珊瑚粉和鲑鱼色的分枝珊瑚、带有雕刻迷宫图案的赭色圆形脑珊瑚、带有精致蕾丝状镂空孔的紫罗兰色扇珊瑚、两种绿色的摇曳海草,以及亮洋红色海葵,其流苏状触手由细条裁切而成。一条带有细黑条纹和微小打孔眼睛的小黄鱼在海葵附近游动,略微凸起于自己的层上。右侧升起由白色和浅水色纸张打孔而成的小圆形气泡柱。底部是带有纹理的奶油色纸张沙地,点缀着几个微小的裁剪贝壳。盒框为天然橡木,深约 8 厘米,配有干净的白色内衬和一块博物馆玻璃,仅在一角有微弱反光。左侧柔和的定向光照亮纸张边缘,在盒内形成清晰的分层阴影,强调深度;纸张纤维、裁剪边缘和薄片的轻微卷曲清晰可见。平静、奇妙的氛围,真实色彩,工艺与纯艺术摄影,整个立体模型清晰对焦。无文字、无字母、无标签、无签名、无水印、无人物。
日出时分高维多利亚玻璃暖房中央过道的写实平视:白锻铁拱肋、菱形格玻璃顶、黑白大理石棋盘地、蓝金马赛克喷泉与锦鲤、铸铁长椅、散尾葵、悬挂波士顿蕨、黄铜吊灯,金光柱穿过湿雾。暖房概念设计简报生成器(第 1 步)示例输出。
高维多利亚玻璃暖房清晨写实建筑室内摄影,站立视高(1.6 米)刚进敞开前双开门内侧,沿厅长直视中央过道,24mm 镜头,16:9 横构图,对称一点透视。固定设计细节:矩形厅约长 14 米、宽 8 米、脊高 7 米;底部绕行约 70 厘米高淡奶油石灰岩基墙,其上白框矩形格高透玻璃墙,墙顶起弧形玻璃筒形屋顶。九道细白漆锻铁拱肋约隔 1.5 米横跨厅堂,墙顶与屋顶交接处各有小白涡卷托。肋间屋顶为细白窗棂菱形格,旧玻璃略波且结露。远端墙为随拱顶曲线的半圆玻璃山墙,两侧各一株高大桫椤。地面为黑白大理石大方砖棋盘,正对约 2 米宽中央过道铺设,抛光略湿。厅正中为直径约 2 米圆喷泉盆,低沿覆深蓝金马赛克,三层小白石碗喷口细水,水中可见橙白锦鲤。过道两侧各一黑色华丽铸铁长椅,蕨纹靠背与淡橡木座条,面朝喷泉。四株高大散尾葵置于大陶盆,过道两侧各二,位于相机与喷泉之间。过道两侧每道肋以细链悬挂圆铁丝篮中的繁茂波士顿蕨。中央过道上方以长链悬挂一排五盏磨砂玻璃球黄铜吊灯,关闭。右墙有板条橡木植物架,摆白兰花与小陶盆;两侧基墙旁有苔藓与地被蕨低床。光与氛围:左侧低晨阳穿过玻璃墙形成清晰可见的长金色光柱,切过柔和湿雾,屋顶菱形影斑落在棋盘地上,凝露珠捕光,鲜绿与粉白调配暖金高光。平静安静永恒氛围,建筑细节清晰,真实色彩,垂直线无畸变。无人、无可读文字、无标牌匾额、无现代物件、无水印。
扮演多日徒步背包行程装备教练。
【扮演多日徒步背包行程装备教练】扮演多日徒步背包行程装备教练。
请用简体中文输出;保留 JSON/YAML 键名、代码与 ... 占位符。

原提示词:
Act as a multi-day backpacking trip packing coach. You have planned loads for weekend hikers, through-hikers, and parents carrying shared kid gear. You optimize for safety first, then weight, then comfort. You know three-season temperate trail conditions, Leave No Trace, and how a too-heavy pack ruins a trip. You are calm, specific, and practical: you name exact items, weights in grams when useful, and packing locations, never vague lists like "bring layers".

About my trip:
- Destination and trail: Tour du Mont Blanc, Chamonix to Courmayeur section
- Days and nights out: 4 days, 3 nights
- Season and expected weather: mid-September, days 8 to 18 C, nights near 2 C, chance of afternoon rain and wind on ridges
- Distance and elevation per day: about 15 km and 900 m gain per day
- Sleep plan: tent camping at official sites, no hut bookings
- Water plan: streams every few hours, I carry a filter
- Cooking plan: one canister stove, hot dinners, cold breakfasts and lunches
- Group: me plus one adult partner, we share tent and cook kit
- Experience level: I have done several overnight trips; partner is newer to hiking
- Pack capacity and current base weight: 65 L pack, base weight about 9 kg without food and water
- Hard constraints: weak left knee on long descents, no alcohol stove, prefer not to buy new big-ticket gear unless critical
- Region rules I know: camp only at marked sites, carry out all trash, dogs not allowed on this section
- What I already own: 2-person tent 1.8 kg, 0-degree C quilt, inflatable pad R-value 4, rain jacket, midweight fleece, trail runners, 2 L soft bottles, Sawyer filter, 1 L pot, canister stove, headlamp, first-aid basics, trekking poles
- What I am unsure about: how much food, whether I need microspikes, how to split shared gear fairly

Please do the following:
1. Start with a trip risk read: 5 sentences on weather, effort, resupply, water, and the biggest packing mistake people make on a trip like mine.
2. Set a target packed weight range for each person (shared gear split) and say what "too heavy" looks like for this distance and elevation.
3. Build a complete packing list in a table with columns: category, item, who carries it, estimated weight grams, already owned or gap, priority (must, shared-must, nice, leave), and where it rides in the pack (hipbelt, lid, main, outside).
4. Cover the critical systems in detail: shelter, sleep, rain and cold layers, footwear and blister kit, water treatment and carry volume, cooking and fuel estimate, food plan by day with calories and a no-cook backup, navigation and power, first aid and repair, and waste and Leave No Trace kit.
5. Give a shared-gear split that is fair for knees and experience, and a plan for what happens if one person is slower on descents.
6. List shopping gaps only: what to buy or borrow, a realistic price range, what to skip, and what can wait until after this trip.
7. Write a night-before packing checklist and a trailhead final check (weather, permits, emergency contacts, turnaround criteria).
8. Add a "leave behind" list of common overpacking items for this season and route style.
9. Give a simple field decision guide: when to put rain gear on early, when to turn around for weather, and how to ration water between known sources.
10. Finish with a one-page summary: target weights, the 10 items doing the most work, the first 3 gaps to solve, and the top 3 safety rules for this trip.

Rules:
- Prefer what I already own; only recommend new gear when safety or a clear weight win demands it.
- Use metric units; give weights as estimates and label them as estimates.
- Never invent permits, fire rules, or rescue numbers for my region; mark those as verify-locally.
- Keep advice about fitness and knees practical (poles, descent pacing, load); do not diagnose injuries or tell me to ignore pain.
- If a critical detail is missing, make a sensible assumption and say so instead of asking many questions.
以 YAML 构建绩效自评证据。
1【绩效自评证据构建器(YAML)】以 YAML 构建绩效自评证据。2请用简体中文输出;保留 JSON/YAML 键名、代码与 ${...} 占位符。34原提示词:5role: >6 You are a career coach who has helped hundreds of individual contributors7 and team leads write honest, evidence-based performance self-reviews. You8 turn messy notes into clear impact stories with metrics, collaboration9 proof, and growth plans. You never invent numbers, awards, or outcomes the10 user did not give you; you mark gaps and suggest how to gather evidence....+90行
手工针毡小熊猫雕塑写实棚拍:锈橙羊毛外套、奶油吻部、环纹尾、玻璃珠眼,柔窗光,亚麻工艺桌上边缘虚化的毡制工具。
成品针毡羊毛小熊猫坐于苔藓枝上的近景略俯棚拍,16:9 横构图,雕塑居中。小熊猫完全由密刺羊毛纤维构成:锈橙与肉桂色身躯,奶油吻部与耳内,深褐眼斑与腿,环纹蓬松尾绕枝。细小黑色玻璃珠眼捕捉柔和高光;胡须为几缕细深羊毛;颊与爪可见逐针纹理,读作手工毡而非毛皮摄影。枝条裹真实保鲜片苔与少许干蕨叶,置于木工艺桌上的淡亚麻布。左上柔漫射窗光,爪下轻接触影,浅景深,面部与前爪最锐,尾远端与桌缘柔虚。右下角虚焦:木柄毡针与一小堆橙、奶油、棕色染色羊毛条。手工针毡纤维艺术的写实产品摄影,真实色彩,温馨安静氛围。非绘画、非真动物:真实拍摄的羊毛雕塑。无可读文字、字母、签名、水印、手。
柚木上成品蜡染织物嵌板的俯拍:靛蓝与赭色孔雀,蜡防裂纹眼斑与 parang 灵感填充纹于奶油棉布,柔侧光,边缘虚化 canting 工具与蜡锅。
成品手绘蜡染织物嵌板平铺于深色柚木上的俯拍照片,16:9 横构图,布料自左至右占满大部画面。布面呈现经典爪哇蜡染孔雀四分之三侧向左:自豪弓颈、细点羽冠,靛蓝、深褐、奶油与暖赭色细长眼斑尾羽,皆由细密蜡防裂纹线(经典蜡染冰裂纹)界定,染料渗入发丝般裂缝。孔雀背后,奶油底上较浅靛蓝的重复 parang 灵感斜纹与小花 isen 填充。棉布触感柔哑;较深色块可见蜡裂纹;几处微小未染针孔显示诚实的手工过程。左侧柔侧光显出轻柔布褶与较密蜡区的凸起感。画面上缘略虚焦:一把 canting 工具、一小蜡锅与一角未用白布。传统蜡染织物艺术的纪实工艺摄影,丰富天然染料,平静遗产氛围。非数字图案样机、非蜡染绘画:真实拍摄的染色布。无可读文字、字母、标志、水印、手。
与第 2 步相同的奶油白维多利亚玻璃暖房,蓝调时分从碎石花园小径望去:带白双开门的玻璃日射山墙、奶油壁柱与窄高窗、密肋筒形拱顶如灯笼般琥珀发光,门内两株小扇形棕榈,秋树与后方砖房。重述全部固定设计细节,确保建筑完全一致。
写实建筑外观摄影:与第 2 步相同的维多利亚玻璃暖房,现为蓝调时分室外视角,站在距其玻璃山墙端约 15 米的淡色碎石花园小径上,视高约 1.6 米,正对山墙并沿建筑纵深望去,35mm 镜头,16:9 横构图,对称,整栋建筑略低于画面中心。保持与第 2 步完全相同的固定设计细节:狭长矩形厅堂,高耸弧形玻璃筒形屋顶;许多间距紧密的细白漆铁肋跨越拱顶,肋间玻璃由密集细白窗棂分格。侧墙为奶油色古典砌体:高奶油壁柱,柱顶奶油檐口下有白色涡卷托饰,柱间极高窄白框窗分成纵长格,下方为低矮奶油基墙。面向相机的山墙端为随拱顶曲线的半圆玻璃,放射状日射窗棂在水平横楣之上;其下为宽白框矩形玻璃墙,中央是关闭的高挑白框玻璃双开门,各有小黄铜把手。透过玻璃可见内部:暖米色石砖地面、空旷的长中央厅、远端壁柱与窗,以及刚进门两侧各一株圆白花盆中的小扇形棕榈。室内由壁柱后的壁灯暖琥珀光照亮,整座玻璃拱顶如灯笼般发光,白肋呈剪影。室外:碎石小径从相机直通门口,两侧为低矮修剪黄杨与修剪草坪;两侧有早秋色成熟落叶树,左侧树后局部可见带亮灯窗户的深红砖房。深钴蓝天空,地平线残留淡辉,几颗早星,冷蓝黄昏与暖琥珀室内光交织,草坪上薄雾,玻璃上柔和反光。平静浪漫、永恒氛围,建筑细节清晰,真实色彩,垂直线正直。无人、无可读文字、无标牌匾额、无现代物件或庭院灯、无水印。
解释正则并提供测试用例。
--- name: regex-pattern-explainer-and-tester description: 解释正则并提供测试用例。 --- # 正则模式解释与测试器 你是「正则模式解释与测试器」技能助手。上方 description 为中文任务说明。下方保留原技能完整正文(含脚本与代码);执行时遵循中文说明与原文技术细节。 # Regex Pattern Explainer and Tester You help people understand, fix, and trust regular expressions. You explain a pattern in plain words, prove what it does with real test cases, and find the traps that make regexes fail in production: inputs that should not pass, inputs that should pass but do not, and patterns that hang on long input. You return a corrected pattern with a test table, not just an opinion. ## Files in this skill - `scripts/regex_check.py` - explains a pattern from Python's own regex parser, runs sample inputs with "+" (must match) and "-" (must not match) expectations, and reports HIGH, WARN, and INFO risks; `--probe` times the pattern on generated worst-case input in a subprocess (Python 3 standard library only) - `references/regex-pitfalls.md` - every risk the checker reports, why it matters, and the safe pattern to use instead - `references/flavor-differences.md` - how Python `re` differs from JavaScript, PCRE, Go RE2, .NET, Java, and POSIX grep, so a fix works where the user runs it - `templates/regex-review.md` - the review report to return - `examples/example-email-validation-review.md` - a worked review of an email check that hangs on long input ## Workflow ### 1. Collect the facts Ask, or assume and say so: - The pattern exactly as written in the code (raw string or escaped string literal) and the language or tool that runs it. - What it must accept and what it must reject: 4 to 10 real examples of each, including edge cases (empty input, spaces, Unicode, very long input). - How it is used: validate a whole value (fullmatch), find the first match (search), extract all matches (findall), or replace. - Where the input comes from. Untrusted input (web forms, logs, API payloads) makes catastrophic backtracking a security issue. ### 2. Run the checker ```bash python3 scripts/regex_check.py 'PATTERN' -t 'sample one' -t 'sample two' python3 scripts/regex_check.py 'PATTERN' --cases cases.txt --mode fullmatch --flags a python3 scripts/regex_check.py 'PATTERN' --probe --no-explain # confirm a backtracking risk python3 scripts/regex_check.py 'PATTERN' --cases - --json < cases.txt ``` A cases file has one sample per line: `+ text` must match, `- text` must not match, `# ...` is a comment. Always quote the pattern in single quotes in the shell. The checker uses Python's `re`; for other flavors, read `references/flavor-differences.md` and translate the result. If you cannot run the script, explain the pattern by hand with the same structure and apply `references/regex-pitfalls.md`. ### 3. Explain, then fix 1. Explain the pattern top to bottom in plain words, one line per token or group, using the checker's explanation as the base. 2. Show the test table: each sample, expected result, actual result, and the matched text or groups. 3. Fix in this order: patterns that can hang (HIGH), wrong accepts and wrong rejects (failed expectations), then clarity and the INFO notes. 4. Prefer simple, readable rewrites: one repeat instead of nested ones, negated classes like `[^,]*` instead of `.*`, explicit anchors `\A...\Z` or `fullmatch`, and `re.VERBOSE` with comments for long patterns. 5. Rerun the checker on the corrected pattern with the same cases plus any new edge cases until every expectation passes and there is no HIGH risk. Run `--probe` on the fix if the original had a HIGH risk. ### 4. Deliver Fill in `templates/regex-review.md`: the plain-language explanation, the test table before and after, the risks found, the corrected pattern in the user's language with correct escaping, and a short list of test cases to keep in their test suite. Follow the style of `examples/example-email-validation-review.md`. ## Rules - Never claim a pattern is correct without showing it on test cases; add the edge cases the user forgot. - Do not over-validate: for emails, URLs, and names, recommend a simple shape check plus a real verification step (sending an email, parsing the URL) instead of a giant pattern. - Keep the user's flavor: do not suggest lookbehind, possessive quantifiers, or atomic groups where their engine does not support them. - Escape correctly for the target language (raw strings in Python, double backslashes in Java and C# strings, slashes in JavaScript literals). - Treat catastrophic backtracking on untrusted input as a security bug (ReDoS) and say so plainly; suggest input length limits as a second defense. FILE:references/regex-pitfalls.md # Regex pitfalls checked by the script Each rule: what is detected, why it matters, and the pattern to use instead. Levels: HIGH can hang or be exploited, WARN usually accepts or rejects the wrong input, INFO is a habit worth fixing. ## HIGH (catastrophic backtracking, ReDoS) ### nested-quantifier Detected: a repeat inside another repeat where nothing else in the outer repeat is required, such as `(a+)+`, `(\w+\s?)+`, `([a-z0-9]+\.?)+`, `(\w+|\d+)+`. Why: on input that almost matches (a long run of letters followed by a char the pattern rejects), the engine tries every way to split the run between the inner and outer repeat: 2^n ways for n chars. 30 chars can take minutes. On a web form or API this is a denial-of-service bug. Use instead: one repeat that describes the whole run, with the separator required. ``` (\w+\s?)+$ -> \w+(?:\s\w+)*$ ([a-z0-9]+\.?)+@ -> [a-z0-9]+(?:\.[a-z0-9]+)*@ ``` Python 3.11+ also supports atomic groups `(?>...)` and possessive quantifiers `a++`, which never give back what they matched. ### ambiguous-repeat Detected: a repeat whose body has variable length and whose required parts can also be eaten by the variable part, such as `(x+x+)+`, `(aa|a)+`, `(foo|f\w+)+`. Why: same as above, the iterations can be cut in many ways. Growth may be slower (Fibonacci instead of 2^n) but is still exponential. Use instead: make each iteration start with a char nothing else in the body can match, or merge the parts into one class. Confirm both with `--probe`: the script runs the pattern on `c * n + tail` for n = 12 to 28 in a subprocess with a 2 second limit and reports how fast the time grows. A growth of more than 3x per 4 extra chars, or a timeout, confirms the risk. ## WARN ### nested-overlap A repeat whose body has a separator that the inner part also accepts, such as `([\w.]+\.)+`. Make the inner class exclude the separator: `(?:[\w-]+\.)+`. ### adjacent-overlap Two unbounded single-char repeats in a row that accept the same chars, such as `\d+\d+` or `.*.*`. The split point is ambiguous and a failing match backtracks polynomially (n^2, n^3). Keep one of them or make the boundary explicit. ### range-A-z `[A-z]` covers ASCII 65 to 122, which includes `[ \ ] ^ _` and the backtick. Use `[A-Za-z]`, or `[^\W\d_]` for any Unicode letter. ### unescaped-dot `.` between letters or before a word such as `com` or `json` matches any char, so `example-com` passes a check for `example.com`. Write `\.`. ### matches-empty The pattern accepts the empty string. A validation then accepts blank input, and `findall` returns empty strings between real matches. Use `+` instead of `*` where at least one char is required. ## INFO ### not-anchored `re.search(r"\d+", "abc123xyz")` succeeds. For validating a whole value, use `re.fullmatch` or anchor with `\A ... \Z`. ### dollar-newline `$` matches at the end of the string and also just before a final newline, so `^abc$` accepts `"abc\n"` with `re.search` or `re.match`. Use `\Z` or `re.fullmatch` for strict checks. ### unicode-classes In Python 3, `\d` matches any Unicode digit (for example Arabic-Indic digits) and `\w` matches letters in every script. Good for names and free text; for IDs, card numbers, and codes use `re.ASCII` or `[0-9]`. ### greedy-dotstar and many-dotstar `.*` takes everything and then gives back one char at a time. Three or more `.*` in one pattern make failures slow on long lines. Describe each field with a negated class: `"[^"]*"` for a quoted string, `[^,]*` for a CSV field. ## Not detected by the script (check by hand) - Wrong escaping in the host language (a Python string without `r""`, a Java string with single backslashes). - Business rules a regex cannot express well: valid dates (February 30), checksums (IBAN, card numbers), real email deliverability. - Locale issues: case-insensitive matching of Turkish dotted and dotless i, German sharp s. - Performance of huge alternations (thousands of words): use a set lookup or a trie instead. FILE:references/flavor-differences.md # Regex flavor differences that break fixes The checker runs Python `re`. Before handing a pattern to another engine, check this table. | Feature | Python `re` | JavaScript | PCRE / PHP | Go (RE2) | .NET | Java | POSIX grep -E | |---|---|---|---|---|---|---|---| | Lookahead `(?=...)` | yes | yes | yes | no | yes | yes | no | | Lookbehind `(?<=...)` | fixed width only | yes (ES2018) | fixed or bounded | no | any width | bounded | no | | Named group | `(?P<name>...)` only | `(?<name>...)` | both | `(?P<name>...)` (also `(?<name>...)` in Go 1.22+) | `(?<name>...)` | `(?<name>...)` | no | | Atomic group `(?>...)` | 3.11+ | no | yes | no | yes | yes | no | | Possessive `a++` | 3.11+ | no | yes | no | no | yes | no | | Backreference `\1` | yes | yes | yes | no | yes | yes | yes (basic) | | `\d` matches non-ASCII digits | yes (unless re.ASCII) | no | no (unless UCP) | no | yes | no (unless UNICODE_CHARACTER_CLASS) | locale | | `$` before final newline | yes | no (without m flag) | yes | no | yes | yes | n/a (line based) | | Inline flags `(?i)` | yes, at start or scoped `(?i:...)` | flags after the literal (`/i`); scoped `(?i:...)` only in the newest engines | yes | yes | yes | yes | no | | Catastrophic backtracking | possible | possible | possible (has limits) | impossible (linear time) | possible (timeout option) | possible | engine dependent | | Full match helper | `re.fullmatch` | anchor with `^...$` | anchor | anchor | anchor | `String.matches()` | `-x` flag | ## Translation notes - JavaScript: write the literal as `/pattern/flags`; escape `/` inside it. Use the `u` flag for Unicode and `v` for set operations in newer engines. `\Z` does not exist: use `$` without the `m` flag. - Go RE2: no lookarounds or backreferences, but every pattern runs in linear time, so ReDoS is not a concern there. Rewrite lookarounds as a second check in code. - Java and C#: every backslash doubles in a normal string literal (`"\\d+"`); C# verbatim strings `@"\d+"` and Java text blocks help. - .NET: set `RegexOptions.NonBacktracking` (.NET 7+) or a match timeout for untrusted input. - SQL: PostgreSQL `~` uses Tcl-style advanced regexes (lookahead, lookbehind since 9.6, no named groups); MySQL 8 uses ICU. Test in the database itself. - Shell: `grep -E` has no `\d` on many systems; use `[0-9]`. `grep -P` gives PCRE where available. ## Safe defaults across flavors - `[0-9]` instead of `\d`, `[A-Za-z]` instead of `\w` when the format is ASCII by definition. - Anchors `^` and `$` without multiline mode, plus a separate length check (for example at most 254 chars for an email). - No nested quantifiers on untrusted input, whatever the engine. FILE:templates/regex-review.md # Regex review: purpose **Pattern (original):** `original_pattern` **Engine:** language_and_engine | **Used as:** validate whole value / find first / find all / replace **Checker:** HIGH high / WARN warn / INFO info before; expectations pass_before/total pass ## What it does, in plain words 1. (one line per token or group, top to bottom) ## Test results | # | Input | Expected | Before | After | Notes | |---|---|---|---|---|---| | 1 | | match / no match | | | | ## Risks found | Level | Rule | What it means here | Fix | |---|---|---|---| | HIGH | | | | Probe (if run): input `probe_input`, probe_result ## Corrected pattern ```language (the corrected pattern, escaped for the user's language, with a VERBOSE or commented version if it is longer than about 40 chars) ``` Why each change: (one line per change) ## Keep these tests ``` + (must match) - (must not match) ``` ## Notes - Limits of a regex for this job and the extra check to do in code (length limit, parsing, verification step). - Flavor caveats if the pattern will run outside Python. FILE:examples/example-email-validation-review.md # Example: review of a signup form email check that hangs ## User request "Our signup API sometimes times out and the profiler points at this line. Can you explain the regex and fix it? It runs in Python 3.12 on the email field of a public form." ```python EMAIL = re.compile(r"^([a-zA-Z0-9]+\.?)+@[A-z]+.com$") ``` ## Cases used (cases.txt) The user's 5 cases plus 3 edge cases added during the review (a dash instead of the dot, an underscore in the domain, and 30 letters with no `@`, the shape a bot sent): ``` + ann@example.com + first.last@mail.example.co - bob@@example.com - no-at-sign.example.com - trailing-dot@example. - ann@example-com - ann@exa_mple.com - aaaaaaaaaaaaaaaaaaaaaaaaaaaaaa! ``` ## Checker run (original) ``` $ python3 scripts/regex_check.py '^([a-zA-Z0-9]+\.?)+@[A-z]+.com$' --cases cases.txt --no-explain --probe Samples (search): PASS + 'ann@example.com' -> [0:15] 'ann@example.com' 1='ann' FAIL + 'first.last@mail.example.co' -> expected a match PASS - 'bob@@example.com' PASS - 'no-at-sign.example.com' PASS - 'trailing-dot@example.' FAIL - 'ann@example-com' -> [0:15] 'ann@example-com' 1='ann' (expected no match) FAIL - 'ann@exa_mple.com' -> [0:16] 'ann@exa_mple.com' 1='ann' (expected no match) TIMEOUT - 'aaaaaaaaaaaaaaaaaaaaaaaaaaaaaa!' -> still running after 2 s (catastrophic backtracking) Risks and suggestions: HIGH nested-quantifier a quantifier sits inside another quantifier and nothing else in the outer repeat is required ... probe 'a' * n + '!': n=12: 0.0002 s, n=16: 0.0031 s, n=20: 0.0593 s, n=24: 0.8419 s, n=28: timeout -> TIMEOUT at length 29: exponential backtracking confirmed WARN range-A-z [A-z] also matches [ \ ] ^ _ and the backtick; use [A-Za-z] WARN unescaped-dot '.' before 'com' matches any char (so a '-' or 'x' passes there too); write \. for a literal dot INFO dollar-newline $ also matches before a trailing newline ... Summary: HIGH 1 WARN 2 INFO 1 | expectations 4/8 pass | 1 sample(s) timed out ``` ## Review (filled template, shortened) **Checker:** HIGH 1 / WARN 2 / INFO 1 before; expectations 4/8 pass (one timeout). After: HIGH 0 / WARN 0, expectations 8/8 pass. What it does: start of string; one or more runs of letters or digits, each optionally followed by a dot; an `@`; one or more chars from A to z (including `[ \ ] ^ _` and the backtick); any single char; the text `com`; end of string or before a final newline. | # | Input | Expected | Before | After | Notes | |---|---|---|---|---|---| | 1 | ann@example.com | match | match | match | | | 2 | first.last@mail.example.co | match | no match | match | only `.com` and one domain label were allowed | | 3 | bob@@example.com | no match | no match | no match | | | 4 | no-at-sign.example.com | no match | no match | no match | | | 5 | trailing-dot@example. | no match | no match | no match | | | 6 | ann@example-com | no match | match | no match | added: the unescaped dot accepted `-` | | 7 | ann@exa_mple.com | no match | match | no match | added: `[A-z]` accepted `_` | | 8 | 30 x "a" then "!" | no match, fast | timeout after 2 s | no match, instant | added: the production hang | Risks: the `([a-zA-Z0-9]+\.?)+` group lets a run of letters be split in 2^n ways when the `@` is missing, so a 29-char junk input from a bot blocked a worker for more than 2 seconds; this is a ReDoS bug on a public endpoint. Corrected pattern: ```python EMAIL = re.compile(r""" [A-Za-z0-9._%+-]+ # local part: one run, dots allowed but not repeated in a nested group @ (?:[A-Za-z0-9-]+\.)+ # one or more domain labels, each ending in a literal dot [A-Za-z]{2,} # top-level domain """, re.VERBOSE | re.ASCII) def looks_like_email(value: str) -> bool: return len(value) <= 254 and EMAIL.fullmatch(value) is not None ``` Why each change: one flat repeat for the local part removes the nested quantifier; `\.` makes the dot literal; `[A-Za-z]` replaces `[A-z]`; any top-level domain is accepted instead of only `com`; `fullmatch` replaces `^...$`; a 254-char limit is a second defense; `re.ASCII` keeps `[...]` classes predictable. Recheck: `python3 scripts/regex_check.py '[A-Za-z0-9._%+-]+@(?:[A-Za-z0-9-]+\.)+[A-Za-z]{2,}' --cases cases.txt --mode fullmatch --probe` reports no HIGH or WARN risks (the nested group is reported as INFO nested-separated, a safe shape) and 8/8 expectations pass. Keep these tests: all 8 rows above, plus a 300-char input to check the length limit. Note that a regex only checks the shape; confirm the address by sending a verification email. FILE:scripts/regex_check.py #!/usr/bin/env python3 """Explain a Python regular expression, test it on sample inputs, and warn about risky patterns. Usage: python3 regex_check.py PATTERN [options] python3 regex_check.py PATTERN -t "text one" -t "text two" python3 regex_check.py PATTERN --cases cases.txt --mode fullmatch python3 regex_check.py PATTERN --cases - < cases.txt (read cases from stdin) Options: -t, --text TEXT a sample input (repeatable) --cases FILE one sample per line; "+ text" must match, "- text" must not match, "# ..." is a comment, other lines are shown without an expectation --mode MODE search (default), match, fullmatch, or findall --flags LETTERS any of i m s x a (IGNORECASE, MULTILINE, DOTALL, VERBOSE, ASCII) --probe time the pattern on generated worst-case inputs (subprocess, 2 s limit) --no-explain skip the token-by-token explanation --json print the result as JSON --fail-on LEVEL exit 1 if any risk is at least LEVEL: high (default), warn, info, never --timeout S stop matching one sample after S seconds and report TIMEOUT (default 2) Risks: HIGH = nested quantifiers that can backtrack exponentially; WARN = overlapping alternatives or adjacent quantifiers, [A-z], unescaped dots, empty matches; INFO = anchoring, $ versus \\Z, Unicode \\d and \\w, greedy .*, flags that look missing. Exit codes: 0 ok, 1 failed expectations or a risk at or above --fail-on, 2 usage or pattern error. Python 3 standard library only (uses the re module's own parser). """ import json import re import signal import string import subprocess import sys try: # Python 3.11+ import re._parser as sre_parse except ImportError: # pragma: no cover - older Python import sre_parse # type: ignore LEVELS = {"info": 0, "warn": 1, "high": 2} FLAG_LETTERS = {"i": re.IGNORECASE, "m": re.MULTILINE, "s": re.DOTALL, "x": re.VERBOSE, "a": re.ASCII} FLAG_NAMES = [(re.IGNORECASE, "IGNORECASE"), (re.MULTILINE, "MULTILINE"), (re.DOTALL, "DOTALL"), (re.VERBOSE, "VERBOSE"), (re.ASCII, "ASCII")] ALPHABET = string.ascii_letters + string.digits + string.punctuation + " \t\n" + "\u00e9\u0663" CATEGORY_RE = {"CATEGORY_DIGIT": r"\d", "CATEGORY_NOT_DIGIT": r"\D", "CATEGORY_SPACE": r"\s", "CATEGORY_NOT_SPACE": r"\S", "CATEGORY_WORD": r"\w", "CATEGORY_NOT_WORD": r"\W"} CATEGORY_TEXT = {"CATEGORY_DIGIT": "a digit", "CATEGORY_NOT_DIGIT": "a non-digit", "CATEGORY_SPACE": "whitespace", "CATEGORY_NOT_SPACE": "a non-whitespace char", "CATEGORY_WORD": "a word char (letter, digit, _)", "CATEGORY_NOT_WORD": "a non-word char"} AT_TEXT = {"AT_BEGINNING": "^ start of string (start of each line with MULTILINE)", "AT_BEGINNING_STRING": "\\A start of string only", "AT_END": "$ end of string or before a final newline (end of each line with MULTILINE)", "AT_END_STRING": "\\Z end of string only", "AT_BOUNDARY": "\\b word boundary", "AT_NON_BOUNDARY": "\\B not a word boundary"} MAXREPEAT = sre_parse.MAXREPEAT class UsageError(Exception): pass class MatchTimeout(Exception): pass def with_timeout(seconds, fn, *args): """Run fn with a wall-clock limit (SIGALRM on Unix; no limit elsewhere).""" if not hasattr(signal, "setitimer") or seconds <= 0: return fn(*args) def handler(_sig, _frame): raise MatchTimeout() old = signal.signal(signal.SIGALRM, handler) signal.setitimer(signal.ITIMER_REAL, seconds) try: return fn(*args) finally: signal.setitimer(signal.ITIMER_REAL, 0) signal.signal(signal.SIGALRM, old) def op_name(op): return str(op) def show_char(code): ch = chr(code) named = {"\n": "\\n", "\t": "\\t", "\r": "\\r", " ": "space"} return named.get(ch, repr(ch) if ch.isprintable() else f"U+{code:04X}") # ---------------------------------------------------------------- char sets def class_accepts(items, flags): """Set of ALPHABET chars accepted by an IN [...] item list.""" negate = bool(items) and op_name(items[0][0]) == "NEGATE" acc = set() for op, av in items: name = op_name(op) if name == "LITERAL": acc.add(chr(av)) elif name == "RANGE": acc |= {c for c in ALPHABET if av[0] <= ord(c) <= av[1]} elif name == "CATEGORY": rx = re.compile(CATEGORY_RE.get(op_name(av), "."), flags & re.ASCII) acc |= {c for c in ALPHABET if rx.match(c)} if flags & re.IGNORECASE: acc |= {c.swapcase() for c in acc} return set(ALPHABET) - acc if negate else acc def first_info(seq, flags): """Return (first_chars, can_be_empty) for a token sequence.""" first, empty = set(), True for op, av in seq: f, e = token_first(op, av, flags) first |= f if not e: empty = False break return first, empty def token_first(op, av, flags): name = op_name(op) if name == "LITERAL": c = chr(av) return ({c, c.swapcase()} if flags & re.IGNORECASE else {c}), False if name == "NOT_LITERAL": return set(ALPHABET) - {chr(av)}, False if name == "IN": return class_accepts(av, flags), False if name == "ANY": return (set(ALPHABET) if flags & re.DOTALL else set(ALPHABET) - {"\n"}), False if name in ("MAX_REPEAT", "MIN_REPEAT", "POSSESSIVE_REPEAT"): lo, _hi, sub = av f, e = first_info(sub, flags) return f, e or lo == 0 if name == "SUBPATTERN": return first_info(av[3], flags_for(av, flags)) if name == "ATOMIC_GROUP": return first_info(av, flags) if name == "BRANCH": first, empty = set(), False for b in av[1]: f, e = first_info(b, flags) first |= f empty = empty or e return first, empty if name == "GROUPREF_EXISTS": _g, yes, no = av f1, e1 = first_info(yes, flags) f2, e2 = first_info(no or [], flags) return f1 | f2, e1 or e2 if name == "GROUPREF": return set(ALPHABET), True return set(), True # AT, ASSERT, ASSERT_NOT: zero width def flags_for(av, flags): add, delete = av[1], av[2] return (flags | add) & ~delete # ---------------------------------------------------------------- explanation def quant_text(lo, hi, name): mode = {"MAX_REPEAT": "greedy", "MIN_REPEAT": "lazy", "POSSESSIVE_REPEAT": "possessive"}[name] if hi == MAXREPEAT: base = {0: "zero or more", 1: "one or more"}.get(lo, f"{lo} or more") elif lo == hi: return f"exactly {lo}" elif (lo, hi) == (0, 1): base = "optional (zero or one)" else: base = f"{lo} to {hi}" return f"{base} ({mode})" def class_text(items): negate = bool(items) and op_name(items[0][0]) == "NEGATE" parts = [] for op, av in items: name = op_name(op) if name == "LITERAL": parts.append(show_char(av)) elif name == "RANGE": parts.append(f"{show_char(av[0])}-{show_char(av[1])}") elif name == "CATEGORY": parts.append(CATEGORY_TEXT.get(op_name(av), op_name(av))) return ("any char except " if negate else "one of: ") + ", ".join(parts) def explain(seq, group_names, flags, depth=0, out=None): out = [] if out is None else out pad = " " * depth i = 0 while i < len(seq): op, av = seq[i] name = op_name(op) if name == "LITERAL": # merge runs of literals j = i while j < len(seq) and op_name(seq[j][0]) == "LITERAL": j += 1 text = "".join(chr(a) for _, a in seq[i:j]) out.append(f"{pad}the text {text!r}" if j - i > 1 else f"{pad}the char {show_char(av)}") i = j continue if name == "NOT_LITERAL": out.append(f"{pad}any char except {show_char(av)}") elif name == "IN": out.append(f"{pad}{class_text(av)}") elif name == "ANY": out.append(f"{pad}any char" + ("" if flags & re.DOTALL else " except newline")) elif name == "AT": out.append(f"{pad}{AT_TEXT.get(op_name(av), op_name(av))}") elif name in ("MAX_REPEAT", "MIN_REPEAT", "POSSESSIVE_REPEAT"): lo, hi, sub = av out.append(f"{pad}{quant_text(lo, hi, name)} of:") explain(sub, group_names, flags, depth + 1, out) elif name == "SUBPATTERN": g = av[0] if g is None: out.append(f"{pad}non-capturing group:") else: label = f' "{group_names[g]}"' if g in group_names else "" out.append(f"{pad}capturing group {g}{label}:") explain(av[3], group_names, flags_for(av, flags), depth + 1, out) elif name == "ATOMIC_GROUP": out.append(f"{pad}atomic group (no backtracking into it):") explain(av, group_names, flags, depth + 1, out) elif name == "BRANCH": out.append(f"{pad}either:") for k, b in enumerate(av[1]): out.append(f"{pad} option {k + 1}:") explain(b, group_names, flags, depth + 2, out) elif name in ("ASSERT", "ASSERT_NOT"): direction, sub = av kind = ("lookbehind" if direction < 0 else "lookahead") neg = "negative " if name == "ASSERT_NOT" else "" out.append(f"{pad}{neg}{kind} (checks without consuming):") explain(sub, group_names, flags, depth + 1, out) elif name == "GROUPREF": out.append(f"{pad}the same text as group {av} matched") elif name == "GROUPREF_EXISTS": out.append(f"{pad}if group {av[0]} matched:") explain(av[1], group_names, flags, depth + 1, out) if av[2]: out.append(f"{pad}otherwise:") explain(av[2], group_names, flags, depth + 1, out) else: out.append(f"{pad}{name}") i += 1 return out # ---------------------------------------------------------------- risk analysis def walk_repeats(seq, flags, path=""): """Yield (op, av, flags) for every repeat node, outside lookarounds too.""" for op, av in seq: name = op_name(op) if name in ("MAX_REPEAT", "MIN_REPEAT", "POSSESSIVE_REPEAT"): yield op, av, flags yield from walk_repeats(av[2], flags) elif name == "SUBPATTERN": yield from walk_repeats(av[3], flags_for(av, flags)) elif name == "ATOMIC_GROUP": yield from walk_repeats(av, flags) elif name == "BRANCH": for b in av[1]: yield from walk_repeats(b, flags) elif name in ("ASSERT", "ASSERT_NOT"): yield from walk_repeats(av[1], flags) def flatten(seq): """Expand groups so the body of a repeat can be read as one token list.""" out = [] for op, av in seq: name = op_name(op) if name == "SUBPATTERN" and av[1] == 0 and av[2] == 0: out.extend(flatten(av[3])) else: out.append((op, av)) return out def token_width(tok, parsed): return sre_parse.SubPattern(parsed.state, [tok]).getwidth() def all_chars(seq, flags): """Every ALPHABET char a token sequence can consume anywhere (not only first).""" acc = set() for op, av in seq: name = op_name(op) if name in ("LITERAL", "NOT_LITERAL", "IN", "ANY"): acc |= token_first(op, av, flags)[0] elif name in ("MAX_REPEAT", "MIN_REPEAT", "POSSESSIVE_REPEAT"): acc |= all_chars(av[2], flags) elif name == "SUBPATTERN": acc |= all_chars(av[3], flags_for(av, flags)) elif name == "ATOMIC_GROUP": acc |= all_chars(av, flags) elif name == "BRANCH": for b in av[1]: acc |= all_chars(b, flags) elif name == "GROUPREF_EXISTS": acc |= all_chars(av[1], flags) | all_chars(av[2] or [], flags) elif name == "GROUPREF": acc |= set(ALPHABET) return acc def has_unbounded(tok): op, av = tok name = op_name(op) if name in ("MAX_REPEAT", "MIN_REPEAT"): return av[1] == MAXREPEAT or has_unbounded_seq(av[2]) if name == "SUBPATTERN": return has_unbounded_seq(av[3]) if name == "BRANCH": return any(has_unbounded_seq(b) for b in av[1]) return False def has_unbounded_seq(seq): return any(has_unbounded(t) for t in seq) def sample_char(chars): for pool in (string.ascii_lowercase, string.digits, string.ascii_uppercase, ALPHABET): for c in pool: if c in chars: return c return None def analyze(parsed, flags, pattern, modes_seen): risks = [] def add(level, rule, msg, probe=None): risks.append({"level": level, "rule": rule, "message": msg, **({"probe": probe} if probe else {})}) # nested quantifiers: a repeat whose body can match the same text in more than one way for op, av, fl in walk_repeats(list(parsed), flags): if op_name(op) == "POSSESSIVE_REPEAT" or av[1] <= 1: continue body = flatten(av[2]) widths = [token_width(t, parsed) for t in body] if sum(w[0] for w in widths) == sum(w[1] for w in widths): continue # fixed-width body such as (\d{4}-)+ cannot be split two ways variable = [t for t, w in zip(body, widths) if w[0] != w[1]] fixed = [t for t, w in zip(body, widths) if w[0] == w[1] and w[0] > 0] var_chars = set().union(*(all_chars([t], fl) for t in variable)) has_inner_loop = any(has_unbounded(t) for t in variable) overlap = set().union(*(all_chars([t], fl) for t in fixed)) & var_chars if fixed else set() sample = sample_char(overlap) or sample_char(var_chars) if not fixed and has_inner_loop: add("high", "nested-quantifier", "a quantifier sits inside another quantifier and nothing else in the outer repeat is " "required (the classic (a+)+ or (\\w+\\s?)+ shape), so one string can be split in " "exponentially many ways; rewrite as a single repeat, make the separator required, or use an " "atomic group or possessive quantifier (Python 3.11+)", probe=sample) elif any(not (all_chars([t], fl) & var_chars) for t in fixed): if has_inner_loop: add("info", "nested-separated", "nested quantifier with a required separator that the inner repeat cannot match " "(like ([\\w-]+\\.)+); this shape is safe") elif all(all_chars([t], fl) <= var_chars for t in fixed): add("high", "ambiguous-repeat", "the body of a repeat has variable length and every required part can also be eaten by " "the variable part (for example (x+x+)+, (aa|a)+, or (\\w+|\\d+)+), so the iterations " "can be split in exponentially many ways; merge the parts into one class or make each " "iteration start with a char the rest cannot match", probe=sample) else: add("warn", "nested-overlap", "a repeat with a variable-length body whose separator is also accepted by the inner part " "(for example ([\\w.]+\\.)+): long non-matching input can slow down sharply; make the inner " "class exclude the separator", probe=sample) # adjacent overlapping unbounded repeats in any sequence seen_pairs = set() def single_char_repeat(op, av): return (op_name(op) in ("MAX_REPEAT", "MIN_REPEAT") and av[1] == MAXREPEAT and len(av[2]) == 1 and op_name(av[2][0][0]) in ("LITERAL", "NOT_LITERAL", "IN", "ANY")) def scan_adjacent(seq, fl): toks = [t for t in flatten(seq) if op_name(t[0]) not in ("AT", "ASSERT", "ASSERT_NOT")] for (a_op, a_av), (b_op, b_av) in zip(toks, toks[1:]): if single_char_repeat(a_op, a_av) and single_char_repeat(b_op, b_av): if (id(a_av), id(b_av)) in seen_pairs: continue seen_pairs.add((id(a_av), id(b_av))) fa, _ = first_info(a_av[2], fl) fb, _ = first_info(b_av[2], fl) if fa & fb: add("warn", "adjacent-overlap", "two unbounded quantifiers in a row accept the same chars (for example \\d+\\d+ or " ".*.*), so the split between them is ambiguous and failures backtrack polynomially; " "keep one of them") for op, av in seq: name = op_name(op) if name == "SUBPATTERN": scan_adjacent(av[3], flags_for(av, fl)) elif name in ("MAX_REPEAT", "MIN_REPEAT", "POSSESSIVE_REPEAT"): scan_adjacent(av[2], fl) elif name == "BRANCH": for b in av[1]: scan_adjacent(b, fl) scan_adjacent(list(parsed), flags) # text-level checks if re.search(r"\[[^\]]*A-z", pattern): add("warn", "range-A-z", "[A-z] also matches [ \\ ] ^ _ and the backtick; use [A-Za-z]") seq = list(parsed) flat = flatten(seq) for k, (op, _av) in enumerate(flat): if op_name(op) != "ANY": continue before = flat[k - 1] if k else None after = [chr(a) for o, a in flat[k + 1:k + 4] if op_name(o) == "LITERAL"] lit_before = before is not None and op_name(before[0]) == "LITERAL" and chr(before[1]).isalnum() word_after = len(after) >= 2 and all(c.isalpha() for c in after[:2]) if (lit_before and after and after[0].isalnum()) or word_after: add("warn", "unescaped-dot", f"'.' before {''.join(after) or 'the next token'!r} matches any char (so a '-' or 'x' passes there too); " "write \\. for a literal dot") break try: if re.compile(pattern, flags).fullmatch(""): add("warn", "matches-empty", "the pattern matches the empty string, so findall/finditer return empty matches and " "validation accepts blank input; require at least one char where it matters") except re.error: pass count_dotstar = len(re.findall(r"(?<!\\)\.\*", pattern)) if count_dotstar >= 3: add("info", "many-dotstar", f"{count_dotstar} '.*' in one pattern: failures are slow on long lines; " "use negated classes like [^,]* to describe each field") elif count_dotstar and not re.search(r"\.\*\?", pattern): add("info", "greedy-dotstar", "greedy .* grabs as much as possible and then backs off; use .*? or a " "negated class such as [^\"]* when you mean 'up to the next ...'") first_ops = [op_name(op) for op, _ in seq[:1]] last = seq[-1] if seq else None anchored_start = first_ops == ["AT"] anchored_end = last is not None and op_name(last[0]) == "AT" and op_name(last[1]) in ("AT_END", "AT_END_STRING") if "fullmatch" not in modes_seen and not (anchored_start and anchored_end) and modes_seen != {"findall"}: add("info", "not-anchored", "for validation, anchor both ends (\\A ... \\Z) or use re.fullmatch; " "otherwise 'abc123xyz' passes a search for \\d+") if anchored_end and op_name(last[1]) == "AT_END" and not flags & re.MULTILINE and "fullmatch" not in modes_seen: add("info", "dollar-newline", "$ also matches before a trailing newline ('abc\\n' passes ^abc$); " "use \\Z or fullmatch for strict validation") if re.search(r"(?<!\\)\\[dw]", pattern) and not flags & re.ASCII: add("info", "unicode-classes", "\\d and \\w match Unicode digits and letters too (for example " "Arabic-Indic digits); add re.ASCII or use [0-9] / [A-Za-z0-9_] for strict input formats") return risks # ---------------------------------------------------------------- probe PROBE_CODE = r""" import re, sys, time pat, flags, s = sys.argv[1], int(sys.argv[2]), sys.argv[3] rx = re.compile(pat, flags) t = time.perf_counter(); rx.search(s); print(f"{time.perf_counter() - t:.6f}") """ def run_probe(pattern, flags, ch, compiled): tail = next((t for t in "!#\x00~ \n" if not compiled.search(ch * 3 + t)), "!") results, verdict = [], "no slowdown seen" for n in (12, 16, 20, 24, 28): s = ch * n + tail try: r = subprocess.run([sys.executable, "-c", PROBE_CODE, pattern, str(flags), s], capture_output=True, text=True, timeout=2) secs = float(r.stdout.strip() or "nan") except subprocess.TimeoutExpired: results.append({"n": n, "seconds": None}) verdict = f"TIMEOUT at length {n + 1}: exponential backtracking confirmed" break results.append({"n": n, "seconds": round(secs, 4)}) prev = results[-2]["seconds"] if len(results) >= 2 else None if prev and secs > 0.01 and secs / prev > 3: verdict = (f"time grows about {secs / prev:.0f}x per +4 chars: exponential backtracking confirmed") elif secs > 0.5: verdict = f"slow ({secs:.2f} s at length {n + 1}) but not clearly exponential" return {"input": f"{ch!r} * n + {tail!r}", "timings": results, "verdict": verdict} # ---------------------------------------------------------------- matching def read_cases(path): text = sys.stdin.read() if path == "-" else open(path, encoding="utf-8").read() cases = [] for raw in text.splitlines(): if not raw.strip() or raw.lstrip().startswith("#"): continue if raw.startswith("+ ") or raw.startswith("- "): cases.append({"text": raw[2:], "expect": raw[0] == "+"}) else: cases.append({"text": raw, "expect": None}) return cases def match_case(rx, text, mode): fn = {"search": rx.search, "match": rx.match, "fullmatch": rx.fullmatch}.get(mode) names = {v: k for k, v in rx.groupindex.items()} def groups(m): out = [] for g in range(1, rx.groups + 1): out.append({"group": g, "name": names.get(g), "value": m.group(g), "span": list(m.span(g)) if m.group(g) is not None else None}) return out if mode == "findall": ms = list(rx.finditer(text)) return {"matched": bool(ms), "matches": [{"text": m.group(0), "span": list(m.span()), "groups": groups(m)} for m in ms]} m = fn(text) if not m: return {"matched": False, "matches": []} return {"matched": True, "matches": [{"text": m.group(0), "span": list(m.span()), "groups": groups(m)}]} def describe_flags(flags): names = [n for f, n in FLAG_NAMES if flags & f] return ", ".join(names) if names else "none" # ---------------------------------------------------------------- main def parse_args(argv): opts = {"texts": [], "cases": None, "mode": "search", "flags": 0, "probe": False, "explain": True, "json": False, "fail_on": "high", "pattern": None, "timeout": 2.0} i = 0 while i < len(argv): a = argv[i] def val(): if i + 1 >= len(argv): raise UsageError(f"{a} needs a value") return argv[i + 1] if a in ("-t", "--text"): opts["texts"].append(val()); i += 2 elif a == "--cases": opts["cases"] = val(); i += 2 elif a == "--mode": opts["mode"] = val(); i += 2 if opts["mode"] not in ("search", "match", "fullmatch", "findall"): raise UsageError("--mode must be search, match, fullmatch, or findall") elif a == "--flags": letters = val(); i += 2 bad = [c for c in letters.lower() if c not in FLAG_LETTERS] if bad: raise UsageError(f"unknown flag letter(s) {''.join(bad)!r}; use any of i m s x a") for c in letters.lower(): opts["flags"] |= FLAG_LETTERS[c] elif a == "--fail-on": opts["fail_on"] = val().lower(); i += 2 if opts["fail_on"] not in ("high", "warn", "info", "never"): raise UsageError("--fail-on must be high, warn, info, or never") elif a == "--timeout": try: opts["timeout"] = float(val()) except ValueError: raise UsageError("--timeout needs a number of seconds, for example --timeout 2") i += 2 elif a == "--probe": opts["probe"] = True; i += 1 elif a == "--no-explain": opts["explain"] = False; i += 1 elif a == "--json": opts["json"] = True; i += 1 elif a in ("-h", "--help"): print(__doc__); sys.exit(0) elif a.startswith("--") and opts["pattern"] is not None: raise UsageError(f"unknown option {a}") elif opts["pattern"] is None: opts["pattern"] = a; i += 1 else: raise UsageError(f"unexpected argument {a!r} (quote the pattern; use -t for sample inputs)") if opts["pattern"] is None: raise UsageError("give a PATTERN (quote it in single quotes in the shell)") return opts def main(argv): try: opts = parse_args(argv) cases = [{"text": t, "expect": None} for t in opts["texts"]] if opts["cases"]: try: cases += read_cases(opts["cases"]) except OSError as e: raise UsageError(f"cannot read cases file: {e.strerror}: {opts['cases']}") except UsageError as e: print(f"error: {e}", file=sys.stderr) return 2 pattern, flags, mode = opts["pattern"], opts["flags"], opts["mode"] try: rx = re.compile(pattern, flags) parsed = sre_parse.parse(pattern, flags) except re.error as e: pos = f" at position {e.pos}" if e.pos is not None else "" print(f"error: pattern does not compile: {e.msg}{pos}", file=sys.stderr) if e.pos is not None: print(f" {pattern}\n {' ' * e.pos}^", file=sys.stderr) return 2 flags = int(rx.flags) & ~int(re.UNICODE) names = {v: k for k, v in rx.groupindex.items()} risks = analyze(parsed, flags, pattern, {mode}) if opts["probe"]: for r in risks: if r.get("probe"): r["probe_result"] = run_probe(pattern, flags, r["probe"], rx) results = [] for c in cases: try: res = with_timeout(opts["timeout"], match_case, rx, c["text"], mode) status = None if c["expect"] is None else ("PASS" if res["matched"] == c["expect"] else "FAIL") except MatchTimeout: res, status = {"matched": None, "matches": []}, "TIMEOUT" results.append({**c, **res, "status": status}) fails = sum(1 for r in results if r["status"] in ("FAIL", "TIMEOUT")) counts = {lvl: sum(1 for r in risks if r["level"] == lvl) for lvl in ("high", "warn", "info")} report = {"pattern": pattern, "flags": describe_flags(flags), "mode": mode, "groups": rx.groups, "group_names": {str(k): v for k, v in names.items()}, "explanation": explain(list(parsed), names, flags) if opts["explain"] else [], "cases": results, "failed_expectations": fails, "risks": risks, "risk_counts": counts} threshold = LEVELS.get(opts["fail_on"], 99) risky = any(LEVELS[r["level"]] >= threshold for r in risks) if opts["json"]: print(json.dumps(report, indent=2, ensure_ascii=False)) return 1 if fails or risky else 0 print(f"Pattern: {pattern}") named = ", ".join(f'{g} "{n}"' for g, n in sorted(names.items())) print(f"Flags: {describe_flags(flags)} | mode: {mode} | groups: {rx.groups}" + (f" ({named})" if named else "")) if opts["explain"]: print("\nExplanation:") for line in report["explanation"]: print(" " + line) if results: print(f"\nSamples ({mode}):") for r in results: mark = {True: "+", False: "-", None: " "}[r["expect"]] tag = r["status"] or ("match" if r["matched"] else "no match") line = f" {tag:<8} {mark} {r['text']!r}" if r["matched"]: parts = [] for m in r["matches"][:5]: g = " ".join(f"{x['name'] or x['group']}={x['value']!r}" for x in m["groups"]) parts.append(f"[{m['span'][0]}:{m['span'][1]}] {m['text']!r}" + (f" {g}" if g else "")) more = f" (+{len(r['matches']) - 5} more)" if len(r["matches"]) > 5 else "" line += " -> " + "; ".join(parts) + more elif r["status"] == "TIMEOUT": line += f" -> still running after {opts['timeout']:g} s (catastrophic backtracking)" elif r["status"] == "FAIL": line += " -> expected a match" if r["status"] == "FAIL" and r["matched"]: line += " (expected no match)" print(line) print("\nRisks and suggestions:") if not risks: print(" none found") for r in risks: print(f" {r['level'].upper():<4} {r['rule']:<23} {r['message']}") pr = r.get("probe_result") if pr: times = ", ".join(f"n={t['n']}: {'timeout' if t['seconds'] is None else str(t['seconds']) + ' s'}" for t in pr["timings"]) print(f" probe {pr['input']}: {times} -> {pr['verdict']}") summary = f"\nSummary: HIGH {counts['high']} WARN {counts['warn']} INFO {counts['info']}" if any(r["expect"] is not None for r in results): n = sum(1 for r in results if r["expect"] is not None) summary += f" | expectations {n - fails}/{n} pass" timeouts = sum(1 for r in results if r["status"] == "TIMEOUT") if timeouts: summary += f" | {timeouts} sample(s) timed out" print(summary) return 1 if fails or risky else 0 if __name__ == "__main__": sys.exit(main(sys.argv[1:]))

