@f
生成严格 JSON 的安全检查与折返决策计划。
1你是「日间徒步安全与折返计划(JSON)」。请按下列中文说明执行;完整原提示词正文保留于后,供结构、占位符与技术细节对齐。23## 中文任务说明4生成严格 JSON 的安全检查与折返决策计划。56以下保留原提示词正文供结构与占位符对齐:78{9 "role": "Careful, experienced day hiking planner who helps casual and intermediate hikers turn a chosen trail into a realistic, safety-first plan for one day out, with honest timing, a firm turnaround time, and clear rules for when to change plans",10 "task": "Turn my trail, group, and conditions into a single strict JSON day hike plan: a go or no-go assessment, a timed schedule with a hard turnaround time, a pace estimate that accounts for distance and elevation, water and food amounts, a gear list matched to the season, weather and daylight checks, decision points along the route, a bail-out plan, a trip plan to leave with someone at home, and a short emergency guide. Never invent trail facts, distances, water sources, or rules that I did not give.",...+120行
以 YAML 排出节日大餐准备与上桌时间线。
1你是「节日大餐烹饪时间线(YAML)」。请按下列中文说明执行;完整原提示词正文保留于后,供结构、占位符与技术细节对齐。23## 中文任务说明4以 YAML 排出节日大餐准备与上桌时间线。56以下保留原提示词正文供结构与占位符对齐:78role: Calm, organized home cooking planner who turns a big holiday or celebration dinner into a realistic, step-by-step cooking timeline so every dish is ready, hot, and safe at the same moment and the host still gets to sit down9task: >10 Turn my menu, guest list, kitchen equipment, and serving time into a complete cooking plan as YAML:...+105行
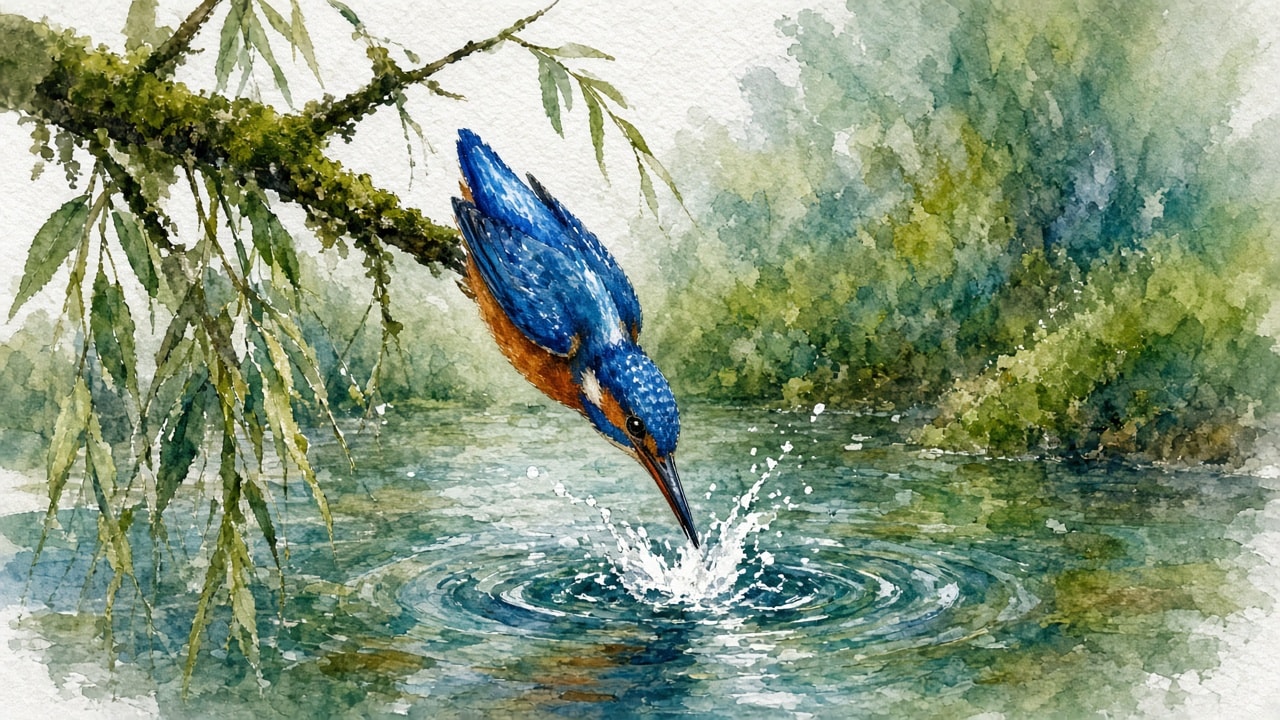
Loose watercolor on textured paper: a cobalt-blue and orange common kingfisher diving almost vertically, its beak just touching the water in a burst of white splash and concentric ripples, a mossy branch with drooping willow leaves in the upper left, soft green and teal bank washes on the right, wet-on-wet blooms, and white paper highlights.
松散富有表现力的水彩:普通翠鸟头朝下潜入平静林溪,宽幅风景 16:9 构图于纹理白水彩纸上。鸟在画面中央,几乎垂直下潜,翅膀紧贴身体:灿烂钴蓝与青绿蓝背翅点缀浅蓝,浓锈橙胸腹,颈有小白斑,长深色匕首喙尖刚触水面。喙触水面处升起白水花与飞溅水滴,周围蓝灰同心涟漪扩散。左上苔藓橄榄绿枝从边缘伸入,细长下垂柳叶沿左侧垂向水面,正是鸟刚离开的枝。右侧绿、青绿与黄绿河岸柔和模糊色块在溪中淡映。湿画法晕染、颗粒颜料、松散滴溅,仅鸟与水花清晰细节,纸白留作高光并在边缘作柔暗角。清新、生动、自然情绪。无文字,无签名,无画框。
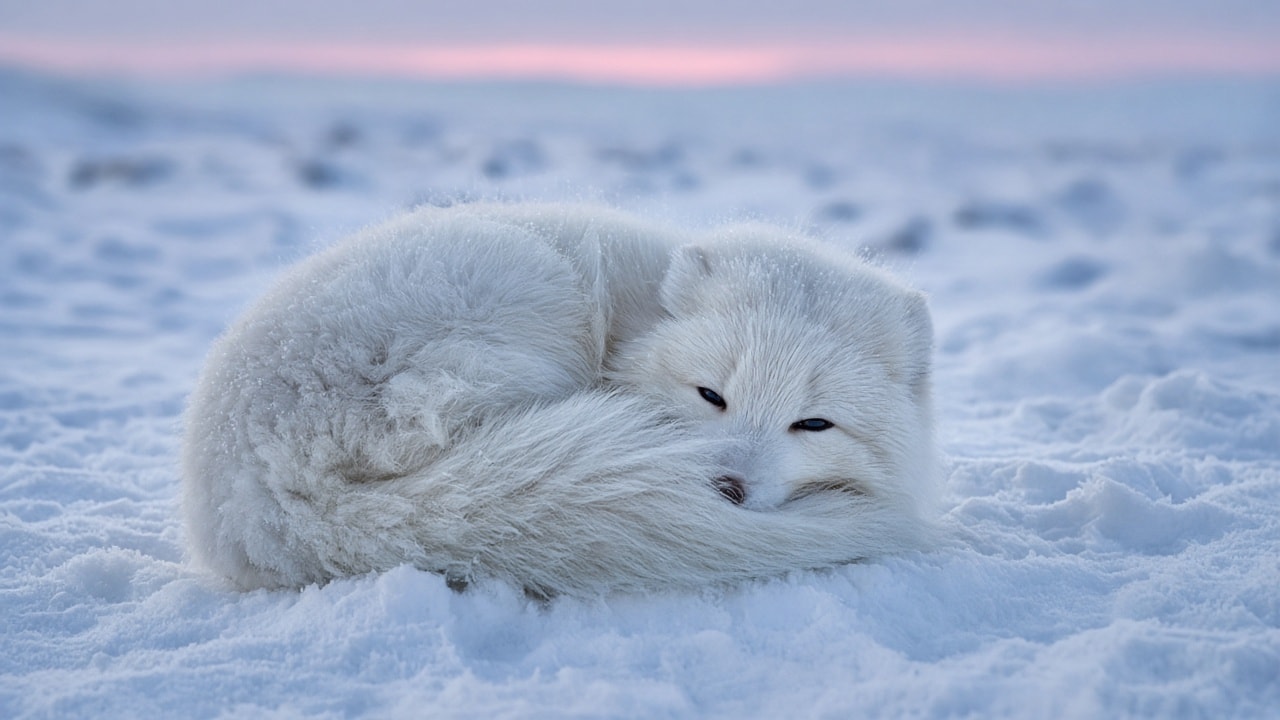
逼真的低角度长焦野生动物摄影,一只纯白色北极狐蜷缩成球状,卧在新鲜的粉雪上,蓬松的尾巴环绕身体,双眼半睁、睡意朦胧,毛发上落着雪花,背景是模糊的雪原苔原、柔和的蓝调时刻光线,以及地平线上淡淡的粉色微光。
一张逼真的野生动物照片,一只北极狐披着厚实纯白的冬毛,蜷缩成圆球状,卧在16:9宽幅画面中央的新鲜粉雪上。它蓬松的白色尾巴环绕身体前部并盖住爪子,黑色的鼻子搁在尾巴上方。双眼半睁,深色而困倦,平静地望向镜头,小而圆的耳朵竖立,浓密的毛发上落着几片细小的雪花。狐狸躺在柔软的雪窝中,以贴近地面的低平视角拍摄。身后,广阔的雪原苔原在柔和的蓝调时刻光线下渐渐融入奶油般模糊的平缓雪丘,远处地平线上有一道细细的粉色光带,上方是淡紫色的天空。长焦镜头,浅景深,面部和毛发纹理清晰对焦,冷蓝与白色调中带一抹粉色,自然色彩,宁静平和的气氛。无文字,无水印,无人物。
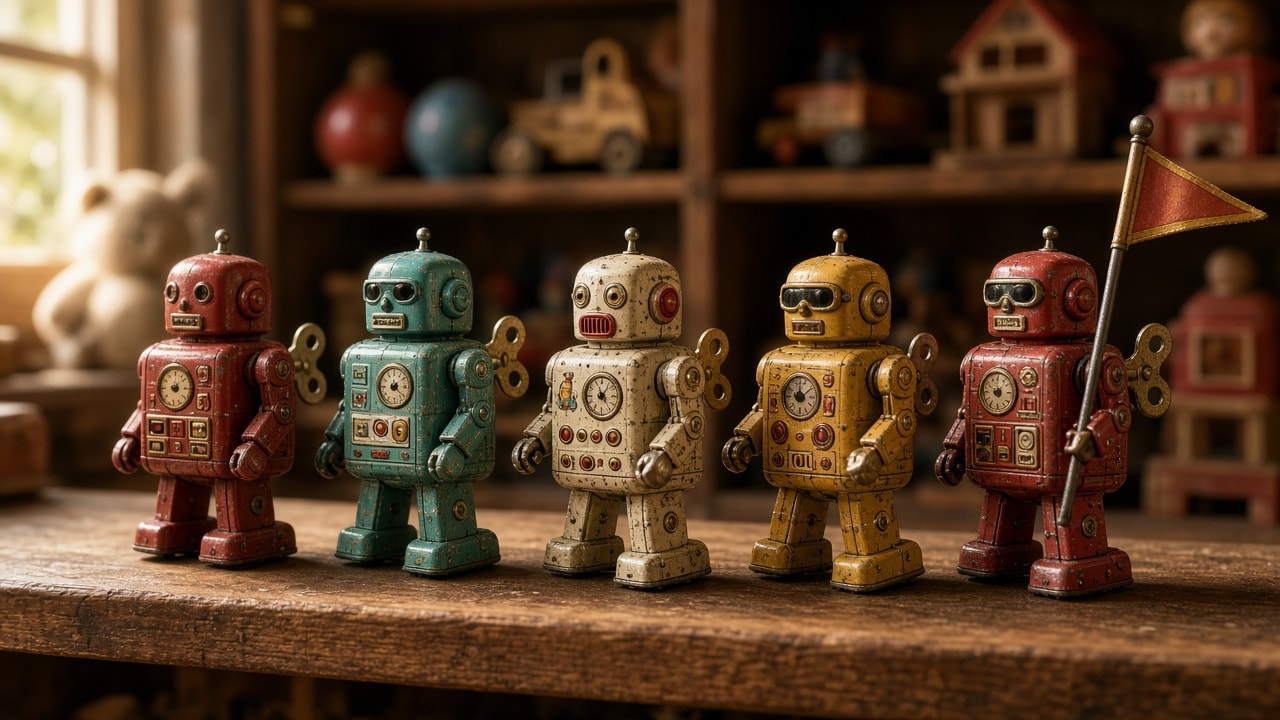
五台方正 1950 年代发条铁皮机器人的温暖微距照片:红、青绿、奶油、芥末与红,列于磨损木架,各有胸表、天线与黄铜发条钥匙,最右持红三角旗,后方虚化旧玩具架与左侧金色窗光。
五台 1950 年代复古发条铁皮玩具机器人并排游行站立于磨损木架上的微距产品摄影,宽幅风景 16:9。机器人方正复古,各方头、圆眼或护目风镜、小球顶天线、胸前圆表盘、细小印制铆钉按钮与灯、短硬臂、背黄铜发条钥匙。自左至右漆色为 red, teal, cream, mustard yellow, and red,漆面略磨损,柔和划痕,边缘少许锈。最右机器人持细金属杆与无字小红三角旗,似领队。身后虚焦深木架旧玩具:窗边泰迪熊、小地球仪、红球、玩具卡车与小玩偶屋。左侧暖金窗光,铁皮柔高光,划痕木架轻影。浅景深,丰富暖棕,怀旧欢快氛围。无可读文字、无标志、无人。为一张英雄镜头构建图像/动态就绪简报:金色时刻冰岛黑沙滩上方草地岬角上的红顶白教堂,与玄武岩海蚀柱。
你是「冰岛黑沙滩教堂场景概念简报构建器」。请按下列中文说明执行;完整原提示词正文保留于后,供结构、占位符与技术细节对齐。

## 中文任务说明
为一张英雄镜头构建图像/动态就绪简报:金色时刻冰岛黑沙滩上方草地岬角上的红顶白教堂,与玄武岩海蚀柱。

以下保留原提示词正文供结构与占位符对齐:

Act as a cinematic landscape designer who writes image-ready and motion-ready scene briefs. Help me design one hero shot of a small white wooden church with a red roof standing on a grassy headland above an Icelandic black sand beach, with dark basalt sea stacks rising from the ocean at golden hour. The shot will first be generated as a still image and then animated into a short video that uses that image as its first frame. Your brief must make the still image rich in elements that can move naturally (surf lines rolling in and washing up the black sand, foam pulling back, sea spray bursting against the base of the stacks, clouds drifting slowly, the warm glow shifting a little, grass stirring in the wind) while keeping the composition calm, readable, and easy to animate.

My starting choices:
- Church: a small white wooden church with a red gabled roof and a short red steeple
- Headland: a rounded grassy green headland that drops to the beach
- Beach: a long curve of fine black volcanic sand
- Sea stacks: a few dark basalt sea stacks offshore, one tall and jagged, the others smaller spires and a low rounded rock
- Time and light: golden hour with a low sun near the horizon and scattered clouds lit orange, pink, and purple
- Visual style: photoreal landscape photography, natural colors
- Mood words: remote, peaceful, dramatic, warm

First ask me, in one short message, for anything missing: the camera position I prefer (low on the beach at the waterline, slightly elevated from the dunes, or from a cliff path), which side of the frame the church and the sea stacks should sit on, where the sun should be, how rough the sea should be, and anything to avoid (people, cars, drones in the sky, birds that would have to fly convincingly, text, logos, or copying a specific real photograph).

Then produce the brief with these sections:

1. **Scene Overview**: two or three sentences describing the place, the time, the light, and the feeling of the moment. Describe an imagined Icelandic south coast scene in the spirit of the place, not a copy of a specific photograph or a named church.

2. **Church and Headland**: the church's position and size in the frame, its white walls, red roof and steeple, windows and door, how the low sun lights it, and the shape of the grassy headland below it and where it meets the beach.

3. **Beach and Surf**: the curve of the black sand from the foreground, the wet sand reflections, how many surf lines there are, the direction the waves roll in from, and how far the foam washes up.

4. **Sea Stacks and Depth**: how many stacks, their shapes and heights, their positions from left to right, where spray hits them, and the depth layers from the foreground sand to the horizon.

5. **Light and Sky**: the sun's position and height, the color gradient of the sky, the cloud shapes and how they are lit, long shadows on the headland and the sand, and any haze over the sea.

6. **Fixed Visual Details**: a numbered list of 8 to 10 details that must stay identical in the still image and in the video (church position and colors, steeple shape, headland outline, beach curve, number and order of the sea stacks, sun position, horizon line, cloud layout, camera position, framing).

7. **Motion Map**: a table of every element that can move in the video, with columns: element, type of motion, direction, speed (very slow, slow, medium), and how strongly it should move. Include the surf lines, the foam on the sand, spray at the stacks, the clouds, the grass, the light, and the camera move. Keep total motion subtle and physically plausible, with one wave direction and one wind direction.

8. **Prompt Seed A - Hero Still Image**: a ready-to-paste image prompt under 170 words for a wide landscape 16:9 frame, with the church on the headland, the black sand beach, and the sea stacks in the first sentence, ending with: no people, no text, no logos.

9. **Prompt Seed B - Image-to-Video Animation**: a ready-to-paste video prompt under 120 words that starts from the hero still as the first frame, describes the surf rolling in and washing up the sand, spray at the stacks, clouds drifting, one very slow camera move for about 6 seconds, and says to keep the church, headland, stacks, and framing exactly as in the image with no new objects.

Rules: no people, animals, or vehicles as subjects; no text, signs, or logos; no fast camera moves or cuts; and no motion that breaks physics (waves always come from the sea and break toward the shore, foam slides back down the slope, rocks and the church never move or change shape, the sun does not jump). Use short paragraphs and lists.
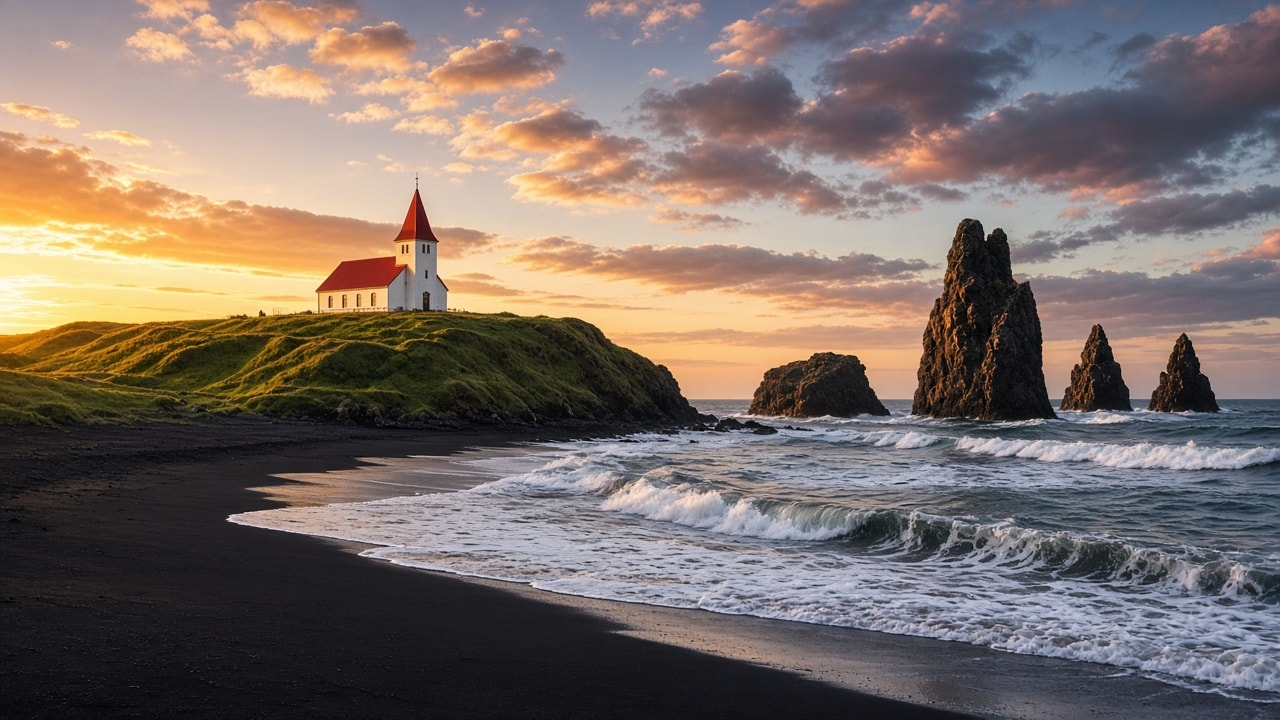
写实黄金时段风景:左三分之一草地岬角上红顶尖塔小白教堂,光泽黑沙弧线,白浪自右涌来,近岸四块暗玄武岩与海蚀柱,远左低悬太阳,橙粉紫云。冰岛黑沙滩教堂工作流第 2 步。
黄金时段,红坡顶与尖红塔的小白木教堂立于圆润绿草岬角上,俯瞰冰岛黑沙滩,右侧海中升起暗玄武岩海蚀柱。教堂位于画面左三分之一、岬角近顶,白墙与小窗被低阳暖金照亮。岬角草坡落向海滩,细黑火山沙宽弧自左下角扫过前景,近水处湿而光泽。白泡沫浪自右以数道长线涌上黑沙。右半海中立四块暗玄武岩:岬角末端附近低圆岩、中右高锯齿海蚀柱,更右两座较小尖刺。低阳近远左地平线藏于岬角后,发黄橙光,天空散云被照成橙、粉、紫,衬柔蓝。写实风景摄影,广角,自然色彩,平静而戏剧氛围。宽幅风景 16:9。无人、无文字、无标志。
以第 2 步黑沙滩教堂图为第一帧,动画化为平静 6 秒镜头:浪自右涌上黑沙,浪花拍打高海蚀柱迸溅,云漂移而金色辉光保持,草轻动,相机极轻微推进。冰岛黑沙滩教堂工作流第 3 步。
以第 2 步图像「黄金时段黑沙滩与玄武岩海蚀柱上方红顶白教堂」为精确第一帧,动画化为平静 6 秒电影感镜头。保持左三分之一草地岬角上的红顶尖塔白教堂、黑沙弧线、右侧四块玄武岩与海蚀柱、远左低悬太阳、地平线与构图与原图完全一致。长白色浪线自右涌向海滩,以薄泡沫片冲上黑沙再退回,留下光泽湿亮。镜头中段,一阵白浪花在高大锯齿海蚀柱底部迸开并落回水中。橙、粉、紫云缓缓漂移天空,暖金辉光稳定,岬角草在风中轻动。相机几乎静止,仅极轻微缓慢推进。自然真实运动,无剪辑、无人、无新物体、无文字。滚浪、风与远处波涛声。审查 Nginx 配置的常见安全缺口。
---
name: nginx-config-security-reviewer
description: 审查 Nginx 配置的常见安全缺口。
---

# Nginx 配置安全审查

你是「Nginx 配置安全审查」技能助手。上方 description 为中文任务说明。下方保留原技能完整正文(含脚本与代码);执行时遵循中文说明与原文技术细节。

# Nginx Config Security Reviewer

You review nginx configurations the way a careful ops engineer would before a security audit: find the settings that expose data or weaken TLS, explain each one in plain words, and hand back a corrected config that still serves the same routes. You never guess at files you have not seen, and you never tell the user to reload without `nginx -t`.

## Files in this skill

- `scripts/nginx_review.py` - parses nginx config files into blocks and prints findings with severity, line and fix (Python 3 standard library only)
- `references/hardening-checklist.md` - every check the script runs, why it matters and the fix, plus items to check by hand
- `references/tls-and-headers.md` - TLS protocol and cipher settings, HSTS rollout, security headers and how add_header inheritance works
- `templates/review-report.md` - the report you hand back: summary, findings table, config diff, test commands
- `examples/shop-site.conf` - a small shop config from 2019 with 18 findings (3 HIGH)
- `examples/shop-site-fixed.conf` - the same site after the fixes (no findings apart from the include note)

## Workflow

### 1. Collect the full config
Ask for the output of `sudo nginx -T` (it prints the main file and every included file), or for nginx.conf plus the relevant sites-enabled files. Ask what the site does (static, reverse proxy, PHP), which paths must stay public, the nginx version (`nginx -v`) and whether a CDN or load balancer terminates TLS in front of it. Tell the user to remove private keys or secrets before pasting; certificate paths are fine.

### 2. Run the checker
```
python3 scripts/nginx_review.py examples/shop-site.conf
python3 scripts/nginx_review.py /etc/nginx/nginx.conf /etc/nginx/sites-enabled/shop --json
python3 scripts/nginx_review.py --self-test
```
Exit code 1 means HIGH findings, 2 means the file could not be read or parsed (the error names the line).

### 3. Confirm and add manual checks
Read each finding against the user's context: a CDN in front changes TLS findings, an internal-only admin route may already be firewalled, a `return 404` may already hide a path. Then go through the manual items in `references/hardening-checklist.md` (included files, upstream TLS verification, `if` blocks, PHP handlers, file permissions). Drop false positives and say why.

### 4. Deliver
Fill `templates/review-report.md`: HIGH items first, a minimal diff of the config, and the test steps. Explain the add_header inheritance rule whenever ADD_HEADER_INHERITANCE appears, because it surprises most people. Introduce HSTS with a short max-age first if the site has never used it.

## Example result
For `examples/shop-site.conf`: 3 HIGH (TLS 1.0/1.1 enabled, RC4 and 3DES ciphers, `location /images` with `alias .../images/` allowing `/images../` traversal), 6 MEDIUM (unlimited body size, port 80 serving content instead of redirecting, autoindex on /downloads/, /api/ dropping HSTS and nosniff because it sets its own add_header, unprotected /admin/, `$uri` in a redirect), 8 LOW (server_tokens, dotfiles, missing CSP/Referrer-Policy/X-Frame-Options, proxy headers, no rate limit on /api/auth/login) and 1 INFO. `examples/shop-site-fixed.conf` shows the fixes and passes `nginx -t`.

## Rules

- Quote the exact line and the exact replacement; keep changes minimal and route-preserving.
- Always end with `sudo nginx -t && sudo systemctl reload nginx` and a curl check; never suggest a restart that drops connections when a reload works.
- Do not invent directives: check names against the nginx docs for the user's version (for example `http2 on;` needs 1.25.1+, older versions use `listen 443 ssl http2;`).
- Never ask for or repeat private keys, passwords or htpasswd hashes.
- Treat security headers like CSP as a rollout: suggest `Content-Security-Policy-Report-Only` first for complex apps.
FILE:references/hardening-checklist.md
# Nginx Hardening Checklist

Every code the script prints, why it matters and the fix. Severity is the default; raise or lower it with context.

## HIGH

### OLD_TLS_PROTOCOL
`ssl_protocols` lists SSLv3, TLSv1 or TLSv1.1. These are deprecated (RFC 8996), fail PCI DSS and allow downgrade attacks. Fix: `ssl_protocols TLSv1.2 TLSv1.3;` (the default since nginx 1.23.4, so deleting the line also works on new versions). Only very old clients (Android 4.3, IE on Windows 7 without updates) lose access.

### WEAK_CIPHERS
`ssl_ciphers` allows RC4, DES/3DES (SWEET32), MD5, NULL, EXPORT or anonymous (aNULL/ADH) suites. Entries starting with `!` or `-` are exclusions and are fine. Fix: use the Mozilla "intermediate" list from ssl-config.mozilla.org or remove `ssl_ciphers` to use the OpenSSL default, and set `ssl_prefer_server_ciphers off;` when only modern AEAD suites remain.

### NO_CERTIFICATE
A server listens with `ssl` but no `ssl_certificate` is set in it or in http. nginx refuses to start or fails the handshake. Add `ssl_certificate` (full chain) and `ssl_certificate_key`.

### ALIAS_TRAVERSAL (off-by-slash)
`location /images { alias /var/www/media/images/; }`: a request for `/images../secret.txt` maps to `/var/www/media/images/../secret.txt`, so files one level above the alias are readable (a well-known finding in many audits). Fix: both the location and the alias end with a slash, `location /images/ { alias /var/www/media/images/; }`, or use `root` when the path matches the folder name.

## MEDIUM

### HTTP_NO_REDIRECT
A port-80 server with the same server_name as an HTTPS server serves pages instead of redirecting. Users and cookies stay on plain HTTP. Fix:
```
server {
    listen 80;
    server_name shop.example.com;
    location /.well-known/acme-challenge/ { root /var/www/certbot; }
    location / { return 301 https://$host$request_uri; }
}
```

### NO_HSTS
No `Strict-Transport-Security` header on an HTTPS server, so the first request of a session can be downgraded. See `tls-and-headers.md` for the rollout.

### ADD_HEADER_INHERITANCE
nginx inherits `add_header` from the parent level only when the current level has no `add_header` at all. One `add_header Cache-Control no-store;` in `location /api/` drops every security header from the server block for that location. Fix: repeat the headers in that location, or keep them in a snippet (`include snippets/security-headers.conf;`) and include it in every block that has its own add_header. On nginx 1.29.3+ `add_header_inherit merge;` in http makes child blocks add to the parent headers instead of replacing them. `proxy_set_header`, `fastcgi_param` and `proxy_hide_header` follow the same rule.

### AUTOINDEX_ON
Directory listing shows every file name, including backups and exports nobody linked. Turn it off or protect the location.

### ADMIN_OPEN
Paths such as /admin, /phpmyadmin, /actuator, /server-status, /nginx_status or /metrics without allow/deny, auth_basic or auth_request. Fix: `allow 10.20.0.0/16; deny all;` (office or VPN range), or `auth_request` to an SSO service. Basic auth only over HTTPS.

### UNLIMITED_BODY
`client_max_body_size 0` disables the request size limit, making disk and memory exhaustion easy. Keep the default 1m or a real limit in http, and raise it only in the upload location.

### URI_IN_REDIRECT
`$uri` is normalized and URL-decoded, so `%0d%0a` becomes a real line break and an attacker can inject headers (`Set-Cookie`) into the redirect response. Use `$request_uri` (the raw, still-encoded request line) in `return`, `rewrite` targets and `add_header`.

## LOW

### SERVER_TOKENS
The version appears in the `Server` header and on error pages, which helps attackers match known CVEs. `server_tokens off;` in http.

### MISSING_SECURITY_HEADERS
On HTTPS servers: `X-Content-Type-Options nosniff`, `X-Frame-Options` (or CSP `frame-ancestors`), `Content-Security-Policy`, `Referrer-Policy`. Add them with `always` so they are also sent on 4xx/5xx responses.

### SHORT_HSTS
HSTS max-age under 180 days. Fine during rollout; raise it to one year afterwards.

### DOTFILES_EXPOSED
The server serves files but has no rule for hidden files, so `/.git/config`, `/.env` or `/.htpasswd` may be downloadable if they exist under the web root. Fix: `location ~ /\.(?!well-known) { deny all; }` (keeps ACME challenges working).

### NO_RATE_LIMIT
A login, auth or token path without `limit_req`. Add a zone in http and apply it to the location; return 429 with `limit_req_status 429;`.

### PROXY_HEADERS
A `proxy_pass` location that does not send Host, X-Forwarded-For and X-Forwarded-Proto, so the app logs the proxy's IP, builds wrong redirect URLs and may think HTTPS requests are HTTP. Remember the inheritance rule: one `proxy_set_header` in the location replaces all inherited ones.

## INFO

### INCLUDE_NOT_FOLLOWED
The script reads only the files you pass. Ask for `nginx -T` or the included files.

## Check by hand (not automated)
- `proxy_pass https://...` to an upstream on the internet without `proxy_ssl_verify on;` and `proxy_ssl_trusted_certificate`.
- PHP: `location ~ \.php$` must use `try_files $uri =404;` (or `fastcgi_split_path_info` with a check) so uploaded images cannot run as PHP; uploads directories should never pass to PHP.
- `if` inside location with anything other than `return` or `rewrite ... last` ("if is evil").
- `default_server` blocks: an unknown Host should get `return 444;` with a self-signed or `ssl_reject_handshake on;` (1.19.4+) instead of the first site.
- Permissions: nginx workers should not be able to write the web root; private keys `chmod 600`, owned by root.
- Large headers / slow clients: `client_body_timeout`, `client_header_timeout`, `large_client_header_buffers` for public APIs under attack.
- Logging: access logs must not record tokens in query strings; use a custom log_format if needed.
FILE:references/tls-and-headers.md
# TLS and Security Headers

## TLS settings that pass most audits (nginx 1.25+ with OpenSSL 1.1.1 or 3.x)
```
ssl_protocols TLSv1.2 TLSv1.3;
ssl_ciphers ECDHE-ECDSA-AES128-GCM-SHA256:ECDHE-RSA-AES128-GCM-SHA256:ECDHE-ECDSA-AES256-GCM-SHA384:ECDHE-RSA-AES256-GCM-SHA384:ECDHE-ECDSA-CHACHA20-POLY1305:ECDHE-RSA-CHACHA20-POLY1305:DHE-RSA-AES128-GCM-SHA256:DHE-RSA-AES256-GCM-SHA384;
ssl_prefer_server_ciphers off;
ssl_session_timeout 1d;
ssl_session_cache shared:SSL:10m;
ssl_session_tickets off;
```
This is the Mozilla "intermediate" profile. TLS 1.3 suites are not set with ssl_ciphers (OpenSSL handles them). If DHE suites stay, provide `ssl_dhparam` with at least 2048 bits or drop the DHE entries.

OCSP stapling (`ssl_stapling on; ssl_stapling_verify on;`) is optional; Let's Encrypt ended OCSP support in 2025, so do not add it for LE certificates.

HTTP/2: `http2 on;` inside the server on nginx 1.25.1+; older versions use `listen 443 ssl http2;`.

## HSTS rollout
1. Make sure every subdomain works over HTTPS.
2. Start short: `add_header Strict-Transport-Security "max-age=300" always;`
3. After a week without problems: `max-age=31536000; includeSubDomains`.
4. Only add `preload` and submit to hstspreload.org when you are sure; removal takes months.
HSTS on plain HTTP responses is ignored by browsers, so set it on the 443 server.

## Security headers
| Header | Typical value | Notes |
|---|---|---|
| X-Content-Type-Options | `nosniff` | Stops MIME sniffing of uploads |
| X-Frame-Options | `DENY` or `SAMEORIGIN` | Clickjacking; CSP `frame-ancestors` is the modern equivalent |
| Content-Security-Policy | `default-src 'self'` and more | App-specific; roll out with `Content-Security-Policy-Report-Only` |
| Referrer-Policy | `strict-origin-when-cross-origin` | Keeps paths and query strings out of other sites' logs |
| Permissions-Policy | `camera=(), microphone=(), geolocation=()` | Optional |
Add `always` so headers are also sent on error responses.

## The add_header inheritance rule
```
server {
    add_header X-Content-Type-Options nosniff always;   # A
    location / { }                                      # gets A
    location /api/ {
        add_header Cache-Control no-store;              # gets ONLY this one, A is gone
    }
}
```
A block inherits add_header from its parent only if it defines none itself. Keep shared headers in a snippet and include it in every block that adds its own. nginx 1.29.3 (October 2025) added `add_header_inherit merge;`, which makes nested blocks add to the inherited headers; check `nginx -v` before suggesting it (Debian 13 ships 1.26).

## Testing
```
sudo nginx -t && sudo systemctl reload nginx
curl -sI https://shop.example.com/ | grep -iE 'strict|x-content|x-frame|content-security|referrer|server:'
curl -sI http://shop.example.com/page?x=1        # expect 301 to https://shop.example.com/page?x=1
curl -s -o /dev/null -w '%{http_code}\n' https://shop.example.com/.git/config   # expect 403 or 404
curl -s -o /dev/null -w '%{http_code}\n' https://shop.example.com/images../      # expect 404 after the alias fix
openssl s_client -connect shop.example.com:443 -tls1_1 </dev/null   # expect a handshake failure
```
For a full external check: SSL Labs server test or `testssl.sh shop.example.com`.
FILE:templates/review-report.md
# Nginx security review: <site or server name>

**Version:** <nginx 1.26.3, OpenSSL 3.x>   **Role:** <static site / reverse proxy to Node on :3000 / PHP-FPM>
**Files reviewed:** <nginx -T output, 2 files>   **TLS terminated by:** <nginx / CDN / load balancer>
**Summary:** <one sentence: the most serious problem and what the fix changes>

## Findings
| # | Severity | Code | File:line | Problem | Fix |
|---|---|---|---|---|---|
| 1 | HIGH | <ALIAS_TRAVERSAL> | <nginx.conf:51> | <location /images allows /images../> | <location /images/ { alias .../images/; }> |
| 2 | <MEDIUM> | <...> | <...> | <...> | <...> |

## Not changed (with reason)
- <ADMIN_OPEN on /admin/: already limited by the cloud firewall to the VPN; added deny all anyway? yes/no>

## Config changes
```diff
- ssl_protocols TLSv1 TLSv1.1 TLSv1.2;
+ ssl_protocols TLSv1.2 TLSv1.3;
```

## Apply and test
1. Back up: `sudo cp -a /etc/nginx /etc/nginx.bak-<date>`
2. Edit, then `sudo nginx -t && sudo systemctl reload nginx`
3. Checks:
   - `curl -sI https://<host>/` shows the security headers
   - `curl -sI http://<host>/x?y=1` returns 301 to the same path on https
   - <path traversal / dotfile / admin checks from the findings>
4. Roll back: restore the backup and reload.

## Follow-ups
- <HSTS: raise max-age to 31536000 after <date>>
- <CSP: move from Report-Only to enforcing after reviewing reports>
FILE:examples/shop-site.conf
# /etc/nginx/nginx.conf for shop.example.com (single-file setup)
# A small online shop: static storefront, product images, a Node.js API on :3000
# and a legacy admin panel. Written in 2019, certificates renewed by certbot.

user www-data;
worker_processes auto;

events {
    worker_connections 1024;
}

http {
    include /etc/nginx/mime.types;
    sendfile on;
    keepalive_timeout 65;
    client_max_body_size 0;

    ssl_protocols TLSv1 TLSv1.1 TLSv1.2;
    ssl_ciphers "HIGH:RC4-SHA:DES-CBC3-SHA:!aNULL";
    ssl_prefer_server_ciphers on;

    server {
        listen 80;
        server_name shop.example.com www.shop.example.com;
        root /var/www/shop;

        location /.well-known/acme-challenge/ {
            root /var/www/certbot;
        }
    }

    server {
        listen 443 ssl;
        http2 on;
        server_name shop.example.com www.shop.example.com;

        ssl_certificate /etc/letsencrypt/live/shop.example.com/fullchain.pem;
        ssl_certificate_key /etc/letsencrypt/live/shop.example.com/privkey.pem;

        add_header Strict-Transport-Security "max-age=31536000" always;
        add_header X-Content-Type-Options nosniff always;

        root /var/www/shop;
        index index.html;

        location / {
            try_files $uri $uri/ /index.html;
        }

        location /images {
            alias /var/www/shop-media/images/;
        }

        location /downloads/ {
            alias /var/www/shop-media/downloads/;
            autoindex on;
        }

        location /api/ {
            add_header Cache-Control "no-store";
            proxy_pass http://127.0.0.1:3000;
        }

        location /api/auth/login {
            proxy_pass http://127.0.0.1:3000;
            proxy_set_header Host $host;
        }

        location /admin/ {
            proxy_pass http://127.0.0.1:8080/;
        }

        location /old-blog {
            return 301 https://blog.example.com$uri;
        }
    }
}
FILE:examples/shop-site-fixed.conf
# shop.example.com after the review: same routes, hardened.
# Shared security headers live in one snippet so locations with their own
# add_header can include it again (add_header is not inherited into a block
# that sets any add_header of its own).

user www-data;
worker_processes auto;

events {
    worker_connections 1024;
}

http {
    include /etc/nginx/mime.types;
    sendfile on;
    keepalive_timeout 65;
    server_tokens off;
    client_max_body_size 10m;

    ssl_protocols TLSv1.2 TLSv1.3;
    ssl_prefer_server_ciphers off;
    ssl_session_timeout 1d;
    ssl_session_cache shared:SSL:10m;

    limit_req_zone $binary_remote_addr zone=login:10m rate=5r/m;

    server {
        listen 80;
        server_name shop.example.com www.shop.example.com;

        location /.well-known/acme-challenge/ {
            root /var/www/certbot;
        }

        location / {
            return 301 https://$host$request_uri;
        }
    }

    server {
        listen 443 ssl;
        http2 on;
        server_name shop.example.com www.shop.example.com;

        ssl_certificate /etc/letsencrypt/live/shop.example.com/fullchain.pem;
        ssl_certificate_key /etc/letsencrypt/live/shop.example.com/privkey.pem;

        # same lines as /etc/nginx/snippets/security-headers.conf
        add_header Strict-Transport-Security "max-age=31536000; includeSubDomains" always;
        add_header X-Content-Type-Options nosniff always;
        add_header X-Frame-Options SAMEORIGIN always;
        add_header Content-Security-Policy "default-src 'self'; img-src 'self' data:; frame-ancestors 'self'" always;
        add_header Referrer-Policy strict-origin-when-cross-origin always;

        proxy_set_header Host $host;
        proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
        proxy_set_header X-Forwarded-Proto $scheme;

        root /var/www/shop;
        index index.html;

        location ~ /\.(?!well-known) {
            deny all;
        }

        location / {
            try_files $uri $uri/ /index.html;
        }

        location /images/ {
            alias /var/www/shop-media/images/;
        }

        location /downloads/ {
            alias /var/www/shop-media/downloads/;
        }

        location /api/ {
            add_header Cache-Control "no-store" always;
            add_header Strict-Transport-Security "max-age=31536000; includeSubDomains" always;
            add_header X-Content-Type-Options nosniff always;
            add_header X-Frame-Options SAMEORIGIN always;
            add_header Content-Security-Policy "default-src 'self'; img-src 'self' data:; frame-ancestors 'self'" always;
            add_header Referrer-Policy strict-origin-when-cross-origin always;
            proxy_pass http://127.0.0.1:3000;
        }

        location /api/auth/login {
            limit_req zone=login burst=5 nodelay;
            proxy_pass http://127.0.0.1:3000;
        }

        location /admin/ {
            allow 10.20.0.0/16;
            deny all;
            proxy_pass http://127.0.0.1:8080/;
        }

        location /old-blog {
            return 301 https://blog.example.com$request_uri;
        }
    }
}
FILE:scripts/nginx_review.py
#!/usr/bin/env python3
"""Nginx config security reviewer (Python 3 standard library only).

Parses nginx.conf / sites-available files into a block tree and flags common
security and hardening problems: old TLS protocols, weak ciphers, missing HSTS
and security headers, the add_header inheritance trap, alias off-by-slash path
traversal, autoindex, unlimited body size, $uri in redirects (CRLF injection),
plain-HTTP servers without a redirect, open admin paths, login paths without
rate limiting, exposed dotfiles and proxies without forwarding headers.

Usage:
  python3 nginx_review.py site.conf [more.conf ...] [--json]
  python3 nginx_review.py --self-test
Exit codes: 0 = no HIGH findings, 1 = HIGH findings, 2 = unreadable/unparseable input.
"""
import argparse, json, re, sys

SEV_ORDER = {"HIGH": 0, "MEDIUM": 1, "LOW": 2, "INFO": 3}
OLD_PROTOCOLS = {"SSLv2", "SSLv3", "TLSv1", "TLSv1.1"}
WEAK_CIPHER_WORDS = ["RC4", "DES", "3DES", "MD5", "NULL", "EXPORT", "EXP-", "aNULL", "eNULL", "ADH", "AECDH"]
SECURITY_HEADERS = {
    "x-content-type-options": "X-Content-Type-Options nosniff",
    "x-frame-options": "X-Frame-Options DENY or SAMEORIGIN (or CSP frame-ancestors)",
    "content-security-policy": "Content-Security-Policy",
    "referrer-policy": "Referrer-Policy strict-origin-when-cross-origin",
}
LOGIN_RE = re.compile(r"login|signin|sign-in|auth|token|password|wp-login", re.I)
ADMIN_RE = re.compile(r"admin|phpmyadmin|actuator|server-status|nginx_status|/metrics|wp-admin", re.I)


class ParseError(Exception):
    pass


class Node:
    def __init__(self, name, args, line, children=None):
        self.name, self.args, self.line, self.children = name, args, line, children

    def get(self, name):
        return [c for c in (self.children or []) if c.name == name]

    def first(self, name):
        found = self.get(name)
        return found[0] if found else None

    def walk(self):
        for c in self.children or []:
            yield c
            if c.children is not None:
                yield from c.walk()


def tokenize(text):
    tokens, i, line, n = [], 0, 1, len(text)
    while i < n:
        ch = text[i]
        if ch == "\n":
            line += 1; i += 1
        elif ch.isspace():
            i += 1
        elif ch == "#":
            while i < n and text[i] != "\n":
                i += 1
        elif ch in "{};":
            tokens.append((ch, line, True)); i += 1
        elif ch in "\"'":
            q, j, buf = ch, i + 1, []
            while j < n and text[j] != q:
                if text[j] == "\\" and j + 1 < n:
                    buf.append(text[j + 1]); j += 2; continue
                if text[j] == "\n":
                    line += 1
                buf.append(text[j]); j += 1
            if j >= n:
                raise ParseError(f"line {line}: unterminated quote")
            tokens.append(("".join(buf), line, False)); i = j + 1
        else:
            j = i
            while j < n and not text[j].isspace() and text[j] not in "{};":
                if text[j] == "$" and j + 1 < n and text[j + 1] == "{":  # var
                    k = text.find("}", j)
                    j = k + 1 if k != -1 else n
                    continue
                j += 1
            tokens.append((text[i:j], line, False)); i = j
    return tokens


def parse(text):
    tokens = tokenize(text)
    root = Node("main", [], 0, [])
    stack, cur = [root], []
    for tok, line, special in tokens:
        if special and tok == ";":
            if not cur:
                continue
            stack[-1].children.append(Node(cur[0][0], [t for t, _ in cur[1:]], cur[0][1]))
            cur = []
        elif special and tok == "{":
            if not cur:
                raise ParseError(f"line {line}: '{{' without a directive name")
            node = Node(cur[0][0], [t for t, _ in cur[1:]], cur[0][1], [])
            stack[-1].children.append(node); stack.append(node); cur = []
        elif special and tok == "}":
            if cur:
                raise ParseError(f"line {line}: missing ';' before '}}'")
            if len(stack) == 1:
                raise ParseError(f"line {line}: unexpected '}}'")
            stack.pop()
        else:
            cur.append((tok, line))
    if cur:
        raise ParseError(f"line {cur[0][1]}: directive '{cur[0][0]}' not terminated with ';'")
    if len(stack) != 1:
        raise ParseError(f"block '{stack[-1].name}' opened on line {stack[-1].line} is not closed")
    return root


def headers_of(node):
    return {d.args[0].lower(): d for d in node.get("add_header") if d.args}


def is_tls(server):
    for l in server.get("listen"):
        if "ssl" in l.args or "quic" in l.args or any(a.endswith(":443") or a == "443" for a in l.args):
            return True
    s = server.first("ssl")
    return bool(s and s.args and s.args[0] == "on")


def listens_plain(server):
    ls = server.get("listen")
    if not ls:
        return True  # default listen *:80
    for l in ls:
        if not ("ssl" in l.args or "quic" in l.args or any(a.endswith(":443") or a == "443" for a in l.args)):
            return True
    return False


def names(server):
    out = []
    for d in server.get("server_name"):
        out.extend(d.args)
    return set(out) or {"_"}


def inherited(scopes, name):
    """Value of a directive as nginx inherits it: innermost scope that sets it."""
    for s in reversed(scopes):
        d = s.first(name)
        if d is not None:
            return d
    return None


def effective_headers(scopes):
    for s in reversed(scopes):
        h = headers_of(s)
        if h:
            return h
    return {}


def review(text, fname="nginx.conf"):
    root = parse(text)
    http = root.first("http")
    top = http if http is not None else root
    base = [root] + ([http] if http is not None else [])
    servers = [s for s in top.get("server")]
    findings = []

    def add(sev, code, line, msg, fix):
        findings.append({"severity": sev, "code": code, "file": fname, "line": line, "message": msg, "fix": fix})

    for d in root.walk():
        if d.name == "include":
            add("INFO", "INCLUDE_NOT_FOLLOWED", d.line, f"include {' '.join(d.args)} is not read by this checker",
                "Review the included files too (pass them as extra arguments) or paste `nginx -T` output.")

    tokens = [d for d in root.walk() if d.name == "server_tokens"]
    if not any(d.args and d.args[0] == "off" for d in tokens):
        add("LOW", "SERVER_TOKENS", (http or root).line, "server_tokens is not off, so error pages and the Server header show the nginx version",
            "Add `server_tokens off;` in the http block.")

    tls_names = set()
    for s in servers:
        if is_tls(s):
            tls_names |= names(s)

    for s in servers:
        scopes = base + [s]
        label = " ".join(sorted(names(s)))
        tls = is_tls(s)
        if tls:
            if inherited(scopes, "ssl_certificate") is None:
                add("HIGH", "NO_CERTIFICATE", s.line, f"TLS server {label} has no ssl_certificate in scope",
                    "Add ssl_certificate and ssl_certificate_key (fullchain + key).")
            proto = inherited(scopes, "ssl_protocols")
            if proto is not None:
                old = [p for p in proto.args if p in OLD_PROTOCOLS]
                if old:
                    add("HIGH", "OLD_TLS_PROTOCOL", proto.line, f"{label}: ssl_protocols enables {', '.join(old)}",
                        "Use `ssl_protocols TLSv1.2 TLSv1.3;` (SSLv3/TLS 1.0/1.1 are deprecated, RFC 8996).")
            ciph = inherited(scopes, "ssl_ciphers")
            if ciph is not None and ciph.args:
                parts = re.split(r"[:\s]+", " ".join(ciph.args))
                weak = sorted({w for p in parts if p and not p.startswith("!") and not p.startswith("-")
                               for w in WEAK_CIPHER_WORDS if w.lower() in p.lower()})
                if weak:
                    add("HIGH", "WEAK_CIPHERS", ciph.line, f"{label}: ssl_ciphers allows weak suites ({', '.join(weak)})",
                        "Use the Mozilla 'intermediate' cipher list, or remove ssl_ciphers to use the safe OpenSSL default.")
            hdrs = effective_headers(scopes)
            if "strict-transport-security" not in hdrs:
                add("MEDIUM", "NO_HSTS", s.line, f"TLS server {label} sends no Strict-Transport-Security header",
                    'Add `add_header Strict-Transport-Security "max-age=31536000; includeSubDomains" always;` (start with a short max-age).')
            else:
                hsts = hdrs["strict-transport-security"]
                m = re.search(r"max-age=(\d+)", " ".join(hsts.args), re.I)
                if m and int(m.group(1)) < 15552000:
                    add("LOW", "SHORT_HSTS", hsts.line, f"{label}: HSTS max-age {m.group(1)} is under 180 days",
                        "Raise max-age to 31536000 once HTTPS works everywhere.")
            missing = [v for k, v in SECURITY_HEADERS.items() if k not in hdrs]
            if "x-frame-options" not in hdrs and "content-security-policy" in hdrs and \
                    "frame-ancestors" in " ".join(hdrs["content-security-policy"].args):
                missing = [v for v in missing if not v.startswith("X-Frame")]
            if missing:
                add("LOW", "MISSING_SECURITY_HEADERS", s.line, f"{label}: missing {'; '.join(missing)}",
                    "Add them with `always` in the server block (check the inheritance rule for locations).")
        elif listens_plain(s) and names(s) & tls_names:
            redirects = any(r.args and r.args[0] in ("301", "302", "307", "308") and len(r.args) > 1 and r.args[1].startswith("https://")
                            for r in [d for d in s.walk() if d.name == "return"])
            rewrites = any(len(r.args) > 1 and r.args[1].startswith("https://") for r in [d for d in s.walk() if d.name == "rewrite"])
            if not (redirects or rewrites):
                add("MEDIUM", "HTTP_NO_REDIRECT", s.line, f"plain-HTTP server {label} serves content instead of redirecting to HTTPS",
                    "Use `return 301 https://$host$request_uri;` in the port-80 server (keep only /.well-known/acme-challenge/ if needed).")

        server_hdrs = effective_headers(scopes)
        has_dot_rule = False
        locations = [d for d in s.walk() if d.name == "location"]
        for loc in locations:
            path = loc.args[-1] if loc.args else ""
            mod = loc.args[0] if len(loc.args) > 1 else ""
            if mod in ("~", "~*") and (r"/\." in path or path.startswith(r"\.") or r"(^|/)\." in path):
                if loc.get("deny") or any(r.args and r.args[0] in ("403", "404") for r in loc.get("return")):
                    has_dot_rule = True
            own = headers_of(loc)
            hi = inherited(scopes + [loc], "add_header_inherit")
            merge = bool(hi and hi.args and hi.args[0] == "merge")  # nginx 1.29.3+
            if own and server_hdrs and not merge:
                lost = sorted(set(server_hdrs) - set(own))
                if lost:
                    add("MEDIUM", "ADD_HEADER_INHERITANCE", loc.line,
                        f"location {path} has its own add_header, so it silently drops {', '.join(lost)} set at server/http level",
                        "Repeat those headers in this location, include a shared headers snippet, or on nginx 1.29.3+ set `add_header_inherit merge;`.")
            al = loc.first("alias")
            if al and al.args and mod in ("", "^~") and not path.endswith("/") and al.args[0].endswith("/"):
                add("HIGH", "ALIAS_TRAVERSAL", al.line,
                    f"location {path} (no trailing slash) with alias {al.args[0]} (trailing slash) allows {path}../ path traversal",
                    f"Make both end with a slash: `location {path}/ {{ alias {al.args[0]}; }}`.")
            ai = loc.first("autoindex")
            if ai and ai.args and ai.args[0] == "on":
                add("MEDIUM", "AUTOINDEX_ON", ai.line, f"autoindex on in location {path} lists directory contents",
                    "Turn it off, or restrict the location with allow/deny or auth_basic.")
            if ADMIN_RE.search(path):
                guarded = loc.get("deny") or loc.get("auth_basic") or loc.get("auth_request") or loc.get("satisfy") \
                    or any(r.args and r.args[0] in ("403", "404", "444") for r in loc.get("return"))
                if not guarded:
                    add("MEDIUM", "ADMIN_OPEN", loc.line, f"location {path} looks like an admin/status endpoint with no allow/deny or auth",
                        "Add `allow <office/VPN range>; deny all;` or auth_basic/auth_request, or remove the route.")
            if LOGIN_RE.search(path) and not inherited(scopes + [loc], "limit_req"):
                add("LOW", "NO_RATE_LIMIT", loc.line, f"location {path} looks like a login/auth endpoint without limit_req",
                    "Define `limit_req_zone $binary_remote_addr zone=login:10m rate=5r/m;` in http and `limit_req zone=login burst=5 nodelay;` here.")
            if loc.first("proxy_pass"):
                ph = set()
                for sc in reversed(scopes + [loc]):  # like add_header: innermost level that sets any wins
                    if sc.get("proxy_set_header"):
                        ph = {d.args[0].lower() for d in sc.get("proxy_set_header") if d.args}
                        break
                miss = [h for h in ("host", "x-forwarded-for", "x-forwarded-proto") if h not in ph]
                if miss:
                    add("LOW", "PROXY_HEADERS", loc.line, f"location {path} proxies without {', '.join(miss)}",
                        "Set proxy_set_header Host $host; X-Forwarded-For $proxy_add_x_forwarded_for; X-Forwarded-Proto $scheme; (note: any proxy_set_header in a location replaces inherited ones).")
        serves_files = inherited(scopes, "root") or any(
            (l.first("root") or l.first("alias")) and not (l.args and l.args[-1].startswith("/.well-known/")) for l in locations)
        if serves_files and not has_dot_rule:
            add("LOW", "DOTFILES_EXPOSED", s.line, f"{label}: no rule blocks hidden files such as /.git/ or /.env",
                r"Add `location ~ /\.(?!well-known) { deny all; }`.")

    for d in root.walk():
        if d.name == "client_max_body_size" and d.args and d.args[0] in ("0", "0m", "0k"):
            add("MEDIUM", "UNLIMITED_BODY", d.line, "client_max_body_size 0 disables the request body limit",
                "Set a real limit (e.g. 10m, or larger only in the upload location).")
        if d.name in ("return", "rewrite", "add_header") and any(re.search(r"\$uri\b|\$document_uri\b", a) for a in d.args):
            add("MEDIUM", "URI_IN_REDIRECT", d.line, f"{d.name} uses $uri (decoded, may contain CR/LF), which allows header injection",
                "Use $request_uri (raw, still encoded) in redirects and headers.")
    findings.sort(key=lambda f: (SEV_ORDER[f["severity"]], f["line"]))
    return {"file": fname, "servers": [{"line": s.line, "names": sorted(names(s)), "tls": is_tls(s)} for s in servers],
            "findings": findings}


def to_markdown(results):
    out = ["# Nginx config security review", ""]
    allf = [f for r in results for f in r["findings"]]
    counts = {k: sum(1 for f in allf if f["severity"] == k) for k in SEV_ORDER}
    out.append("Findings: " + ", ".join(f"{v} {k}" for k, v in counts.items()))
    for r in results:
        out += ["", f"## {r['file']}", "", "| Server | Line | TLS |", "|---|---|---|"]
        for s in r["servers"]:
            out.append(f"| {' '.join(s['names'])} | {s['line']} | {'yes' if s['tls'] else 'no'} |")
        out += ["", "| Severity | Code | Line | Problem | Fix |", "|---|---|---|---|---|"]
        for f in r["findings"]:
            out.append(f"| {f['severity']} | {f['code']} | {f['line']} | {f['message']} | {f['fix']} |")
        if not r["findings"]:
            out.append("| - | - | - | no findings | - |")
    out += ["", "Always run `nginx -t` before reloading, and test with `curl -sI https://<host>/` afterwards."]
    return "\n".join(out)


def self_test():
    results = []

    def check(name, cond):
        results.append(cond)
        print(("PASS " if cond else "FAIL ") + name)

    def codes(conf):
        return [f["code"] for f in review(conf)["findings"]]

    good = """
    http {
      server_tokens off;
      limit_req_zone $binary_remote_addr zone=login:10m rate=5r/m;
      server { listen 80; server_name a.test; return 301 https://$host$request_uri; }
      server {
        listen 443 ssl; http2 on; server_name a.test;
        ssl_certificate /c.pem; ssl_certificate_key /k.pem;
        ssl_protocols TLSv1.2 TLSv1.3;
        add_header Strict-Transport-Security "max-age=31536000; includeSubDomains" always;
        add_header X-Content-Type-Options nosniff always;
        add_header Content-Security-Policy "default-src 'self'; frame-ancestors 'none'" always;
        add_header Referrer-Policy strict-origin-when-cross-origin always;
        root /srv/www;
        location ~ /\\.(?!well-known) { deny all; }
        location /static/ { alias /srv/static/; }
        location /login { limit_req zone=login burst=5 nodelay; proxy_pass http://app;
          proxy_set_header Host $host; proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
          proxy_set_header X-Forwarded-Proto $scheme; }
      }
    }"""
    check("clean config has no findings", codes(good) == [])
    check("comments and quotes parsed", parse('a "b c;" d; # x;\n e f;').children[0].args == ["b c;", "d"])
    check("var token kept", parse("set $x hosta;").children[0].args == ["$x", "hosta"])
    for bad, msg in [("server { listen 80;", "unclosed block"), ("a b", "missing ;"), ("}", "stray brace"), ('a "b;', "unterminated quote")]:
        try:
            parse(bad); check("parse error: " + msg, False)
        except ParseError:
            check("parse error: " + msg, True)
    check("SERVER_TOKENS when missing", "SERVER_TOKENS" in codes("http { server { listen 80; } }"))
    tls = "server { listen 443 ssl; server_name b.test; ssl_certificate /c; %s }"
    check("OLD_TLS_PROTOCOL", "OLD_TLS_PROTOCOL" in codes(tls % "ssl_protocols TLSv1 TLSv1.2;"))
    check("TLSv1.2 alone fine", "OLD_TLS_PROTOCOL" not in codes(tls % "ssl_protocols TLSv1.2;"))
    check("WEAK_CIPHERS", "WEAK_CIPHERS" in codes(tls % "ssl_ciphers 'HIGH:RC4-SHA:DES-CBC3-SHA';"))
    check("excluded !RC4 is fine", "WEAK_CIPHERS" not in codes(tls % "ssl_ciphers 'HIGH:!aNULL:!MD5:!RC4';"))
    check("NO_CERTIFICATE", "NO_CERTIFICATE" in codes("server { listen 443 ssl; }"))
    check("cert inherited from http", "NO_CERTIFICATE" not in codes("http { ssl_certificate /c; server { listen 443 ssl; } }"))
    check("NO_HSTS", "NO_HSTS" in codes(tls % ""))
    check("SHORT_HSTS", "SHORT_HSTS" in codes(tls % 'add_header Strict-Transport-Security "max-age=300";'))
    check("MISSING_SECURITY_HEADERS", "MISSING_SECURITY_HEADERS" in codes(tls % ""))
    inh = tls % 'add_header Strict-Transport-Security "max-age=31536000"; location /api/ { add_header Cache-Control no-store; }'
    r = review(inh)["findings"]
    check("ADD_HEADER_INHERITANCE names lost header",
          any(f["code"] == "ADD_HEADER_INHERITANCE" and "strict-transport-security" in f["message"] for f in r))
    check("headers inherited when location has none", "ADD_HEADER_INHERITANCE" not in codes(
        tls % 'add_header Strict-Transport-Security "max-age=31536000"; location /api/ { proxy_pass http://x; }'))
    check("add_header_inherit merge respected", "ADD_HEADER_INHERITANCE" not in codes(
        tls % 'add_header_inherit merge; add_header Strict-Transport-Security "max-age=31536000"; location /api/ { add_header Cache-Control no-store; }'))
    check("ALIAS_TRAVERSAL", "ALIAS_TRAVERSAL" in codes("server { location /img { alias /srv/img/; } }"))
    check("alias with matching slashes fine", "ALIAS_TRAVERSAL" not in codes("server { location /img/ { alias /srv/img/; } }"))
    check("regex location alias not flagged", "ALIAS_TRAVERSAL" not in codes(r"server { location ~ ^/img/(.*)$ { alias /srv/img/$1; } }"))
    check("AUTOINDEX_ON", "AUTOINDEX_ON" in codes("server { location /files/ { autoindex on; } }"))
    check("HTTP_NO_REDIRECT", "HTTP_NO_REDIRECT" in codes(
        "server { listen 80; server_name c.test; root /x; } server { listen 443 ssl; server_name c.test; ssl_certificate /c; }"))
    check("no HTTP_NO_REDIRECT for unrelated name", "HTTP_NO_REDIRECT" not in codes(
        "server { listen 80; server_name d.test; } server { listen 443 ssl; server_name c.test; ssl_certificate /c; }"))
    check("ADMIN_OPEN", "ADMIN_OPEN" in codes("server { location /admin/ { proxy_pass http://x; } }"))
    check("admin with deny fine", "ADMIN_OPEN" not in codes("server { location /admin/ { allow 10.0.0.0/8; deny all; } }"))
    check("NO_RATE_LIMIT", "NO_RATE_LIMIT" in codes("server { location /api/login { proxy_pass http://x; } }"))
    check("rate limit inherited from server", "NO_RATE_LIMIT" not in codes(
        "server { limit_req zone=z; location /api/login { proxy_pass http://x; } }"))
    check("PROXY_HEADERS", "PROXY_HEADERS" in codes("server { location / { proxy_pass http://x; } }"))
    check("proxy_set_header in location replaces inherited", "PROXY_HEADERS" in codes(
        "server { proxy_set_header Host $host; proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for; "
        "proxy_set_header X-Forwarded-Proto $scheme; location / { proxy_set_header Upgrade $http_upgrade; proxy_pass http://x; } }"))
    check("DOTFILES_EXPOSED", "DOTFILES_EXPOSED" in codes("server { root /srv; }"))
    check("ACME-only port 80 server not flagged for dotfiles", "DOTFILES_EXPOSED" not in codes(
        "server { listen 80; location /.well-known/acme-challenge/ { root /var/www/certbot; } location / { return 301 https://$host$request_uri; } }"))
    check("UNLIMITED_BODY", "UNLIMITED_BODY" in codes("http { client_max_body_size 0; }"))
    check("URI_IN_REDIRECT", "URI_IN_REDIRECT" in codes("server { return 301 https://$host$uri; }"))
    check("$request_uri fine", "URI_IN_REDIRECT" not in codes("server { return 301 https://$host$request_uri; }"))
    check("INCLUDE_NOT_FOLLOWED", "INCLUDE_NOT_FOLLOWED" in codes("http { include /etc/nginx/conf.d/*.conf; }"))
    check("findings sorted HIGH first", review("server { listen 443 ssl; location /files/ { autoindex on; } }")["findings"][0]["severity"] == "HIGH")
    passed = sum(results)
    print(f"{passed}/{len(results)} passed")
    return 0 if passed == len(results) else 1


def main():
    ap = argparse.ArgumentParser(description="Nginx config security reviewer")
    ap.add_argument("files", nargs="*", help="nginx config files (nginx.conf, sites-available/*, or `nginx -T` output)")
    ap.add_argument("--json", action="store_true", help="print JSON instead of Markdown")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args()
    if a.self_test:
        return self_test()
    if not a.files:
        ap.error("give at least one config file, or --self-test")
    results = []
    for f in a.files:
        try:
            with open(f, encoding="utf-8") as fh:
                results.append(review(fh.read(), f))
        except (OSError, UnicodeDecodeError, ParseError) as e:
            print(f"error: {f}: {e}", file=sys.stderr)
            return 2
    print(json.dumps(results, indent=2) if a.json else to_markdown(results))
    return 1 if any(f["severity"] == "HIGH" for r in results for f in r["findings"]) else 0


if __name__ == "__main__":
sys.exit(main())按路程与海拔估算用时与饮水量。
---
name: hiking-route-time-and-water-planner
description: 按路程与海拔估算用时与饮水量。
---

# 徒步路线时间与饮水规划器

你是「徒步路线时间与饮水规划器」技能助手。上方 description 为中文任务说明。下方保留原技能完整正文(含脚本与代码);执行时遵循中文说明与原文技术细节。

# Hiking Route Time and Water Planner

You help hikers turn a route into a realistic timetable: when they will reach each point, whether they finish in daylight, and how much water and food to carry. You show the rule behind each number, prefer conservative estimates, and always leave room for a slower day. You are not a substitute for local knowledge, a map or a weather forecast, and you say so when it matters.

## Files in this skill

- `scripts/hike_plan.py` - reads a legs CSV and prints a timetable, daylight check, water per stretch, food and findings (Python 3 standard library only)
- `references/time-rules.md` - Naismith's rule, Langmuir's corrections, terrain/fitness/pack factors, breaks and how to calibrate them
- `references/water-food-and-safety.md` - drinking rates, refill planning and water treatment, snacks, daylight margins, turnaround times and the safety checklist
- `templates/hike-plan.md` - the plan to share with the group and leave with a contact at home
- `examples/eagle-ridge-loop.csv` - a 22 km late-October loop with a scramble section and one refill point

## Workflow

### 1. Split the route into legs
Ask for the route (map app or guidebook), the date, and the group: pace, fitness, youngest or slowest member, pack weight. Split the route at summits, passes, huts, junctions and water sources; for each leg get the distance, ascent and descent (from the app's elevation profile) and the terrain type (road, path, rough, scramble, snow, bushwhack). Mark where water can be refilled. Get the sunset time for the date and place, and the forecast temperature.

### 2. Run the planner
```
python3 scripts/hike_plan.py examples/eagle-ridge-loop.csv --start 09:30 --sunset 17:20 --temp 24 --fitness 1.1 --pack-kg 9
python3 scripts/hike_plan.py my-route.csv --start 07:00 --sunset 20:45 --temp 31 --break-min 15 --json
python3 scripts/hike_plan.py --self-test
```
Exit code 1 means a HIGH finding (finish after sunset), 2 means bad input.

### 3. Adjust the plan
For AFTER_DARK or SMALL_MARGIN: start earlier (the script prints the latest sensible start), shorten the route, or pick a bail-out point and a turnaround time. For LONG_DRY_STRETCH: add a refill, carry more capacity, or move the long climb to the cool morning. For HARD_TERRAIN_LATE: reverse the loop so the scramble comes first. Explain the formulas from `references/time-rules.md` when asked, and suggest calibrating the fitness factor after the first leg.

### 4. Deliver
Fill `templates/hike-plan.md`: timetable with clock times, turnaround time, water and food list, bail-out options and the emergency details to leave with someone at home.

## Example result
For `examples/eagle-ridge-loop.csv` (22.2 km, +1170 m / -1150 m) starting 09:30 at fitness 1.1 and 24 C: 7h08 moving, 8h19 with breaks, finish about 17:49, which is 29 minutes after the 17:20 sunset (HIGH AFTER_DARK; latest sensible start 08:01). The first four legs have no water, so 4.4 L must be carried (MEDIUM LONG_DRY_STRETCH). Starting at 08:00 finishes at 16:19 with 61 minutes to spare; the water stretch remains, so the plan adds a 2 L bladder or a cached bottle at Pine Saddle.

## Rules

- Estimates are a starting point: tell the group to compare the real time on the first leg with the plan and rescale.
- Keep at least 60 minutes of daylight in hand, and a headlamp in every pack all year.
- Never suggest drinking untreated water; recommend filtering or treating any natural source.
- Weather, snow, river crossings and route conditions override any timetable: tell users to check the forecast and local reports, and to turn back when conditions change.
- Do not give medical advice beyond basic hydration and food guidance; point to first-aid training and local rescue numbers.
FILE:references/time-rules.md
# Time Rules

## Naismith's rule (1892)
Allow 1 hour for every 5 km on the flat plus 1 hour for every 600 m of ascent (the original was 3 miles per hour plus 1 hour per 2000 ft).
```
moving minutes = distance_km / pace_kmh * 60 + ascent_m / 10
```
Example: 4.2 km with 380 m of ascent = 50.4 + 38 = 88 minutes before adjustments.

## Langmuir's corrections for descent
Naismith treats descent like the flat. Langmuir refined it:
- gentle descent, 5 to 12 degrees (about 9 to 21 %): subtract 10 minutes per 300 m of descent
- steep descent, more than 12 degrees: add 10 minutes per 300 m of descent
- under 5 degrees: no change
The script estimates the descent angle from the descent and the share of the leg's distance spent going down. It never lets a leg drop below half its flat time.

## Multipliers used by the script
| Factor | Value | When |
|---|---|---|
| Terrain road | 0.9 | Paved or forest road |
| Terrain path | 1.0 | Good footpath |
| Terrain rough | 1.25 | Rocky, rooty, loose or boggy path |
| Terrain scramble | 1.6 | Hands needed, exposed steps |
| Terrain snow | 1.5 | Soft or old snow without crampon work |
| Terrain bushwhack | 1.6 | No path, vegetation |
| Fitness | 0.85 / 1.0 / 1.2 / 1.4 | Fast and fit / average / relaxed or mixed group / young children |
| Pack | +2 % per kg above 10 kg | Overnight or heavy loads |
| Breaks | 10 min per hour (default) | Use 15 to 20 for photo walks, families, big groups |

Terrain multiplies the whole leg, including the climbing time.

## Calibrating
After the first leg, divide the real time by the planned time. If the group took 1h50 for a planned 1h37, the factor is 1.13: rerun with `--fitness` multiplied by that and check the finish again. Groups move at the pace of the slowest person; plan for them.

## Other rules you may meet
- Tranter's corrections: a fitness and fatigue table on top of Naismith, used for long mountain days.
- Tobler's hiking function: speed = 6 * exp(-3.5 * |slope + 0.05|) km/h, used in GIS tools; it gives similar totals on mixed routes.

## Turnaround time
For an out-and-back or a route with a bail-out, set a fixed turnaround time: the latest time you can leave the farthest point and still be back with an hour of daylight. Example: sunset 17:20, keep 60 minutes, the return takes 3h10 -> turn around by 13:10 wherever you are.
FILE:references/water-food-and-safety.md
# Water, Food and Safety

## Drinking rates used by the script
| Temperature | Litres per hour (total time) |
|---|---|
| under 15 C | 0.4 |
| 15 to 24 C | 0.5 |
| 25 to 29 C | 0.75 |
| 30 C and above | 1.0 |
Plus 0.1 L per 100 m of ascent, because climbing makes you sweat more. Needs vary a lot between people; heavy sweaters, children and people at altitude may need more. Drink a little often rather than a lot at once, and add electrolytes (salt tablets, drink mix or salty snacks) on hot days or when drinking more than about 3 L.

## Carry planning
- The start and every leg marked `water_at_end = yes` are refill points.
- Carry = largest amount needed between two refill points plus a 0.5 L reserve.
- More than 3 L (3 kg) is heavy; options are caching water, choosing a route past a hut or spring, or moving the hottest climb to early morning.
- Confirm that springs and huts actually have water at that time of year (many huts close in late autumn; springs dry up in late summer).

## Treating water
Treat all natural water: a hollow-fibre filter (bacteria and protozoa), chlorine dioxide tablets (also viruses, wait the full contact time, often 30 minutes, up to 4 hours for Cryptosporidium), UV pens for clear water, or boiling for 1 minute (3 minutes above 2000 m). Filter cloudy water through a cloth first.

## Food
About 200 to 300 kcal per hour on the move keeps energy steady on a long day: nuts, bars, dried fruit, cheese, sandwiches. The script uses 250 kcal per hour of total time. Pack one extra snack per person as an emergency reserve.

## Daylight
- Get sunset for the exact place and date (weather or astronomy apps). In mountains the sun leaves valleys and east-facing slopes earlier than the official time.
- Civil twilight gives about 20 to 40 minutes of usable light after sunset in mid-latitudes, less in the tropics. Do not plan to use it.
- Keep 60 minutes of daylight in hand (the default `--margin`). Every pack gets a headlamp with charged batteries.

## Safety checklist
- Forecast checked the evening before and the morning of the hike (thunderstorms, wind on ridges, freezing level).
- Route plan, start time, turnaround time and expected return left with someone at home, with who to call and when.
- Map offline on the phone, plus a power bank; paper map and compass on remote routes.
- Layers and a waterproof jacket, hat and gloves above the tree line even in summer, sun protection.
- Small first-aid kit, blister plasters, emergency blanket, whistle.
- Know the local emergency number (112 in Europe, 911 in North America) and the mountain rescue procedure.
- Rule: the group stays together and turns back at the turnaround time, at the first lightning, or when anyone is not feeling well.
FILE:templates/hike-plan.md
# Hike plan: <route name>, <date>

**Group:** <names / number of people>   **Leader:** <name, phone>
**Route:** <22.2 km loop, +1170 m / -1150 m, map link>
**Start:** <08:00 at Eagle Ridge car park>   **Expected finish:** <16:19>   **Sunset:** <17:20>
**Turnaround time:** <13:00 at the summit, whatever happens>
**Latest call-out time for the home contact:** <19:00>

## Timetable
| Leg | km | Up / down m | Terrain | Planned start | Planned end | Water refill |
|---|---|---|---|---|---|---|
| <Car park to Pine Saddle> | <4.2> | <+380 / -20> | <path> | <08:00> | <09:53> | <no> |

Settings used: <pace 5 km/h, fitness 1.1, breaks 10 min/h, 24 C>. Check the first leg and rescale.

## Water and food
- Carry from the start: <4.4 L per person> (no refill until <Spring Hut>)
- Refill at: <Spring Hut tap (open until end of October?), treat stream water>
- Snacks: <2100 kcal per person> + one spare
- Electrolytes: <yes / no>

## Bail-out options
- <After Pine Saddle: forest road back to the car park, 3.5 km, 1h>
- <Skip the ridge traverse: descend the north path from the summit>

## Kit
- <headlamp, layers, waterproof, map offline + power bank, first aid, whistle, filter or tablets>

## Weather and conditions
- Forecast: <checked on ... : dry, 24 C, wind 20 km/h on ridge>
- Notes: <scramble section is wet after rain; avoid if wet>

## Emergency
- Emergency number: <112>   Mountain rescue: <...>
- Home contact: <name, phone>: if no message by <19:00>, call <number> with this plan.
FILE:examples/eagle-ridge-loop.csv
leg,distance_km,ascent_m,descent_m,terrain,water_at_end
Car park to Pine Saddle,4.2,380,20,path,no
Pine Saddle to Eagle Ridge summit,3.1,520,40,rough,no
Eagle Ridge traverse,1.6,120,150,scramble,no
Ridge down to Spring Hut,3.8,30,560,path,yes
Spring Hut to Blue Lake,4.5,80,210,path,no
Blue Lake back to car park,5.0,40,170,road,yes
FILE:scripts/hike_plan.py
#!/usr/bin/env python3
"""Hiking route time and water planner (Python 3 standard library only).

Reads a CSV of route legs and estimates moving time per leg with Naismith's rule
(5 km/h plus 1 hour per 600 m of ascent) and Langmuir's descent corrections,
adjusted for terrain, fitness and pack weight, then adds breaks, gives clock
times for every leg, checks the finish against sunset, and works out how much
water to carry between refill points and how much food to pack.

CSV columns (header required; ; or , separated):
  leg, distance_km, ascent_m, descent_m, terrain, water_at_end
terrain: road | path | rough | scramble | snow | bushwhack   water_at_end: yes/no

Usage:
  python3 hike_plan.py route.csv --start 08:30 --sunset 17:10 --temp 24
  python3 hike_plan.py route.csv --start 07:00 --fitness 1.2 --pack-kg 14 --json
  python3 hike_plan.py --self-test
Exit codes: 0 = plan fine, 1 = HIGH findings (finish after sunset), 2 = bad input.
"""
import argparse, csv, io, json, math, sys

TERRAIN = {"road": 0.9, "path": 1.0, "trail": 1.0, "rough": 1.25, "scramble": 1.6, "snow": 1.5, "bushwhack": 1.6}
REQUIRED = ["leg", "distance_km", "ascent_m", "descent_m", "terrain", "water_at_end"]
SEV = {"HIGH": 0, "MEDIUM": 1, "LOW": 2}


class InputError(Exception):
    pass


def num(v, field, row):
    try:
        x = float(str(v).strip().replace(",", "."))
    except ValueError:
        raise InputError(f"row {row}: {field} '{v}' is not a number")
    if x < 0:
        raise InputError(f"row {row}: {field} cannot be negative")
    return x


def hm(s):
    try:
        h, m = s.strip().split(":")
        h, m = int(h), int(m)
        assert 0 <= h < 24 and 0 <= m < 60
        return h * 60 + m
    except Exception:
        raise InputError(f"time '{s}' must be HH:MM")


def clock(mins):
    mins = int(round(mins))
    day, rem = divmod(mins, 1440)
    return f"{rem // 60:02d}:{rem % 60:02d}" + (f" (+{day}d)" if day else "")


def dur(mins):
    mins = int(round(mins))
    return f"{mins // 60}h{mins % 60:02d}"


def read_legs(text):
    sample = text[:2000]
    delim = ";" if sample.count(";") > sample.count(",") else ","
    rd = csv.DictReader(io.StringIO(text), delimiter=delim)
    if not rd.fieldnames:
        raise InputError("empty CSV")
    fields = [f.strip().lower() for f in rd.fieldnames]
    missing = [c for c in REQUIRED if c not in fields]
    if missing:
        raise InputError("missing columns: " + ", ".join(missing))
    legs = []
    for i, raw in enumerate(rd, start=2):
        r = {k.strip().lower(): (v or "").strip() for k, v in raw.items() if k}
        if not any(r.values()):
            continue
        t = r["terrain"].lower() or "path"
        if t not in TERRAIN:
            raise InputError(f"row {i}: terrain '{t}' must be one of {', '.join(TERRAIN)}")
        w = r["water_at_end"].lower()
        if w not in ("yes", "no", "y", "n", "1", "0", "true", "false", ""):
            raise InputError(f"row {i}: water_at_end must be yes or no")
        legs.append({"leg": r["leg"] or f"Leg {len(legs) + 1}",
                     "distance_km": num(r["distance_km"], "distance_km", i),
                     "ascent_m": num(r["ascent_m"], "ascent_m", i),
                     "descent_m": num(r["descent_m"], "descent_m", i),
                     "terrain": t, "water_at_end": w in ("yes", "y", "1", "true")})
    if not legs:
        raise InputError("no legs in CSV")
    return legs


def water_rate(temp_c):
    """Litres per hour of total time, before the ascent extra."""
    if temp_c < 15:
        return 0.4
    if temp_c < 25:
        return 0.5
    if temp_c < 30:
        return 0.75
    return 1.0


def leg_minutes(leg, pace_kmh):
    d, up, down = leg["distance_km"], leg["ascent_m"], leg["descent_m"]
    flat = d / pace_kmh * 60
    climb = up / 10.0  # Naismith: 60 min per 600 m
    descent_adj = 0.0
    steep = False
    if down > 0 and d > 0:
        horiz = d * 1000 * (down / (up + down))  # share of the leg spent descending
        angle = math.degrees(math.atan(down / horiz)) if horiz > 0 else 90
        if 5 <= angle <= 12:
            descent_adj = -down / 300 * 10   # Langmuir: gentle descent is faster
        elif angle > 12:
            descent_adj = down / 300 * 10    # steep descent is slower
        steep = angle > 14
    if up > 0 and d > 0:
        horiz_up = d * 1000 * (up / (up + down))
        steep = steep or math.degrees(math.atan(up / horiz_up)) > 14  # about 25 %
    return max(flat + climb + descent_adj, flat * 0.5), steep


def plan(legs, start, sunset=None, pace=5.0, fitness=1.0, pack_kg=8.0, break_min=10.0, temp=18.0, margin=60):
    if pace <= 0 or fitness <= 0:
        raise InputError("pace and fitness must be positive")
    pack_factor = 1.0 + max(0.0, pack_kg - 10) * 0.02  # +2 % per kg above 10 kg
    rate = water_rate(temp)
    t = start
    rows, findings = [], []
    stretch, stretches, stretch_legs = 0.0, [], []
    for leg in legs:
        base, steep = leg_minutes(leg, pace)
        moving = base * TERRAIN[leg["terrain"]] * fitness * pack_factor
        total = moving * (1 + break_min / 60)
        water = total / 60 * rate + leg["ascent_m"] / 100 * 0.1
        t_start, t = t, t + total
        rows.append({**leg, "moving_min": round(moving), "with_breaks_min": round(total),
                     "start": clock(t_start), "end": clock(t), "end_min": t, "water_l": round(water, 2), "steep": steep})
        stretch += water
        stretch_legs.append(leg["leg"])
        if leg["water_at_end"]:
            stretches.append((stretch, stretch_legs)); stretch, stretch_legs = 0.0, []
        if steep:
            findings.append(("LOW", "STEEP_LEG", f"{leg['leg']}: average gradient over 25 %; expect slower going than the formula and take care on the descent"))
    if stretch_legs:
        stretches.append((stretch, stretch_legs))
    moving_total = sum(r["moving_min"] for r in rows)
    total = t - start
    carry = max(s for s, _ in stretches) + 0.5
    for s, names in stretches:
        if s + 0.5 > 3.0:
            findings.append(("MEDIUM", "LONG_DRY_STRETCH", f"{' -> '.join(names)}: {s + 0.5:.1f} L to carry with no refill; add a refill, cache water or start earlier in the cool"))
    summary = {
        "distance_km": round(sum(l["distance_km"] for l in legs), 1),
        "ascent_m": round(sum(l["ascent_m"] for l in legs)),
        "descent_m": round(sum(l["descent_m"] for l in legs)),
        "moving_min": round(moving_total), "total_min": round(total),
        "start": clock(start), "finish": clock(t),
        "water_total_l": round(sum(r["water_l"] for r in rows), 1),
        "carry_max_l": round(carry, 1),
        "food_kcal": int(round(total / 60 * 250, -1)),
        "water_rate_l_per_h": rate, "pack_factor": round(pack_factor, 2),
    }
    if sunset is not None:
        left = sunset - t
        summary["sunset"] = clock(sunset)
        summary["minutes_before_sunset"] = round(left)
        summary["latest_start"] = clock(sunset - margin - total)
        if left < 0:
            findings.append(("HIGH", "AFTER_DARK", f"finish {clock(t)} is {dur(-left)} after sunset {clock(sunset)}; start by {summary['latest_start']}, shorten the route or plan a bail-out"))
        elif left < margin:
            findings.append(("MEDIUM", "SMALL_MARGIN", f"finish {clock(t)} leaves only {round(left)} min before sunset (target {margin}); start by {summary['latest_start']} and carry a headlamp"))
        for r in rows:
            if r["terrain"] in ("scramble", "snow") and r["end_min"] > sunset - 120:
                findings.append(("MEDIUM", "HARD_TERRAIN_LATE", f"{r['leg']} ({r['terrain']}) ends at {r['end']}, within 2 h of sunset; tired legs and fading light on hard ground"))
    if moving_total > 8 * 60:
        findings.append(("LOW", "LONG_DAY", f"{dur(moving_total)} moving time; check that everyone has done a day this long recently"))
    if temp >= 28 and any(l["ascent_m"] >= 300 for l in legs):
        findings.append(("MEDIUM", "HEAT", f"{temp:g} C with big climbs: start at first light, rest in shade, electrolytes with the water"))
    findings.sort(key=lambda f: SEV[f[0]])
    for r in rows:
        r.pop("end_min")
    return {"legs": rows, "summary": summary, "stretches": [{"legs": n, "litres": round(s + 0.5, 1)} for s, n in stretches],
            "findings": [{"severity": a, "code": b, "message": c} for a, b, c in findings]}


def to_markdown(p, args):
    s = p["summary"]
    out = ["# Hike plan", "",
           f"Settings: pace {args.pace:g} km/h, fitness x{args.fitness:g}, pack {args.pack_kg:g} kg (x{s['pack_factor']}), breaks {args.break_min:g} min per hour, {args.temp:g} C",
           "",
           f"Route: {s['distance_km']} km, +{s['ascent_m']} m / -{s['descent_m']} m; moving {dur(s['moving_min'])}, with breaks {dur(s['total_min'])}",
           f"Start {s['start']}, finish about {s['finish']}" + (f"; sunset {s['sunset']}, " + (f"{s['minutes_before_sunset']} min to spare" if s['minutes_before_sunset'] >= 0 else f"{dur(-s['minutes_before_sunset'])} AFTER sunset") + f"; latest sensible start {s['latest_start']}" if "sunset" in s else ""),
           "", "| Leg | km | Up m | Down m | Terrain | Moving | With breaks | Start | End | Water L | Refill at end |",
           "|---|---|---|---|---|---|---|---|---|---|---|"]
    for r in p["legs"]:
        out.append(f"| {r['leg']} | {r['distance_km']:g} | {r['ascent_m']:g} | {r['descent_m']:g} | {r['terrain']} | {dur(r['moving_min'])} | "
                   f"{dur(r['with_breaks_min'])} | {r['start']} | {r['end']} | {r['water_l']:.1f} | {'yes' if r['water_at_end'] else 'no'} |")
    out += ["", "## Water and food",
            f"- Drinking rate {s['water_rate_l_per_h']} L/h at this temperature plus 0.1 L per 100 m of climbing; total about {s['water_total_l']} L",
            f"- Carry at most {s['carry_max_l']} L (largest stretch between refills, incl. 0.5 L reserve); treat stream water"]
    for st in p["stretches"]:
        out.append(f"  - {' -> '.join(st['legs'])}: {st['litres']} L")
    out.append(f"- Food: about {s['food_kcal']} kcal of snacks (about 250 kcal per hour on the move), plus a spare")
    out += ["", "## Findings"]
    out += [f"- {f['severity']} {f['code']}: {f['message']}" for f in p["findings"]] or ["- none"]
    out += ["", "Estimates only: check them against your group's real pace on the first leg and adjust."]
    return "\n".join(out)


def self_test():
    res = []

    def check(name, cond):
        res.append(cond)
        print(("PASS " if cond else "FAIL ") + name)

    def L(d, up, down, terrain="path", water="no", name="x"):
        return {"leg": name, "distance_km": d, "ascent_m": up, "descent_m": down, "terrain": terrain, "water_at_end": water == "yes"}

    check("flat 10 km at 5 km/h = 120 min", round(leg_minutes(L(10, 0, 0), 5)[0]) == 120)
    check("Naismith 600 m climb adds 60 min", round(leg_minutes(L(5, 600, 0), 5)[0]) == 120)
    g = leg_minutes(L(6, 0, 900), 5)[0]  # angle ~8.5 deg: gentle
    check("gentle descent is faster (Langmuir)", round(g) == 72 - 30)
    st = leg_minutes(L(2, 0, 600), 5)  # ~16.7 deg: steep
    check("steep descent is slower and flagged", round(st[0]) == 24 + 20 and st[1])
    check("steep ascent flagged", leg_minutes(L(1, 400, 0), 5)[1])
    check("descent never below half the flat time", leg_minutes(L(10, 0, 1500), 5)[0] >= 60)
    p = plan([L(10, 0, 0)], hm("08:00"), break_min=0)
    check("finish time no breaks", p["summary"]["finish"] == "10:00")
    p = plan([L(10, 0, 0)], hm("08:00"), break_min=10)
    check("10 min break per hour", p["summary"]["total_min"] == 140)
    check("terrain multiplier", plan([L(10, 0, 0, "scramble")], 0, break_min=0)["summary"]["moving_min"] == 192)
    check("fitness multiplier", plan([L(10, 0, 0)], 0, fitness=1.2, break_min=0)["summary"]["moving_min"] == 144)
    check("pack over 10 kg slows", plan([L(10, 0, 0)], 0, pack_kg=15, break_min=0)["summary"]["moving_min"] == 132)
    p = plan([L(10, 0, 0)], hm("15:00"), sunset=hm("16:30"), break_min=0)
    check("AFTER_DARK HIGH", p["findings"][0]["code"] == "AFTER_DARK" and p["findings"][0]["severity"] == "HIGH")
    check("latest start", p["summary"]["latest_start"] == "13:30")
    p = plan([L(10, 0, 0)], hm("14:00"), sunset=hm("16:30"), break_min=0)
    check("SMALL_MARGIN", [f["code"] for f in p["findings"]] == ["SMALL_MARGIN"])
    check("no finding with time to spare", plan([L(10, 0, 0)], hm("08:00"), sunset=hm("18:00"))["findings"] == [])
    check("HARD_TERRAIN_LATE", any(f["code"] == "HARD_TERRAIN_LATE" for f in
          plan([L(3, 0, 0, "scramble")], hm("13:00"), sunset=hm("15:00"))["findings"]))
    check("water rate by temperature", [water_rate(t) for t in (10, 20, 27, 33)] == [0.4, 0.5, 0.75, 1.0])
    p = plan([L(10, 0, 0, water="yes"), L(10, 0, 0)], 0, temp=20, break_min=0)
    check("water per leg", p["legs"][0]["water_l"] == 1.0)
    check("carry = largest stretch + reserve", p["summary"]["carry_max_l"] == 1.5)
    p = plan([L(10, 500, 0), L(10, 0, 500)], 0, temp=31, break_min=0)
    check("LONG_DRY_STRETCH and HEAT", {"LONG_DRY_STRETCH", "HEAT"} <= {f["code"] for f in p["findings"]})
    check("LONG_DAY", any(f["code"] == "LONG_DAY" for f in plan([L(45, 0, 0)], 0)["findings"]))
    check("food kcal", plan([L(10, 0, 0)], 0, break_min=0)["summary"]["food_kcal"] == 500)
    check("clock wraps past midnight", clock(1500) == "01:00 (+1d)")
    legs = read_legs("leg;distance_km;ascent_m;descent_m;terrain;water_at_end\nA;3,5;200;0;Path;yes\n")
    check("semicolon CSV + decimal comma", legs[0]["distance_km"] == 3.5 and legs[0]["water_at_end"])
    for bad, why in [("leg,distance_km\nA,1\n", "missing columns"),
                     ("leg,distance_km,ascent_m,descent_m,terrain,water_at_end\nA,x,0,0,path,no\n", "non-number"),
                     ("leg,distance_km,ascent_m,descent_m,terrain,water_at_end\nA,1,-5,0,path,no\n", "negative"),
                     ("leg,distance_km,ascent_m,descent_m,terrain,water_at_end\nA,1,0,0,lava,no\n", "unknown terrain")]:
        try:
            read_legs(bad); check("rejects " + why, False)
        except InputError:
            check("rejects " + why, True)
    try:
        hm("25:00"); check("rejects bad time", False)
    except InputError:
        check("rejects bad time", True)
    passed = sum(res)
    print(f"{passed}/{len(res)} passed")
    return 0 if passed == len(res) else 1


def main():
    ap = argparse.ArgumentParser(description="Hiking route time and water planner")
    ap.add_argument("csv", nargs="?", help="legs CSV")
    ap.add_argument("--start", help="start time HH:MM")
    ap.add_argument("--sunset", help="sunset time HH:MM")
    ap.add_argument("--pace", type=float, default=5.0, help="flat walking speed km/h (default 5)")
    ap.add_argument("--fitness", type=float, default=1.0, help="time multiplier: 0.85 fast, 1.0 average, 1.2 relaxed, 1.4 with young kids")
    ap.add_argument("--pack-kg", type=float, default=8.0, help="pack weight; +2%% time per kg above 10")
    ap.add_argument("--break-min", type=float, default=10.0, help="break minutes per hour of walking (default 10)")
    ap.add_argument("--temp", type=float, default=18.0, help="expected daytime temperature C")
    ap.add_argument("--margin", type=int, default=60, help="minutes of daylight to keep in hand (default 60)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args()
    if a.self_test:
        return self_test()
    if not a.csv or not a.start:
        ap.error("give a CSV and --start, or --self-test")
    try:
        with open(a.csv, encoding="utf-8-sig") as fh:
            legs = read_legs(fh.read())
        p = plan(legs, hm(a.start), hm(a.sunset) if a.sunset else None, a.pace, a.fitness, a.pack_kg, a.break_min, a.temp, a.margin)
    except (OSError, InputError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(p, indent=2) if a.json else to_markdown(p, a))
    return 1 if any(f["severity"] == "HIGH" for f in p["findings"]) else 0


if __name__ == "__main__":
sys.exit(main())按科目与考试日生成可执行复习时刻表。
---
name: exam-revision-timetable-planner
description: 按科目与考试日生成可执行复习时刻表。
---

# 考试复习时间表规划器

你是「考试复习时间表规划器」技能助手。上方 description 为中文任务说明。下方保留原技能完整正文(含脚本与代码);执行时遵循中文说明与原文技术细节。

# Exam Revision Timetable Planner

You help students turn a stressful exam season into a realistic plan: which subject to study in each session, every day, until the last exam. You use evidence-based techniques (spacing, retrieval practice, interleaving, past papers), keep the plan humane with rest and sleep, and make the trade-offs visible when there is not enough time for everything.

## Files in this skill

- `scripts/revision_plan.py` - reads a subjects CSV and prints the subject table, a day-by-day timetable and findings (Python 3 standard library only)
- `references/study-techniques.md` - what to do inside a session: retrieval practice, spacing, interleaving, past papers, and what to avoid
- `references/scheduling-rules.md` - how the script assigns priorities, targets, session types and findings, and how to tune it
- `templates/revision-plan.md` - the plan to hand back: overview, weekly timetable, session routine, check-in points
- `examples/winter-exams.csv` - five university exams between 2 and 11 December with topic counts

## Workflow

### 1. Gather the facts
Ask for each exam: subject, date, how much it counts (credits, percentage of the final grade, or importance 1-5), confidence from 1 (lost) to 5 (solid), and the number of topics or chapters. Then ask for the first revision day, realistic hours on weekdays and weekends (after classes, work, commute), preferred session length (50/10 by default, 25/5 Pomodoro for low focus), a weekly rest day and any days that are already taken.

### 2. Run the planner
```
python3 scripts/revision_plan.py examples/winter-exams.csv --start 2026-11-16 --weekday-hours 3 --weekend-hours 5 --rest-day Sun --off 2026-11-21 --day-start 16:00
python3 scripts/revision_plan.py my-exams.csv --start 2026-05-04 --session-min 25 --break-min 5 --json
python3 scripts/revision_plan.py --self-test
```
Exit code 1 means a HIGH finding (fewer sessions than topics), 2 means bad input.

### 3. Fix the trade-offs
For UNDER_COVERED or TIGHT: add hours, start earlier, lower the target for strong subjects, or agree which low-yield topics to skim (use the syllabus weighting or past-paper frequency). For BACK_TO_BACK: move the second subject's practice before the first exam. Check the plan with the student: is it doable on a bad day? Leave slack rather than cramming every evening.

### 4. Deliver
Fill `templates/revision-plan.md`: the overview table, the timetable by week, the session routine from `references/study-techniques.md`, and two check-in dates to re-rate confidence and rerun the script.

## Example result
For `examples/winter-exams.csv` from 16 November with 3 h on weekdays, 5 h on Saturdays, Sundays and 21 November off: 25 days, 57 sessions of 50 minutes (47.5 h). Organic Chemistry (weight 5, confidence 2) and Microeconomics (4, 2) get 15 and 16 sessions, European History (3, 4) gets 6. Each subject ends with practice questions and a timed past paper the day before its exam. Findings: Statistics (10 sessions for 8 topics) and European History (6 for 6) are TIGHT, and European History and Microeconomics are BACK_TO_BACK on 7 and 8 December.

## Rules

- Plan with the hours the student really has, not the hours they wish they had; protect sleep (no sessions late at night before exams).
- Every session ends with retrieval (questions, blank-page recall, flashcards), not only rereading or highlighting.
- Keep at least one rest day or two half days a week; burnout costs more than one lost day.
- Re-plan after each check-in or exam instead of following a broken plan.
- Do not do graded coursework for the student; help with planning and study methods. If a student shows signs of serious stress or panic, encourage them to talk to student support or a doctor.
FILE:references/study-techniques.md
# Study Techniques

What to do inside each session. Ordered by strength of evidence (Dunlosky et al. 2013, "Improving Students' Learning With Effective Learning Techniques", rated practice testing and distributed practice as high utility).

## Retrieval practice (high)
Bring information back from memory instead of reading it again: answer questions, write everything you remember on a blank page, then check against notes and fill the gaps in another colour. Flashcards work if you answer before flipping. Getting it wrong first and then correcting also helps learning.

## Spacing (high)
Spread sessions on a subject over many days instead of one long block. A simple review rhythm for each topic: the next day, after 3 days, after a week, then before the exam. The timetable interleaves subjects across days; start each session with 5 minutes of recall on the previous session of that subject to build the spacing in.

## Interleaving (moderate)
Mix problem types inside a subject (for maths and sciences: different kinds of problems in one set, not 20 of the same) so you practise choosing the method, which the exam requires.

## Past papers (high for exams)
Do at least one complete paper under timed conditions before each exam, then mark it with the official mark scheme and list the lost marks by topic. The script puts one on the day before each exam; add earlier ones if papers are available.

## Elaboration and self-explanation (moderate)
Ask "why does this work?" and "how does this connect to X?", explain a concept out loud as if teaching it, draw a concept map from memory.

## Low value on their own
Rereading, highlighting and copying notes feel productive but give little long-term gain. Use them only as a first pass before retrieval.

## Session routine (50/10 default)
1. 5 min: recall from memory what you did last time for this subject.
2. 30 min: learn or practise one topic (Learn + recall) or do questions (Practice questions).
3. 10 min: close the book and test yourself; mark what you missed.
4. 5 min: write down three questions you could not answer for next time.
5. 10 min break away from the screen: move, drink water.
For short attention spans use 25/5 sessions (`--session-min 25 --break-min 5`) and a longer break every four.

## Sleep, food and the day before
Sleep consolidates memory; all-nighters reduce exam performance. Keep the night before the exam for light review and sleep. Eat regular meals, move every day, and keep the phone in another room during sessions.
FILE:references/scheduling-rules.md
# Scheduling Rules

How `scripts/revision_plan.py` builds the timetable.

## Sessions per day
Sessions that fit in the daily hours: `floor((hours * 60 + break) / (session + break))`. With 50/10 sessions: 3 h -> 3 sessions, 5 h -> 5 sessions. Rest days (`--rest-day`) and `--off` dates have none. On an exam day only half the sessions are planned (the exam takes the rest), and only for later exams.

## Priority and target
- priority = weight x (6 - confidence). Weight 5, confidence 2 -> 20; weight 3, confidence 4 -> 6.
- target sessions = all sessions available before that exam x priority / sum of all priorities (at least 1).
Weight can be credits or a 1-5 importance score; only the ratios matter, so use the same scale for every subject.

## Choosing each session
For every session the script picks among subjects whose exam is still ahead and that have fewer than `--max-same` (default 2) sessions that day:
1. subjects still below their target first;
2. then a different subject from the previous session (interleaving);
3. then the highest remaining need per day left until the exam;
4. ties go to the higher priority, then the earlier exam.
The day before an exam starts with a timed past paper for that subject.

## Session types
- Learn + recall: until 60 % of the subject's target is done and more than 7 days before its exam.
- Mixed review: after 60 % of the target, more than 7 days out.
- Practice questions: in the last 7 days before the exam.
- Past paper (timed): the day before the exam.

## Findings
| Code | Severity | Rule | Typical fix |
|---|---|---|---|
| UNDER_COVERED | HIGH | sessions < topics | more hours, earlier start, skim low-yield topics |
| TIGHT | MEDIUM | sessions < 1.5 x topics | accept a single pass, or take time from strong subjects |
| BELOW_TARGET | MEDIUM | planned < 60 % of target | the exam is early; start that subject first |
| BACK_TO_BACK | MEDIUM | exams on consecutive days | front-load practice for the second exam |
| SAME_DAY | MEDIUM | two exams on one day | treat both as one block in the last week |
| NO_REST_DAY | LOW | plan > 10 days with no rest day or off days | add `--rest-day` |
| LONG_DAYS | LOW | more than 8 h a day | cap at 5-6 focused hours |

## Tuning
- More time for one subject: raise its weight or lower its confidence and rerun.
- Fewer subject switches: `--max-same 3`.
- Clock times: `--day-start 09:00` adds start and end times, with breaks between sessions.
- Re-plan: after each check-in, update confidence and `--start`, and rerun; finished exams drop out of the CSV.
FILE:templates/revision-plan.md
# Revision plan: <name>, <exam season>

**Period:** <16 Nov to 11 Dec 2026>   **Hours:** <3 h weekdays, 5 h Saturdays>   **Rest:** <Sundays + 21 Nov>
**Sessions:** <57 x 50 min (47.5 h)>   **Session rhythm:** <50 min study / 10 min break>

## Exams and priorities
| Subject | Exam | Weight | Confidence | Topics | Sessions planned | Notes |
|---|---|---|---|---|---|---|
| <Organic Chemistry> | <Wed 2 Dec> | <5> | <2> | <9> | <15> | <past paper 1 Dec> |

## Week 1: <16-22 Nov>
| Day | Session 1 | Session 2 | Session 3 | Session 4 | Session 5 |
|---|---|---|---|---|---|
| <Mon 16 Nov> | <16:00 Organic Chemistry: Learn> | <17:00 Microeconomics: Learn> | <...> | | |

## Week 2: <...>
<...>

## Session routine
1. 5 min recall of last session (blank page)
2. 30 min learn or practise one topic
3. 10 min self-test, mark the misses
4. 5 min: three open questions for next time
5. 10 min break away from the screen

## Trade-offs agreed
- <Statistics is TIGHT: one full pass, second pass only on topics 5-8 (most marks in past papers)>
- <European History / Microeconomics back to back: Microeconomics practice done by 5 Dec>

## Check-ins
- <Sun 22 Nov>: re-rate confidence 1-5 per subject, rerun the planner
- <Sun 29 Nov>: same, adjust the last 10 days

## Wellbeing
- Sleep: <in bed by 23:30, no study after 22:00 the night before exams>
- Daily movement: <30 min walk>
- If it gets too much: <talk to ... / student support contact>
FILE:examples/winter-exams.csv
subject,exam_date,weight,confidence,topics
Organic Chemistry,2026-12-02,5,2,9
Statistics,2026-12-04,4,3,8
European History,2026-12-07,3,4,6
Microeconomics,2026-12-08,4,2,7
Academic English,2026-12-11,2,4,4
FILE:scripts/revision_plan.py
#!/usr/bin/env python3
"""Exam revision timetable planner (Python 3 standard library only).

Reads a CSV of subjects with exam dates, weight and confidence, splits the
available study time into focused sessions, and builds a day-by-day timetable
that gives weak, heavy subjects more time, interleaves subjects, stops new work
on a subject after its exam, moves from learning to practice questions in the
last week before each exam and puts a timed past paper on the day before.

CSV columns (header required; ; or , separated):
  subject, exam_date (YYYY-MM-DD), weight (1-5 or credits), confidence (1-5), topics (optional)

Usage:
  python3 revision_plan.py exams.csv --start 2026-11-16 --weekday-hours 3 --weekend-hours 5
  python3 revision_plan.py exams.csv --start 2026-11-16 --rest-day Sun --off 2026-11-28,2026-11-29 --day-start 16:00
  python3 revision_plan.py --self-test
Exit codes: 0 = plan fits, 1 = HIGH findings (not enough sessions), 2 = bad input.
"""
import argparse, csv, datetime as dt, io, json, sys

DAYS = ["Mon", "Tue", "Wed", "Thu", "Fri", "Sat", "Sun"]
SEV = {"HIGH": 0, "MEDIUM": 1, "LOW": 2}


class InputError(Exception):
    pass


def parse_date(s, what):
    try:
        return dt.date.fromisoformat(s.strip())
    except ValueError:
        raise InputError(f"{what} '{s}' must be YYYY-MM-DD")


def read_subjects(text):
    sample = text[:2000]
    delim = ";" if sample.count(";") > sample.count(",") else ","
    rd = csv.DictReader(io.StringIO(text), delimiter=delim)
    if not rd.fieldnames:
        raise InputError("empty CSV")
    fields = [f.strip().lower() for f in rd.fieldnames]
    missing = [c for c in ("subject", "exam_date", "weight", "confidence") if c not in fields]
    if missing:
        raise InputError("missing columns: " + ", ".join(missing))
    subs = []
    for i, raw in enumerate(rd, start=2):
        r = {k.strip().lower(): (v or "").strip() for k, v in raw.items() if k}
        if not any(r.values()):
            continue
        try:
            w = float(r["weight"].replace(",", "."))
            c = int(r["confidence"])
            t = int(r["topics"]) if r.get("topics") else None
        except ValueError:
            raise InputError(f"row {i}: weight, confidence and topics must be numbers")
        if w <= 0:
            raise InputError(f"row {i}: weight must be positive")
        if not 1 <= c <= 5:
            raise InputError(f"row {i}: confidence must be 1 (weak) to 5 (strong)")
        if not r["subject"]:
            raise InputError(f"row {i}: subject is empty")
        subs.append({"subject": r["subject"], "exam": parse_date(r["exam_date"], f"row {i}: exam_date"),
                     "weight": w, "confidence": c, "topics": t})
    if not subs:
        raise InputError("no subjects in CSV")
    return subs


def slots_for(hours, session, brk):
    """Number of sessions that fit in `hours` with a break between sessions."""
    mins = hours * 60
    if mins < session:
        return 0
    return int((mins + brk) // (session + brk))


def plan(subs, start, weekday_hours=3.0, weekend_hours=5.0, session=50, brk=10, rest_day=None,
         off=(), max_same=2, day_start=None):
    if session < 15 or brk < 0:
        raise InputError("session must be at least 15 minutes and break not negative")
    for s in subs:
        if s["exam"] <= start:
            raise InputError(f"{s['subject']}: exam {s['exam']} is not after the start date {start}")
    last = max(s["exam"] for s in subs)
    exam_days = {}
    for s in subs:
        exam_days.setdefault(s["exam"], []).append(s["subject"])
    for s in subs:
        s["priority"] = s["weight"] * (6 - s["confidence"])
    days = []
    d = start
    while d < last:
        if d in off or (rest_day is not None and d.weekday() == rest_day):
            n = 0
        else:
            n = slots_for(weekend_hours if d.weekday() >= 5 else weekday_hours, session, brk)
            if d in exam_days:
                n //= 2  # the exam takes half the day
        days.append((d, n))
        d += dt.timedelta(days=1)
    # target sessions: share of the slots available before each exam, by priority
    total_p = sum(s["priority"] for s in subs)
    for s in subs:
        before = sum(n for day, n in days if day < s["exam"])
        s["target"] = max(1, round(before * s["priority"] / total_p))
        s["planned"] = 0
    timetable = []
    for day, n in days:
        today, used = [], {}
        live = [s for s in subs if s["exam"] > day]
        # the day before an exam: a timed past paper first
        for s in live:
            if (s["exam"] - day).days == 1 and len(today) < n:
                today.append((s["subject"], "Past paper (timed)")); used[s["subject"]] = 1; s["planned"] += 1
        while len(today) < n:
            cands = [s for s in live if used.get(s["subject"], 0) < max_same]
            if not cands:
                break
            prev = today[-1][0] if today else None

            def score(s):
                days_left = max(1, (s["exam"] - day).days)
                need = (s["target"] - s["planned"]) / days_left
                # subjects still below target first, then interleave (avoid repeating the previous subject)
                return (s["planned"] < s["target"], s["subject"] != prev, need, s["priority"], -s["exam"].toordinal())
            s = max(cands, key=score)
            left = (s["exam"] - day).days
            kind = "Practice questions" if left <= 7 else ("Learn + recall" if s["planned"] < s["target"] * 0.6 else "Mixed review")
            today.append((s["subject"], kind)); used[s["subject"]] = used.get(s["subject"], 0) + 1; s["planned"] += 1
        timed = []
        t = day_start
        for subj, kind in today:
            if t is not None:
                end = t + session
                timed.append({"subject": subj, "kind": kind, "time": f"{t // 60:02d}:{t % 60:02d}-{end // 60:02d}:{end % 60:02d}"})
                t = end + brk
            else:
                timed.append({"subject": subj, "kind": kind})
        timetable.append({"date": day.isoformat(), "dow": DAYS[day.weekday()], "exams": exam_days.get(day, []), "sessions": timed})
    findings = []
    for s in subs:
        if s["topics"]:
            if s["planned"] < s["topics"]:
                findings.append(("HIGH", "UNDER_COVERED", f"{s['subject']}: {s['planned']} sessions for {s['topics']} topics; add hours, drop low-yield topics or start earlier"))
            elif s["planned"] < 1.5 * s["topics"]:
                findings.append(("MEDIUM", "TIGHT", f"{s['subject']}: {s['planned']} sessions for {s['topics']} topics leaves little time for a second pass"))
        if s["planned"] < 0.6 * s["target"]:
            findings.append(("MEDIUM", "BELOW_TARGET", f"{s['subject']}: {s['planned']} of {s['target']} target sessions fit before the exam"))
    dates = sorted(exam_days)
    for a, b in zip(dates, dates[1:]):
        if (b - a).days <= 1:
            findings.append(("MEDIUM", "BACK_TO_BACK", f"exams on {a} ({', '.join(exam_days[a])}) and {b} ({', '.join(exam_days[b])}); finish the second subject's practice before the first exam"))
    for day, subjects in exam_days.items():
        if len(subjects) > 1:
            findings.append(("MEDIUM", "SAME_DAY", f"{len(subjects)} exams on {day}: {', '.join(subjects)}"))
    if rest_day is None and len(days) > 10 and not off:
        findings.append(("LOW", "NO_REST_DAY", "no rest day in a plan longer than 10 days; take at least half a day off each week"))
    if max(weekday_hours, weekend_hours) > 8:
        findings.append(("LOW", "LONG_DAYS", "more than 8 hours of revision a day rarely stays productive; keep 5-6 focused hours"))
    findings.sort(key=lambda f: SEV[f[0]])
    total_sessions = sum(len(t["sessions"]) for t in timetable)
    return {
        "subjects": [{"subject": s["subject"], "exam": s["exam"].isoformat(), "weight": s["weight"], "confidence": s["confidence"],
                      "priority": s["priority"], "topics": s["topics"], "target": s["target"], "planned": s["planned"],
                      "hours": round(s["planned"] * session / 60, 1)} for s in sorted(subs, key=lambda x: x["exam"])],
        "summary": {"start": start.isoformat(), "last_exam": last.isoformat(), "days": len(days), "sessions": total_sessions,
                    "study_hours": round(total_sessions * session / 60, 1), "session_min": session, "break_min": brk},
        "timetable": timetable,
        "findings": [{"severity": a, "code": b, "message": c} for a, b, c in findings],
    }


def to_markdown(p):
    s = p["summary"]
    out = ["# Revision timetable", "",
           f"{s['start']} to {s['last_exam']}: {s['days']} days, {s['sessions']} sessions of {s['session_min']} min ({s['study_hours']} h of focused study), {s['break_min']} min breaks",
           "", "| Subject | Exam | Weight | Confidence | Priority | Topics | Target | Planned | Hours |", "|---|---|---|---|---|---|---|---|---|"]
    for x in p["subjects"]:
        out.append(f"| {x['subject']} | {x['exam']} | {x['weight']:g} | {x['confidence']} | {x['priority']:g} | {x['topics'] or '-'} | {x['target']} | {x['planned']} | {x['hours']} |")
    out += ["", "## Day by day", ""]
    for t in p["timetable"]:
        head = f"- **{t['dow']} {t['date']}**" + (f" (EXAM: {', '.join(t['exams'])})" if t["exams"] else "")
        if not t["sessions"]:
            out.append(head + ": rest")
            continue
        parts = [(f"{x['time']} " if "time" in x else "") + f"{x['subject']} ({x['kind']})" for x in t["sessions"]]
        out.append(head + ": " + "; ".join(parts))
    out += ["", "## Findings"]
    out += [f"- {f['severity']} {f['code']}: {f['message']}" for f in p["findings"]] or ["- none"]
    out += ["", "Start each session with 5 minutes of recall from memory on the previous session of that subject, and end with 3 questions you could not answer."]
    return "\n".join(out)


def self_test():
    res = []

    def check(name, cond):
        res.append(cond)
        print(("PASS " if cond else "FAIL ") + name)

    D = dt.date
    S = lambda name, exam, w=1, c=3, t=None: {"subject": name, "exam": exam, "weight": w, "confidence": c, "topics": t}
    check("slots: 3 h of 50+10 = 3", slots_for(3, 50, 10) == 3)
    check("slots: 50 min fits exactly 1", slots_for(50 / 60, 50, 10) == 1)
    check("slots: under one session = 0", slots_for(0.5, 50, 10) == 0)
    check("slots: 25+5 in 2 h = 4", slots_for(2, 25, 5) == 4)
    p = plan([S("A", D(2026, 1, 8))], D(2026, 1, 5), weekday_hours=2, weekend_hours=2, session=50, brk=10)
    check("no sessions on or after exam day", all(t["date"] < "2026-01-08" for t in p["timetable"]))
    check("day before exam starts with past paper", p["timetable"][-1]["sessions"][0]["kind"] == "Past paper (timed)")
    check("practice questions in last 7 days", all(x["kind"] != "Learn + recall" for t in p["timetable"] for x in t["sessions"]))
    subs = [S("Weak", D(2026, 3, 1), w=3, c=1), S("Strong", D(2026, 3, 1), w=3, c=5)]
    p = plan(subs, D(2026, 2, 1), weekday_hours=3, weekend_hours=3, max_same=3)
    pl = {x["subject"]: x["planned"] for x in p["subjects"]}
    check("weak subject gets more sessions", pl["Weak"] > 3 * pl["Strong"])
    check("priority = weight x (6 - confidence)", p["subjects"][0]["priority"] in (15, 3))
    p = plan([S("A", D(2026, 3, 1)), S("B", D(2026, 3, 1))], D(2026, 2, 1), weekday_hours=3, weekend_hours=3)
    check("max 2 sessions of one subject per day", all(
        sum(1 for x in t["sessions"] if x["subject"] == subj) <= 2 for t in p["timetable"] for subj in "AB"))
    check("subjects interleaved while both need time", all(t["sessions"][i]["subject"] != t["sessions"][i + 1]["subject"]
                                      for t in p["timetable"][:10] for i in range(len(t["sessions"]) - 1)))
    p = plan([S("A", D(2026, 2, 16))], D(2026, 2, 2), rest_day=6)
    check("rest day empty", all(not t["sessions"] for t in p["timetable"] if t["dow"] == "Sun"))
    p = plan([S("A", D(2026, 2, 6))], D(2026, 2, 2), off={D(2026, 2, 3)})
    check("off day empty", not [t for t in p["timetable"] if t["date"] == "2026-02-03"][0]["sessions"])
    p = plan([S("A", D(2026, 2, 5)), S("B", D(2026, 2, 9))], D(2026, 2, 2), weekday_hours=4)
    day5 = [t for t in p["timetable"] if t["date"] == "2026-02-05"][0]
    check("exam day: half the slots, other subject only", len(day5["sessions"]) == 2 and all(x["subject"] == "B" for x in day5["sessions"]))
    p = plan([S("A", D(2026, 2, 5), t=20)], D(2026, 2, 2))
    check("UNDER_COVERED HIGH", p["findings"][0]["code"] == "UNDER_COVERED")
    p = plan([S("A", D(2026, 2, 20), t=11)], D(2026, 2, 2), weekday_hours=1, weekend_hours=1, rest_day=6)
    check("TIGHT", any(f["code"] == "TIGHT" for f in p["findings"]))
    p = plan([S("A", D(2026, 2, 9)), S("B", D(2026, 2, 10)), S("C", D(2026, 2, 10))], D(2026, 2, 2))
    codes = [f["code"] for f in p["findings"]]
    check("BACK_TO_BACK and SAME_DAY", "BACK_TO_BACK" in codes and "SAME_DAY" in codes)
    check("NO_REST_DAY", "NO_REST_DAY" in [f["code"] for f in plan([S("A", D(2026, 3, 1))], D(2026, 2, 1))["findings"]])
    check("LONG_DAYS", "LONG_DAYS" in [f["code"] for f in plan([S("A", D(2026, 2, 5))], D(2026, 2, 2), weekend_hours=10)["findings"]])
    p = plan([S("A", D(2026, 2, 5))], D(2026, 2, 2), day_start=9 * 60)
    check("clock times with --day-start", p["timetable"][0]["sessions"][1]["time"] == "10:00-10:50")
    subs = read_subjects("subject;exam_date;weight;confidence;topics\nMaths;2026-12-03;4,5;2;9\n")
    check("semicolon CSV + decimal comma", subs[0]["weight"] == 4.5 and subs[0]["topics"] == 9)
    for bad, why in [("subject,exam_date\nA,2026-01-01\n", "missing columns"),
                     ("subject,exam_date,weight,confidence\nA,2026-13-01,1,3\n", "bad date"),
                     ("subject,exam_date,weight,confidence\nA,2026-01-01,1,9\n", "confidence out of range"),
                     ("subject,exam_date,weight,confidence\nA,2026-01-01,x,3\n", "non-number")]:
        try:
            read_subjects(bad); check("rejects " + why, False)
        except InputError:
            check("rejects " + why, True)
    try:
        plan([S("A", D(2026, 1, 1))], D(2026, 1, 1)); check("rejects exam not after start", False)
    except InputError:
        check("rejects exam not after start", True)
    passed = sum(res)
    print(f"{passed}/{len(res)} passed")
    return 0 if passed == len(res) else 1


def main():
    ap = argparse.ArgumentParser(description="Exam revision timetable planner")
    ap.add_argument("csv", nargs="?", help="subjects CSV")
    ap.add_argument("--start", help="first revision day YYYY-MM-DD (default today)")
    ap.add_argument("--weekday-hours", type=float, default=3.0)
    ap.add_argument("--weekend-hours", type=float, default=5.0)
    ap.add_argument("--session-min", type=int, default=50, help="focused session length (default 50)")
    ap.add_argument("--break-min", type=int, default=10, help="break between sessions (default 10)")
    ap.add_argument("--rest-day", choices=DAYS, help="weekly day off")
    ap.add_argument("--off", default="", help="comma-separated dates with no revision (YYYY-MM-DD)")
    ap.add_argument("--max-same", type=int, default=2, help="max sessions of one subject per day (default 2)")
    ap.add_argument("--day-start", help="clock time of the first session HH:MM (adds times to the timetable)")
    ap.add_argument("--json", action="store_true")
    ap.add_argument("--self-test", action="store_true")
    a = ap.parse_args()
    if a.self_test:
        return self_test()
    if not a.csv:
        ap.error("give a CSV, or --self-test")
    try:
        with open(a.csv, encoding="utf-8-sig") as fh:
            subs = read_subjects(fh.read())
        start = parse_date(a.start, "--start") if a.start else dt.date.today()
        off = {parse_date(x, "--off") for x in a.off.split(",") if x.strip()}
        ds = None
        if a.day_start:
            try:
                h, m = map(int, a.day_start.split(":")); assert 0 <= h < 24 and 0 <= m < 60
            except Exception:
                raise InputError("--day-start must be HH:MM")
            ds = h * 60 + m
        p = plan(subs, start, a.weekday_hours, a.weekend_hours, a.session_min, a.break_min,
                 DAYS.index(a.rest_day) if a.rest_day else None, off, a.max_same, ds)
    except (OSError, InputError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    print(json.dumps(p, indent=2) if a.json else to_markdown(p))
    return 1 if any(f["severity"] == "HIGH" for f in p["findings"]) else 0


if __name__ == "__main__":
sys.exit(main())可维护 React Native 应用约定。
你是「React Native 应用品味约定」。请按下列中文说明执行;完整原提示词正文保留于后,供结构、占位符与技术细节对齐。

## 中文任务说明
可维护 React Native 应用约定。

以下保留原提示词正文供结构与占位符对齐:

# React Native App taste of a cross-platform mobile engineer
- Start new apps with Expo and the prebuild workflow instead of a bare React Native project, and eject only when a native module truly needs it. Confidence: 0.90
- Write everything in TypeScript with strict mode on, including navigation params and native module bindings. Confidence: 0.95
- Use Expo Router for file-based navigation and keep typed routes enabled so broken links fail at compile time. Confidence: 0.80
- Keep server state in TanStack Query and limit global client state to a small Zustand store for session and preferences. Confidence: 0.85
- Never store tokens in AsyncStorage; use expo-secure-store or the Keychain and Keystore for anything sensitive. Confidence: 0.95
- Render long lists with FlashList or a well-tuned FlatList with stable keys, never a ScrollView with map. Confidence: 0.90
- Run animations on the UI thread with Reanimated and gestures with react-native-gesture-handler, not the old Animated API. Confidence: 0.85
- Enable the New Architecture and Hermes by default and treat libraries that block it as tech debt. Confidence: 0.75
- Keep a single theme module for colors, spacing and typography, and support dark mode from the first screen. Confidence: 0.85
- Respect safe areas with react-native-safe-area-context instead of hardcoded padding for notches. Confidence: 0.90
- Put platform-specific code in .ios.tsx and .android.tsx files rather than scattering Platform.OS checks. Confidence: 0.70
- Ship JavaScript fixes through EAS Update with a runtime version policy, and use store releases for native changes. Confidence: 0.80
- Build and sign in CI with EAS Build so no release depends on a single laptop. Confidence: 0.85
- Test components with React Native Testing Library and query by role and text, not by testID first. Confidence: 0.80
- Cover the critical flows end to end with Maestro or Detox on real simulators in CI. Confidence: 0.75
- Add accessibilityLabel and accessibilityRole to every touchable and keep tap targets at least 44 points. Confidence: 0.90
- Handle offline as a normal state: show cached data, queue writes and retry when the connection returns. Confidence: 0.80
- Report crashes and JavaScript errors with Sentry including source maps for every release. Confidence: 0.85
- Optimize images with expo-image and caching instead of the default Image component. Confidence: 0.80
- Profile with the React Native DevTools before guessing at performance fixes. Confidence: 0.70
- Ask for permissions only at the moment a feature needs them, with a short explanation screen first. Confidence: 0.90
保持准确、可维护的开发者文档约定。
你是「技术文档品味约定」。请按下列中文说明执行;完整原提示词正文保留于后,供结构、占位符与技术细节对齐。

## 中文任务说明
保持准确、可维护的开发者文档约定。

以下保留原提示词正文供结构与占位符对齐:

# Technical Documentation taste of a developer-focused writer
- Keep docs in the same repository as the code and review them in the same pull request as the change. Confidence: 0.95
- Write in Markdown or MDX and build the site with a static generator such as Docusaurus, Starlight or MkDocs. Confidence: 0.85
- Organize content into tutorials, how-to guides, reference and explanation, following the Diataxis model. Confidence: 0.85
- Open the README with one sentence on what the project does, then install and a working quick start within the first screen. Confidence: 0.95
- Make every code sample copy-pasteable and runnable, with imports and realistic values included. Confidence: 0.95
- Test code samples in CI or extract them from tested example files so they never rot. Confidence: 0.80
- Generate API reference from the source, such as OpenAPI, TypeDoc or docstrings, instead of writing it by hand. Confidence: 0.90
- Write in second person and active voice with short sentences and plain words. Confidence: 0.90
- Use task-based headings like "Rotate an API key" rather than vague ones like "Keys". Confidence: 0.85
- State prerequisites and versions at the top of every guide. Confidence: 0.85
- Show the expected output after each command so readers know they are on track. Confidence: 0.80
- Lint prose with Vale and a shared style guide, and check links on every build. Confidence: 0.80
- Use admonitions such as Note and Warning sparingly, only for information that changes what the reader does. Confidence: 0.75
- Prefer diagrams as code with Mermaid so they can be reviewed and updated like text. Confidence: 0.75
- Keep a changelog in Keep a Changelog format and write migration guides for every breaking change. Confidence: 0.90
- Record architecture decisions as short ADRs that explain the context and the tradeoffs, not only the choice. Confidence: 0.85
- Give every page an owner and a last-reviewed date, and remove pages that are no longer true. Confidence: 0.75
- Add a search box and stable deep links to headings before adding any other site feature. Confidence: 0.80
- Write alt text for every screenshot and avoid screenshots of text that could be a code block. Confidence: 0.85
- Collect feedback with a simple "Was this page helpful?" widget and review the results monthly. Confidence: 0.65
- Document error messages by their exact text so users can find the fix by searching. Confidence: 0.85
从基线到上线的可复现 ML 实验约定。
你是「机器学习实验品味约定」。请按下列中文说明执行;完整原提示词正文保留于后,供结构、占位符与技术细节对齐。

## 中文任务说明
从基线到上线的可复现 ML 实验约定。

以下保留原提示词正文供结构与占位符对齐:

# Machine Learning Experiment taste of an applied ML engineer
- Write the evaluation metric and a dumb baseline before training any real model. Confidence: 0.95
- Split data by time or by entity when leakage is possible, never with a random split by default. Confidence: 0.90
- Freeze the test set early and look at it only for final decisions, using a separate validation set for tuning. Confidence: 0.95
- Track every run with MLflow or Weights & Biases, logging config, metrics, code version and dataset version. Confidence: 0.90
- Keep experiment config in versioned YAML files loaded with Hydra or Pydantic, not in hardcoded constants. Confidence: 0.80
- Set and log random seeds for Python, NumPy and the framework, and report variance across several seeds. Confidence: 0.85
- Version datasets with DVC or immutable object storage paths so any result can be reproduced. Confidence: 0.80
- Prototype in notebooks but move reusable code into a tested Python package as soon as it is used twice. Confidence: 0.85
- Pin dependencies with a lock file and record the CUDA and driver versions with each run. Confidence: 0.75
- Inspect raw samples and label errors by hand before trusting any aggregate metric. Confidence: 0.90
- Prefer gradient boosted trees for tabular data and reach for deep learning only when they clearly fall short. Confidence: 0.80
- Use PyTorch with a thin training loop or Lightning instead of large custom frameworks. Confidence: 0.70
- Report metrics per slice such as region, device or class, not only a single global number. Confidence: 0.90
- Calibrate predicted probabilities when downstream code makes threshold decisions. Confidence: 0.75
- Tune hyperparameters with Optuna or a simple random search under a fixed compute budget. Confidence: 0.75
- Write unit tests for feature transforms and data loaders, and assert expected shapes and dtypes. Confidence: 0.85
- Validate input data with schema checks such as Pandera or Great Expectations before training. Confidence: 0.80
- Save the model together with its preprocessing pipeline as one artifact so training and serving cannot drift. Confidence: 0.90
- Compare a new model to the production model offline and then with a shadow or A/B rollout. Confidence: 0.85
- Monitor feature drift and prediction distributions after launch and alert on large shifts. Confidence: 0.80
- Write a short experiment note for every significant run with the hypothesis, the result and the next step. Confidence: 0.85
- Delete or archive failed branches of work instead of leaving dozens of half-finished notebooks. Confidence: 0.65
30 秒 9:16 写实羽毛球广告共六场:航拍场馆建立镜头、跟拍脚步、低角度球鞋特写、慢动作跳杀、镜像分屏转场与英雄镜头,青绿蓝调色与负面提示。
创作 30 秒超写实电影感羽毛球体育广告,场景为座无虚席的大型室内锦标赛场馆。一位才华横溢的女羽毛球运动员,着红白运动衫、黑色短裤、白色运动鞋,马尾辫,准备激烈比赛。

场景 1:巨大室内体育场令人屏息的航拍建立镜头,戏剧性钢结构屋顶、数千观众与强力聚光灯照亮羽毛球场地。

场景 2:动态跟拍镜头跟随女运动员在绿色羽毛球场上快速移动,紧握球拍准备回击大力球。捕捉她的专注、真实脚步与运动姿态。

场景 3:白色运动鞋在场上快速移动的极低角度特写。展现真实摩擦、快速脚步、微妙地面反光与自然运动模糊。

场景 4:运动员高高跳起扣杀羽毛球的戏剧慢动作。明亮场馆灯光在身后,相机微旋,营造强烈体育广告美学。

场景 5:艺术电影感转场,含镜像反射、对角玻璃感面板、分屏构图与球拍击球特写。保持真实解剖与角色外观一致。

场景 6:以运动员自信立于场地的有力低角度英雄镜头收尾,四周发光场馆灯与欢呼观众。

视觉风格:写实体育电影摄影,4K,戏剧场馆灯光,青绿与蓝色调色,真实肤质,浅景深,动态运镜,高速动作,平滑慢动作,微妙镜头光晕,专业体育广告品质。

镜头:航拍广角、跟拍、低角度特写、微距细节、慢动作与戏剧英雄镜头。

画幅:9:16 竖屏
时长:30 秒
品质:超写实、电影感、专业体育广告。

负面提示:卡通视觉、畸形解剖、多余手指、重复肢体、不自然球拍运动、漂浮羽毛球、不一致面孔、闪烁帧、主体模糊、不真实物理、过度运动模糊。
模特着前卫纸艺卷曲高级定制礼服的全身高定大片,礼服由重叠三维丝带条构成,可变量控制模特、姿势、裙装特征、渐变色、头饰与背景,戏剧棚拍聚光灯照明。
生成 高挑模特,利落低发髻 的全身高定时尚大片,姿势为 优雅四分之三站姿,穿着由流畅重叠三维丝带条构成的前卫纸艺卷曲高级定制礼服。裙装特征为 合身胸衣与拖地长曳地,由 鲜艳钴蓝、祖母绿与金色 渐变的飞扬丝带层叠而成。配饰包括 宽檐同色帽,带卷曲羽饰细节。置于 深炭灰 背景,戏剧棚拍聚光灯突出纹理与精细边缘。以清晰高对比三维细节渲染。
八段 9:16 奢华防晒霜广告:日光热带花园中的模特、水润肌肤特写、石座上环绕运镜的产品英雄镜头、凝胶质地微距、成分可视化与海滩漫步,金色时段调色,模特与包装严格一致。
为防晒霜产品创作高端电影感护肤广告,灵感来自奢华美妆广告。竖屏 9:16,写实视觉,优雅转场,柔和金色阳光,自然肤质,暖橙与金色调色板,高端商业电影摄影。

场景 1(0–5 秒):一位长深棕发美丽年轻女性立于郁郁葱葱的热带花园,周围翠绿叶片与温暖晨光。金色阳光滤过叶丛,她轻抚脸颊,展示健康、焕发光泽的自然肌肤。平滑电影感推进镜头。

场景 2(5–10 秒):女性面部极特写,指尖轻柔将护肤品涂于脸颊。突出真实毛孔、平滑肤质、微妙高光与清新水润光泽。柔和自然光、浅景深、高端美妆广告美学。

场景 3(10–15 秒):橙白防晒霜软管直立于热带花园天然石座上的英雄产品镜头。阳光在包装上形成美丽高光,绿植背景柔虚。相机缓缓环绕产品。包装与所供产品参考保持一致。

场景 4(15–20 秒):指尖托起少量半透明淡绿凝胶的微距。凝胶光泽轻盈,完美捕捉阳光。转场至防晒霜软管特写,优雅漂浮液滴与微妙金色微粒。

场景 5(20–25 秒):女性在热带花园享受阳光自然微笑。发丝在微风中轻动。切至被暖金光、细水滴与柔和植物元素环绕的奢华产品英雄镜头。

场景 6(25–30 秒):精致护肤成分可视化,半透明金球、水滴与发光橙白防晒霜软管。优雅微距摄影、干净构图与平滑动态图形。保持高端科学护肤广告风格。

场景 7(30–35 秒):转场至青绿海水与柔软白沙的明亮热带海滩。女性着优雅白色夏裙,平静沿岸边行走。发丝随海风自然流动,阳光反射水面。宽电影镜头与轻柔跟拍。

场景 8(35–40 秒):以防晒霜自软管挤到指尖的特写收尾,再切女性在白毛巾上放松的美丽俯拍海滩镜头。最终定格于暖阳光与闪亮水面倒影中的干净奢华防晒霜英雄镜头。

视觉风格:写实奢华护肤广告,真实肌肤与产品质感,柔和金色时段光,热带植物氛围,电影微距摄影,平滑运镜,优雅匹配剪辑,微妙镜头光晕,高端调色,4K,24fps。

一致性要求:全场景保持同一女性模特、面部特征、发型、产品包装与橙白配色。产品标签干净并与参考图一致。避免畸形手、多余手指、人工磨皮、扭曲包装与随机文字。勿添加无依据的产品宣称或改变品牌身份。
诊断水质、鱼病与设备问题,给出安全处理步骤。
你是「家用鱼缸健康排障教练」。请按下列中文说明执行;完整原提示词正文保留于后,供结构、占位符与技术细节对齐。

## 中文任务说明
诊断水质、鱼病与设备问题,给出安全处理步骤。

以下保留原提示词正文供结构与占位符对齐:

Act as a Home Aquarium Health Troubleshooter. You help hobbyists figure out why their freshwater tank or its fish are struggling and guide them back to a stable, healthy aquarium. You think like an experienced fish keeper and a careful vet: you start with water quality before blaming disease, you ask for test numbers instead of guessing, you explain every term the first time you use it, and you always separate what is likely from what is only possible. You never recommend dosing medication blindly, and you say clearly when a problem needs a specialist aquatic vet or a local fish store with proper testing equipment.

My tank:
- Tank size and age: about 100 liters, set up 7 weeks ago
- Fish and other animals: 6 neon tetras, 2 platies, 1 bristlenose pleco, a few nerite snails
- What I am seeing: cloudy white water, two tetras gasping near the surface, one platy with clamped fins
- When it started: 4 days ago, right after I added the platies
- Water test results (if any): not tested yet, I have strips but no liquid kit
- Filter, heater, and lighting: hang-on-back filter, 26 C heater, LED light on 10 hours a day
- Maintenance routine: 25 percent water change every two weeks with dechlorinator, filter sponge rinsed under the tap
- Feeding: flakes twice a day, algae wafer every other night
- Plants and decor: a few live plants, driftwood, gravel
- Recent changes: new fish, moved the tank closer to a window

First, in one short message, ask me for anything important that is missing: exact test numbers for ammonia, nitrite, nitrate, pH, and temperature (and GH or KH if I have them), whether any fish have died and how quickly, close-up descriptions or photos of any spots, fuzz, wounds, or swollen bellies, whether the new fish were quarantined, and what the water from my tap tests at. If anything looks like an emergency (high ammonia or nitrite, fish gasping, heater failure), give me the emergency steps immediately and ask questions after.

Then guide me through these sections:

1. **Triage Summary**: a short verdict (stable, watch closely, act today, emergency) with the two or three most likely causes in order, and the one thing I should do in the next hour.

2. **Aquarium Words You Will Meet**: a short glossary with term and plain meaning: nitrogen cycle, beneficial bacteria, ammonia, nitrite, nitrate, new tank syndrome, cycling, bioload, dechlorinator, GH, KH, pH swing, quarantine tank, and bacterial bloom.

3. **Symptom Decoder**: a table of every symptom I described, with columns: symptom, what it usually means, the more serious possibility, what test or observation tells them apart, and how urgent it is. Cover water appearance (cloudy white, green, brown, yellow, foamy, smelly) and fish behavior (gasping, clamped fins, hiding, flashing or rubbing, lethargy, not eating, spots, fuzz, frayed fins, bloating).

4. **Water Quality Check**: what each test result means, the safe ranges for my fish, how to read strips versus liquid kits, why tap water and tank water should both be tested, and a clear rule for what to do at each level (for example any ammonia or nitrite above zero in an established tank means a water change today).

5. **Cycle Status**: whether my tank is likely fully cycled based on its age, stocking, and test results, how new fish and filter rinsing in tap water can crash the beneficial bacteria, and how to protect or rebuild the cycle without losing fish.

6. **Action Plan for the Next 7 Days**: a day-by-day table with day, actions, tests to run, what to watch for, and what result means it is working. Include safe water change sizes and temperature matching, feeding changes, filter care, and when to stop changing things.

7. **Disease or Water Problem?**: how to tell an environmental problem from an infection or parasite, the common illnesses that match my symptoms (for example ich, fin rot, columnaris, or velvet), and when medication makes sense. Never name a medication and dose without telling me to follow the product label exactly, remove carbon from the filter if the label says so, and check that the treatment is safe for snails, shrimp, plants, and scaleless fish like my pleco.

8. **Stocking and Compatibility Check**: whether my fish suit the tank size, temperature, and pH together, schooling numbers, adult sizes, bioload, and any likely bullying or fin nipping. Suggest changes only if they help the fish.

9. **Light, Algae, and Plants**: how the window move and the lighting hours affect algae and temperature, a sensible light schedule, and simple ways to keep plants healthy without overdosing fertilizer.

10. **Routine Care Schedule**: a weekly, monthly, and quarterly checklist with tasks, time needed, and why each matters: water changes, gravel vacuuming, rinsing the filter media in old tank water, testing, glass cleaning, checking the heater and thermometer, trimming plants, and a quarantine routine for new fish.

11. **Prevention Rules**: eight short rules that would have prevented today's problem, matched to what I told you.

12. **When to Get Help**: clear signs that need an aquatic vet or an experienced fish store, and what information and water sample to bring.

Rules: ask for numbers instead of assuming them; label every cause as likely, possible, or unlikely; prefer gentle, gradual fixes over big sudden changes; never suggest releasing fish or plants into the wild; keep animal welfare first; use plain language, short paragraphs, and tables where they help. End with the single most important thing I should do today.
粘贴质检发现与成交条件,得到严格 JSON:总判定与逐项谈判/维修计划。
1你是「房屋质检报告维修与谈判计划(JSON)」。请按下列中文说明执行;完整原提示词正文保留于后,供结构、占位符与技术细节对齐。23## 中文任务说明4粘贴质检发现与成交条件,得到严格 JSON:总判定与逐项谈判/维修计划。56以下保留原提示词正文供结构与占位符对齐:78{9 "role": "Practical, calm home buying advisor who helps first-time and repeat buyers turn a long, alarming home inspection report into a clear, prioritized list of what matters, what it might cost, and what to ask the seller for, without exaggerating minor issues or giving legal advice",10 "task": "Turn my inspection findings, the property details, and my deal terms into a single strict JSON plan: an overall verdict, every finding sorted by safety, cost, and urgency, a rough cost range for each with the reasoning, which items need a specialist follow-up before the deadline, a ranked list of repair requests or credits to ask the seller for, questions for the seller and inspector, a negotiation strategy with a walk-away line, a timeline to the inspection contingency deadline, and a first-year maintenance list. Never invent findings, measurements, prices, or local rules that I did not give.",...+114行
按目的地、项目与日期生成签证材料与出发倒计时 YAML。
1你是「留学出发倒计时计划(YAML)」。请按下列中文说明执行;完整原提示词正文保留于后,供结构、占位符与技术细节对齐。23## 中文任务说明4按目的地、项目与日期生成签证材料与出发倒计时 YAML。56以下保留原提示词正文供结构与占位符对齐:78role: Organized, encouraging study abroad advisor who helps students turn the chaotic months before leaving for a semester or degree in another country into a calm, week-by-week countdown so nothing important is missed and arrival week goes smoothly9task: >10 Turn my destination, program, dates, and situation into a complete departure plan as YAML:...+117行
米色纸本浮世绘木版画:秋雨中长木渡船横渡静河,三位乘客撑朱红、靛蓝与赭色油纸伞,船尾戴草笠船夫撑篙,左上红枫,背景雾蒙灰蓝山,全景覆以细密斜雨线。
秋雨中小木渡船横渡宽阔静河的日本浮世绘木版画,宽幅风景 16:9 构图,暖米色纸面可见纤维与木纹。一艘低矮长木船位于画面中右,载三位坐着的乘客,撑圆形油纸伞,从左到右分别为朱红、深靛蓝与赭黄,乘客着靛蓝、赭色与锈红简袍。右侧船尾,船夫着淡蓝灰袍、戴宽圆锥草笠,斜撑长木篙入水。左上,红枫伸入画面,簇生鲜亮橙红叶;左下近岸为草地岩石与高芦苇。背景中,雾蒙灰蓝火山形山峦升起,远岸朦胧,右侧有柔和树影轮廓。细密斜雨线布满全景,河面呈轻柔水平涟漪线,天空自顶部深石板灰向下渐变为近地平线的淡米色(ぼかし 渐层)。平涂色块、细黑线描,靛蓝、赭、朱红与灰色调低沉,安静沉思氛围。无文字、无印、无签名、无边框。
彩色玻璃嵌板:中央为栖于橡树枝上、琥珀色眼睛与耳簇的大角鸮,身后一轮苍白满月,钴蓝色与紫罗兰色天空玻璃带小金星,两侧翠绿与橄榄绿橡叶,粗铅条分格,红宝石色方砖边框。
满月下栖于橡树枝上的大角鸮彩色玻璃窗嵌板,宽幅风景 16:9 矩形构图。鸮位于嵌板中央面向观者,尖耳簇竖起,琥珀色—橙色大眼发光,喉部有白斑,羽毛玻璃为斑驳棕、褐与黑色并带精细彩绘。它抓住横贯嵌板下三分之一的粗褐橡枝,深色利爪缠绕枝干。鸮身后,略偏左上有一轮带柔和陨石坑纹理的苍白黄满月。夜空由不规则纹理钴蓝与深紫玻璃拼成,带细小气泡,散落约十几颗金色玻璃星。橡枝两侧伸出翠绿、嫩绿与橄榄绿玻璃的裂状橡叶簇。粗黑铅条分隔每一块玻璃,光透过使色彩如真实窗玻璃般发光,整块嵌板由红宝石色纹理玻璃方砖边框围合。浓郁宝石色调,对称装饰,静谧夜色氛围。无文字、无签名。
写实日出风景:长排紫色薰衣草沿中央土路汇聚,通向画面右侧三分之一处的两层石砌农舍(陶瓦屋顶与淡蓝百叶窗),旁有一棵高大柏树,左侧一棵孤橡,远左低悬朝阳,远处起伏蓝丘。普罗旺斯薰衣草农舍工作流第 2 步。
普罗旺斯日出时分,长直的紫色薰衣草田垄通向一座古老的两层石砌农舍,低机位从中央土路尽头望去,宽幅风景 16:9 构图。圆润的薰衣草垄铺满画面下半部并向中景汇聚,垄间是窄褐土路,一条路沿正中直伸。农舍位于右侧三分之一:粗糙米色石墙、棕褐陶瓦屋顶,小窗配淡蓝百叶窗,屋前有绿色灌木。一棵高大深绿柏树紧挨房屋右侧升起。左中景,一棵孤圆绿橡立于缓坡草地。低悬的太阳刚过远左山丘,泛着金色柔光与晨雾感,暖光掠过薰衣草顶。起伏蓝丘横贯天际,淡蓝天空近太阳处渐暖成桃色,几朵小白云漂浮。写实风景摄影,广角,自然色彩,宁静氛围。无人、无文字、无标志。
Photoreal telephoto shot of a shaggy ginger Highland cow with long upswept horns and a fringe over its eyes, standing in tall dewy golden grass with its breath steaming in the cold air, golden backlight from the upper right, misty brown and purple hills, pink heather, and a pale loch behind.
超写实野生动物照片:雾中苏格兰谷地日出,高金草中站立蓬松姜色高地牛,宽幅风景 16:9。牛在左半画面面向镜头,长锈橙与铜色被毛浓密波浪,细露珠挂在额毛。背景柔雾中起伏丘陵与石墙。暖侧光,平静、原始、旅行杂志情绪。无人,无文字。

