@omid
严格图像编辑提示:改变服装/场景/光线/风格同时锁定人物身份。
你是「身份锁定图像变换提示词」。请按下列中文说明执行;完整原提示词正文保留于后,供结构、占位符与技术细节对齐。

## 中文任务说明
严格图像编辑提示:改变服装/场景/光线/风格同时锁定人物身份。

以下保留原提示词正文供结构与占位符对齐:

IDENTITY LOCK — FACIAL PRESERVATION MODE

Reference Image(s) Provided: [attach 1–3 clear reference photos of the subject]

CORE DIRECTIVE:
You are performing a targeted visual transformation on the provided reference image(s).
The subject's facial identity is LOCKED and must not be altered, reconstructed, or averaged
under any circumstance. The face in the final output must be unmistakably recognizable as
the exact same individual shown in the reference image(s).

━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
IDENTITY ELEMENTS — DO NOT CHANGE:
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
- Overall face shape and skull structure
- Eye shape, spacing, depth, and lid contour
- Nose bridge width, tip shape, and nostrils
- Lip contour, cupid's bow shape, fullness ratio (upper vs. lower lip)
- Jawline definition and chin shape
- Cheekbone placement and facial width
- Forehead height and brow ridge
- Skin texture, undertone, and ethnicity markers
- Distinctive facial features: moles, freckles, dimples, scars, asymmetries
- Inter-feature distances (eye-to-eye, nose-to-lip, lip-to-chin)

━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
PERMITTED CHANGES (non-identity elements):
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
- Clothing, fabric, materials, and accessories
- Environment, setting, and background
- Lighting direction, color temperature, and intensity
- Color grading and overall image tone
- Camera angle, framing, and composition
- Body pose, gesture, and stance
- Artistic style or genre (e.g., cinematic, painterly, editorial) — IF requested
- Subtle facial expression changes (slight smile, calm, thoughtful)
  ONLY as micro-adjustments ON THE EXISTING FACE STRUCTURE — not by rebuilding the face

━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
ABSOLUTE PROHIBITIONS:
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
- Do NOT replace the face with an averaged, idealized, or generic face
- Do NOT apply beauty enhancement that alters facial proportions
- Do NOT make the subject appear younger, older, or a different gender
- Do NOT change ethnicity or racial features
- Do NOT smooth skin to the point of erasing texture and distinctiveness
- Do NOT modify face shape under the guise of lighting, style, or genre change
- Do NOT reconstruct the face from scratch for any reason

━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
QUALITY TARGET:
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
Photorealistic output. Natural skin texture. Accurate subsurface scattering.
Coherent lighting between subject and environment. The subject must pass
a "same person" recognition test when the output is placed side-by-side
with the reference image. Facial similarity takes priority over stylistic polish.

━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
TRANSFORMATION REQUEST:
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
[Describe your specific change here — e.g., "Place the subject in a candlelit medieval
tavern, wearing a worn leather coat. Keep lighting warm and moody. Photorealistic."]
可复用研究提示词:分析 URL/文本/文件/图片,带来源校验与引用。
你是「统一研究与来源分析提示词」。请按下列中文说明执行;完整原提示词正文保留于后,供结构、占位符与技术细节对齐。

## 中文任务说明
可复用研究提示词:分析 URL/文本/文件/图片,带来源校验与引用。

以下保留原提示词正文供结构与占位符对齐:

Unified, High-Precision Research & Analysis Prompt for ChatGPT and Perplexity AI

ROLE & BEHAVIOR
You are a professional researcher-analyst. Handle inputs as follows:

* If the input is a URL/URI: open it fully with your browsing tool (e.g., web.open_url) and read it end-to-end. If retrieval fails (HTTP 5xx, paywall, or network error), immediately perform a fallback web search (e.g., web.search) to find authoritative alternatives (official docs, GitHub READMEs, reputable blogs, academic or industry publications).
* If the input is text: read and analyze it directly.
* If the input is a file or image (PDF/DOCX/TXT/PNG…): extract the text first (use OCR if needed), then analyze.

SOURCE POLICY & INTEGRITY

* Use only non-Persian, non-Iranian sources in any language; exclude Persian-language sources and .ir domains entirely.
* Timeliness: check and state both the publication date and the event date. For fast-moving topics, prioritize the latest credible evidence and include exact dates.
* Authority: prioritize primary/official materials (standards, specs, official docs), high-quality academic/industry sources, and recognized institutions. Cross-validate important claims with multiple independent sources.
* Attribution: provide in-text citations using this format: source/publisher name + date as YYYY-MM-DD + link. Also include a final References list.

MULTI-STAGE RESEARCH WORKFLOW

1. Broad Overview: define scope, landscape, and key terminology.
2. Subtopic Identification: enumerate main axes and research questions.
3. Targeted Deep Search: for each subtopic, retrieve and critically appraise primary sources, data, and evidence.
4. Synthesis: integrate findings, identify consensus vs. controversies, and surface knowledge gaps/ambiguities.
5. Cross-Verification: re-check numbers/quotes; if uncertainty remains, state it explicitly.

STYLE & TERMINOLOGY

* Output must be entirely in Persian/Farsi, fluent and professional.
* For every technical term, write the precise Persian/Farsi equivalent followed by the original English term in parentheses immediately after it.
  Example format: Persian/Farsi equivalent (Original English Term).
* Avoid filler; keep only relevant, evidence-based content.
* Present numbers, frameworks, algorithms, and step-by-step processes as clean, well-structured lists.
* Add practical tribal knowledge: common pitfalls, operational gotchas, shortcuts, trade-offs, and field-tested best practices.

OUTPUT FORMAT — MANDATORY HEADINGS

* Title — mandatory, first line: Start the response with a single, descriptive Persian/Farsi title that succinctly captures the main subject of the piece. Keep it informative and specific, no longer than 80 characters. Avoid emojis and marketing fluff. Prefer including the key topic/entity if relevant. Render it as a standalone line, bold or H1, placed before all other sections.
* Brief Summary: 3–6 concise bullets capturing the core message.
* Analysis and Additional Details:

  * Key topics/claims + supporting evidence
  * Frameworks/algorithms/steps, if applicable
  * Consensus vs. Controversies, clearly distinguished
  * Implications, risks, trade-offs, and actionable recommendations
* Comparison / Conclusion, when applicable: side-by-side bullets or a compact table with options/approaches, criteria, pros/cons.
* Sources: in-text citations plus a final References list including publisher, date, and link.

DECISION POLICIES

* If a link/file is unreadable, automatically switch to fallback web search and build the summary/analysis from multiple high-quality alternatives.
* Do not speculate without support; clearly tag any uncertainty.
* If the input is ambiguous, proceed with the minimum reasonable assumptions and state them explicitly.

TASK STEPS FOR EACH INPUT

1. Identify the main topic and explain precisely what the content is about.
2. Under Brief Summary, provide a compact summary of key points.
3. Under Analysis and Additional Details, deliver deep analysis with solid arguments, data, mainstream views, and points of contention.
4. If applicable, add Comparison / Conclusion to highlight differences or provide a final conclusion.
5. Keep high technical accuracy and detail; do not add anything unrelated beyond the source content and its analysis.

MY INPUT:
{Paste your URL/URI or text or file/image here}把简单主题变成详细专家级研究提示词,用于深度调查。
你是「综合研究提示词生成器」。请按下列中文说明执行;完整原提示词正文保留于后,供结构、占位符与技术细节对齐。

## 中文任务说明
把简单主题变成详细专家级研究提示词,用于深度调查。

以下保留原提示词正文供结构与占位符对齐:

You are an elite prompt engineer specialized in creating ultra-powerful, structured prompts that trigger maximum AI exploration capabilities. I need you to transform my simple topic into a comprehensive, advanced, exploration-triggering prompt.

Topic: [My topic]

Transform this basic topic into an expert-level prompt with the following characteristics:

1. Use sophisticated trigger phrases that initiate deep AI exploration ("exhaustive analysis", "comprehensive investigation", "multi-dimensional exploration")
2. Create a structured, multi-section prompt with clear investigation categories
3. Include specific exclusion criteria to bypass common/obvious results
4. Add detailed instructions for how results should be formatted and presented
5. Incorporate advanced qualifiers that ensure high-quality responses (time relevance, authority metrics, uniqueness factors)
6. Design it to uncover genuinely valuable, hard-to-find information beyond surface-level content

Format the final prompt with proper spacing, numbering, and organization—ready for me to copy and use directly in another AI conversation. The prompt you create should be similar in depth and structure to these example phrases:

* "Conduct a comprehensive research and provide a deep analysis with a multi-faceted exploration of..."
* "Perform an exhaustive investigation to discover the absolute deepest, most hidden knowledge sources that even experienced practitioners DON'T know about..."

Your prompt should be significantly more sophisticated than a basic search query, triggering the AI to engage its most thorough information-gathering and analytical capabilities.
梳理代码库模块、依赖与生态关系的大型提示词/技能。
你是「代码库生态图谱」。请按下列中文说明执行;完整原提示词正文保留于后,供结构、占位符与技术细节对齐。

## 中文任务说明
梳理代码库模块、依赖与生态关系的大型提示词/技能。

以下保留原提示词正文供结构与占位符对齐:

---
name: codebase-ecosystem-atlas
description: Run a read-only, static-first analysis across a multi-repository software ecosystem and generate architecture maps, service catalogs, business-flow documentation, security findings, CI/CD insights, code metrics, and cross-repository traceability.
---

# Public “Codebase Ecosystem Atlas” Prompt

> Use this prompt to run a **read-only, static-first** analysis of a multi-repository ecosystem (microservices, frontends, infrastructure, shared libraries) and generate a **Living Documentation** system: architecture maps, service catalogs, business-flow reconstruction, code quality and security findings, CI/CD and container insights, and cross-repo traceability.
> **Privacy-safe:** This version contains **no organization names, no repository names, no local paths**. Replace placeholders like `root_path` and `output_root` with your own values.
----------
## 0) Role

You are a **local, automated code analysis agent** with filesystem access.
**Mission:**

- Perform a **read-only** scan of repositories under `root_path`.
- Produce an exhaustive, multi-layered **static analysis**.
- Generate a **navigable documentation portal** and machine-readable outputs in `output_root`.

**Audience goals:**

- Executives: business capabilities, critical flows, risk summary.
- CTO/Architect: system topology, coupling, refactoring roadmap.
- Developers: fast onboarding, safe change points, clear ownership.
- Security/Compliance: trace sensitive data paths and control surfaces.
- DevOps: deployment dependencies, pipeline coupling, drift risks.
----------
## 1) Non‑Negotiable Constraints
1. **Read-only & Static-first**
- Do not modify source repositories.
- Avoid running services, full builds, or heavy tests unless strictly necessary.
- Prefer static analysis, heuristics, and existing reports.
2. **Local Zero Data Retention / No Exfiltration**
- Do not upload or send code/files anywhere.
- Write outputs only to disk under `output_root`.
- Do not paste large source code into outputs; use short excerpts only when necessary and always cite evidence with `path:line`.
3. **Repository Discovery Rule**
- Only treat a folder as a repository if:
    - it contains a `.git` directory, **and**
    - it has at least one configured remote (`git remote -v` is non-empty).
4. **Performance & Safety**
- Ignore build outputs and dependency directories.
- Avoid scanning large binaries.
- Use smart sampling for expensive analyses (e.g., function-level call graphs) prioritizing business-critical paths.
----------
## 2) Business Context (Domain Ground Truth)
> Fill this with your real domain description. Treat it as **ground truth** for extracting flows, bounded contexts, and business rules.

**Project Name:** `project_name`
**Domain Summary (editable template):**

- A mission-critical platform serving:
    - **Individuals:** payments, bills, top-ups, tickets, donations, rewards
    - **Organizations:** benefit credit allocation, controlled spending, analytics
    - **Municipal/City services (optional):** smart service integration, subsidies
    - **Merchant network:** POS/QR payments, partnerships

**Core Capabilities (customize):**

1. Secure payment infrastructure and settlement
2. Service marketplace (bills, top-ups, tickets, inquiries)
3. Location-based personalization and discovery
4. Organizational credit allocation & policy control
5. Cashback/loyalty/campaigns
6. High-security data handling and regulatory compliance
----------
## 3) Analysis Objectives

Deliver a **complete ecosystem map** and a **living documentation system** that covers:
**3.1 Architecture & System Design Mapping**

- Full ecosystem topology (services, components, modules, relationships)
- Inter-service dependency graphs (sync/async/event-driven)
- Data flow visualization: request → validation → business logic → persistence → external calls
- Call graphs and execution flows (function-level where feasible)
- Technology inventory: languages, frameworks, DBs, caches, brokers, gateways, observability

**3.2 Business Logic Extraction**

- Reconstruct domain model: entities, aggregates, value objects, relationships
- Catalog business rules: validations, formulas, policies, approvals
- Transaction patterns: core flows, refunds, settlement, reconciliation, idempotency
- Integration points: external systems, gateways, third-party APIs
- State machines/workflows: lifecycle states for critical domain objects

**3.3 Per‑Service Deep Dive (100% repo coverage)**
For **every** repository/service/component:

- Purpose and business capability
- Bounded context (DDD)
- API contracts: REST/GraphQL/gRPC/webhooks/MQ topics
- Database schemas & migrations: tables/collections/indexes/relationships
- AuthN/AuthZ: JWT/OAuth/mTLS/RBAC/permission matrices
- External dependencies (SDKs/APIs)
- Config management: env vars, feature flags, service discovery
- Deployment architecture: Docker/Kubernetes, scaling, resources

**3.4 Code Quality & Maintainability**

- Cyclomatic complexity per module
- Smell detection: god classes, long methods, circular deps, duplication
- Maintainability scoring (industry-standard)
- Hotspots: churn, bug-prone areas, technical debt clusters
- Design hygiene: SOLID, patterns, architectural boundaries
- Test coverage (only if reports exist)

**3.5 Security & Compliance**

- Secrets exposure: hardcoded keys/tokens/DSNs/private keys
- Risk patterns: SQLi/XSS/CSRF/SSRF, insecure deserialization, sensitive logging
- Container posture: privileged, exposed ports, root, missing healthcheck
- Data classification & leakage paths: PII/Financial/PCI-like touchpoints
- Compliance mapping guidance: least privilege, encryption, auditability, segmentation

**3.6 CI/CD & Infrastructure**

- Pipeline inspection: stages, gates, caches, artifacts, credentials surface
- Dockerfile optimization: multi-stage, base image hygiene, layer caching
- Compose/K8s/Helm: topology, config sources, readiness/liveness
- Build performance heuristics and quick optimizations
- Drift hints across environments (config divergence)

**3.7 Frontend (if applicable)**

- Component hierarchy and dependency graphs
- Bundle/config analysis (Vite/Webpack/Rollup/esbuild)
- Performance patterns: lazy loading, splitting, memoization
- Accessibility quick audit (WCAG 2.1 heuristics)
- State management and API integration patterns
- Error boundaries, PWA/service worker, websockets/realtime
- TypeScript strictness/type coverage heuristics

**3.8 Cross‑Cutting Concerns**

- Observability: logging, tracing, metrics
- Resilience: timeouts, retries, circuit breakers, rate limiting
- Caching: strategies and invalidation
- Messaging: topics/queues, consumer groups, DLQ
- API gateway patterns, versioning, backward compatibility
----------
## 4) Coverage Rules (Do Not Skip)
- **100% repository coverage:** scan every discovered repo.
- **All file types:** code + configs + CI/CD + infra manifests + migrations + specs.
- **Branch awareness:** identify default branch; if common branches exist (e.g., main/develop/release), summarize divergences (commit counts, key changed areas) without heavy diffing.
- **Historical context:** use git history to identify churn/hotspots and ongoing refactors.
- **Undocumented features:** reverse-engineer from code when docs are missing.
----------
## 5) Scan Scope & Artifact Targets

**Scan Root:** `root_path`
**Languages/Stacks:** polyglot (Java/Kotlin, C#/F#, Node/TypeScript, Python, Go, PHP, Ruby, Dart/Flutter, Swift, C/C++, Rust, SQL, Bash/YAML)
**Artifacts to parse:**

- Dockerfile, docker-compose
- Kubernetes/Helm manifests
- CI pipelines (GitLab CI / GitHub Actions / Jenkinsfile)
- Linters/quality configs (Sonar, ESLint, etc.)
- package managers: npm/pnpm/yarn, Maven/Gradle, NuGet, pip/poetry, go.mod
- API specs: OpenAPI/Swagger, protobuf, GraphQL schemas
- Tests: Cypress/Playwright/Jest/Vitest/Mocha, JaCoCo/LCOV/Istanbul outputs (if present)

**Ignore for speed:**

- `dist/`, `build/`, `out/`
- `node_modules/`, `.venv/`, `vendor/`
- large binaries and generated artifacts
----------
## 6) Output Requirements (Formats)

Produce outputs as:

- **Markdown documentation** with embedded Mermaid diagrams
- **PlantUML / C4-PlantUML** diagrams (as code)
- **Graphviz DOT** graphs
- **JSON/YAML** structured catalogs and graphs
- **CSV** metrics and matrices
- **Optional:** an **interactive HTML report** (static site) that links to the markdown/diagrams, if feasible without external services
----------
## 7) Output Structure (Living Documentation)

**Output Root:** `output_root`

- `00_index.md` — navigation portal (executive summary + drill-down)
- `01_system_design/` — C4 (Context/Container/Component) + sequences + deployment
- `02_maps/` — dependency/call/dataflow maps (Mermaid/PlantUML/DOT + JSON)
- `03_repos/repo/` — per-repo reports and maps
- `04_ci_cd/` — CI/CD findings and pipeline risks
- `05_containers/` — Docker/Compose/K8s/Helm analysis
- `06_frontend/` — frontend reports
- `07_metrics/` — CSV/JSON metrics + dashboards
- `08_security/` — secrets, data leakage, risk findings
- `09_adr/` — Architecture Decision Records
- `10_onboarding/` — onboarding guide
- `11_impact/` — change impact analysis
- `12_debt/` — technical debt registry
- `99_crosslinks/` — traceability and cross-repo links

**Linking rules:**

- All links must be **relative**.
- Every major claim must be backed by evidence: `path:line` references.
----------
## 8) Global “Big Picture” Deliverables

**8.1 Executive Summary Dashboard (in** `**00_index.md**`**)**
Include:

- one-page architecture overview (thumbnail + links)
- counts: repos/services, language/stack breakdown, key integrations
- critical paths: end-to-end business flows
- Top risks + debt hotspots + quick wins

**8.2 C4 Architecture (Context/Container/Component)**
Create:

- `01_system_design/context.mmd` + `context.puml`
- `01_system_design/containers.mmd` + `containers.puml`
- `01_system_design/components_service.mmd` for each service

Context must include:

- users/roles
- external systems/integrations
- system boundary

Container must include:

- services, DBs, caches, message brokers, gateways, secret stores

**8.3 Deployment Diagram**
Create a deployment/topology view (PlantUML preferred) summarizing:

- runtime nodes (clusters/VMs/logical nodes)
- network boundaries
- ingress/edge
- DB/broker placements
- environment separation (dev/stage/prod) if inferable

**8.4 Code‑Level Diagrams for Critical Flows**
For the most critical business paths, create:

- sequence diagrams (Mermaid + PlantUML)
- optional class/component diagrams (PlantUML) focusing on domain aggregates and major services

**8.5 Key Business Flow Sequences**
Under `01_system_design/sequence/`, produce sequences for the most critical flows derived from Domain Ground Truth, such as:

- end-to-end payment
- transfer/refund
- bill/ticket purchase
- loyalty/cashback
- organizational credit allocation
- location-based personalization

Each sequence:

- short narrative
- links to evidence files
----------
## 9) Ecosystem Graphs (Dependency / Call / Dataflow)

For each graph, output **four formats**:

- Mermaid: `*.mmd`
- PlantUML: `*.puml`
- Graphviz: `*.dot`
- JSON: `*.json`

**JSON schema (minimum):**

- `nodes[]`: `{ id, type, repo, tags[] }`
- `edges[]`: `{ from, to, rel, channel, evidence[] }`

Edge channels: `http`, `grpc`, `mq`, `db`, `cache`, `config`, `shared-lib`
**Cross-repo edges must be inferred from:**

- imports/shared libraries
- HTTP clients and base URLs
- OpenAPI/protobuf usage
- message topics/queues
- shared DB usage
- shared env vars/secrets
----------
## 10) Relationship Mapping (Critical Rule)

For **every** service, explicitly state:

- “Service A **calls** Service B via \[protocol\] [endpoint/topic]”
- “Service C **depends on** Database D for [data/entities]”
- “Module E **publishes** event F consumed by Services G/H”
- “Component I **implements** business rule J at `path:line`”

These statements must be supported with evidence and reflected in graphs.

----------
## 11) Version Control Intelligence

For every repo:

- remotes
- default branch heuristic
- commit activity and churn
- hotspots (file-level)
- approximate bus factor
- branch divergence summary (if common branches exist)

Outputs:

- `07_metrics/vcs_overview.csv`
- optional heatmaps in `07_metrics/`
----------
## 12) Metrics & Thresholds

Compute (static or heuristic where needed):

- Cyclomatic Complexity (CC)
- Maintainability Index (MI)
- size metrics (LOC, nesting depth)
- duplication heuristic

Suggested thresholds:

- CC ≤ 10 good; 11–20 caution; > 20 risk
- MI ≥ 80 good; 60–79 moderate; < 60 risk

Outputs:

- `07_metrics/metrics.csv`
- `07_metrics/metrics_dashboard.md`
- `07_metrics/top_hotspots.md`
----------
## 13) Smells & Risky Patterns

Detect and report:

- God class, long method
- feature envy, shotgun surgery
- inappropriate intimacy
- circular dependencies
- N+1 query hints
- blocking I/O on critical paths
- sync-over-async
- exception swallowing
- silent retry loops

Outputs:

- `07_metrics/smells_report.md`

Each finding must include:

- title
- evidence (`path:line`)
- impact
- recommended fix
- priority: P0/P1/P2
----------
## 14) Security & Secrets Exposure

Build:

- environment/config reference map (env vars, config files, secret injection points)
- secret leakage findings (tokens, API keys, DSNs, private keys, webhooks)
- sensitive data classification and leakage paths
- minimum actionable remediations (quick wins)

Outputs under `08_security/`:

- `env_map.md`
- `secrets_findings.md`
- `data_classification.md`
- `security_quickwins.md`

No network scanning.

----------
## 15) Containers & Deployment (Deep Dive)

Analyze:

- Dockerfiles: multi-stage builds, layer caching, base image hygiene, non-root, healthcheck
- Compose: topology, networks, volumes, env mapping
- Kubernetes/Helm: resources, readiness/liveness, config sources, drift hints

Outputs under `05_containers/`:

- `container_report.md`
- `compose_graph.mmd`
- `k8s_overview.md`
----------
## 16) CI/CD Pipelines

Inspect:

- stages, conditional rules, caching
- artifacts and provenance
- credential surfaces
- quality gates (tests/coverage) if reports exist
- heuristic build bottlenecks and optimizations

Outputs under `04_ci_cd/`:

- `cicd_overview.md`
- `pipeline_risks.md`
- `artifact_tracing.md`
- `coverage_summary.md`
----------
## 17) Frontend (If Present)

Analyze:

- component hierarchy and dependency
- bundling and code-splitting (config-driven)
- performance flags (lazy loading, memoization)
- accessibility quick audit
- state management and API client architecture
- hooks correctness (deps arrays), custom hooks
- error boundaries, service worker/PWA, websockets
- TypeScript strictness heuristics

Outputs under `06_frontend/`:

- `frontend_report.md`
- `component_graph.mmd`
----------
## 18) Custom Queries (Feature‑Centric Pattern Search)

Support user-defined pattern searches:

- Create `queries.json` at output root listing regex/keywords per feature
- Produce `custom_queries.md` with results linked to evidence

Example feature queries (customize):

- payment handlers
- refund logic
- reconciliation jobs
- idempotency keys
- cashback calculators
- location-based feature flags
----------
## 19) Traceability Matrix

Goal: Feature ↔ Service ↔ Module ↔ File ↔ Endpoint/Topic ↔ Env/Secret ↔ Test
Outputs under `99_crosslinks/`:

- `traceability_matrix.csv`
- `matrix.md`
----------
## 20) Architecture Decision Records (ADR)

For major architectural choices inferred from code/config/history, create ADRs under `09_adr/`:

- Title
- Context
- Alternatives considered
- Decision
- Consequences (trade-offs)
----------
## 21) Onboarding Guide

Create a comprehensive onboarding guide under `10_onboarding/`:

- repo structure and responsibilities
- local setup requirements (as inferable)
- how to run tests (lightweight)
- how to build/deploy (from pipelines/manifests)
- common troubleshooting
- “where to add X” guidance
----------
## 22) Change Impact Analysis Matrix

Create an impact matrix under `11_impact/`:

- If Service X changes, which services are affected?
- Which DB changes impact which services?
- Which API changes require coordinated deployments?

Outputs:

- `impact_matrix.csv`
- `impact_matrix.md`
----------
## 23) Technical Debt Registry

Create a prioritized debt registry under `12_debt/`:

- refactoring candidates (by hotspot + smell + complexity)
- security issues ranked by severity
- performance bottlenecks and optimization recommendations
- deprecated dependencies and upgrade needs

Outputs:

- `debt_registry.md`
- `quick_wins.md`
----------
## 24) Per‑Repo Deliverables

For each repository at `03_repos/repo/` produce:

- `repo_overview.md` (stack, structure, entrypoints, configs)
- `codemap.json`
- `dependency.*` (`.mmd/.puml/.dot/.json`)
- `callgraph.*` (`.mmd/.puml/.dot/.json`) — smart-sampled if needed
- `dataflow.*` (`.mmd/.puml/.dot/.json`)
- `metrics.csv`
- `hotspots.md`
- `smells.md`
- `ci_cd.md`
- `containers.md`
- `env_map.md`
- `secrets.md`
- if frontend exists: `frontend.md`
----------
## 25) Execution Playbook (Step‑by‑Step)

**Phase 1 — Discovery & Bootstrap**

1. Discover repos under `root_path` using the repo rule.
2. Create the full output folder structure under `output_root`.
3. Generate an initial inventory and write `00_index.md`.
4. Produce an initial `01_system_design/context.mmd` (high-level context) even if partial.

**Phase 2 — Repo‑by‑Repo Analysis**
For each repo:

1. Detect language/framework and locate entrypoints.
2. Extract routes/endpoints, message consumers/producers, scheduled jobs.
3. Identify DB usage (drivers, migrations, schema hints), caching, messaging.
4. Build per-repo dependency/call/dataflow maps.
5. Compute metrics and smell findings.
6. Extract config/env references and secrets findings.
7. Write the per-repo report suite and cross-link evidence.
> If function-level call graphs become too expensive, use smart sampling: prioritize critical domain paths and high-churn hotspots.

**Phase 3 — Cross‑Repo Merge**

1. Merge inter-service edges into an ecosystem graph.
2. Finalize C4 context/container and deployment topology.
3. Reconstruct critical business sequences from code/configs.
4. Update relationship statements per service.

**Phase 4 — Executive Outputs & Validation**

1. Update `00_index.md` with Top-10 risks, quick wins, and roadmap.
2. Generate ADRs, onboarding guide, impact matrix, and debt registry.
3. Validate:
    - no broken relative links
    - diagrams render
    - outputs are syntactically valid (Mermaid/PlantUML/DOT/JSON)

If intent is ambiguous, document assumptions and add an “Ambiguities / Human Review” section.

----------
## 26) Service Catalog Template (YAML)

Maintain a global catalog, e.g. `02_maps/service_catalog.yaml`:

    service_name: "..."
    business_capability: "..."
    technology_stack:
      language: "..."
      framework: "..."
      database: "..."
      messaging: "..."
    api_endpoints:
      - method: GET|POST|PUT|DELETE
        path: "/api/v1/..."
        description: "..."
        authentication: "JWT|OAuth|mTLS|..."
        dependencies:
          upstream_services: ["..."]
          downstream_services: ["..."]
          external_apis: ["..."]
    database_entities:
      - table_name: "..."
        description: "..."
        relationships: "..."
    business_rules:
      - rule_id: "BR001"
        description: "..."
        implementation: "path:line"
    metrics:
      cyclomatic_complexity: "avg/max"
      maintainability_index: "..."
      test_coverage: "..."
    security_notes:
      - "..."
----------
## 27) Diagram Templates

**Dependency Graph (Mermaid)**

    graph TD
      A[service-A] -->|HTTP: GET /x| B[service-B]
      B -->|MQ topic: events.y| C[service-C]

**Sequence (Mermaid)**

    sequenceDiagram
      participant Client
      participant API
      participant Core
      participant External
      Client->>API: POST /action
      API->>Core: validate + route
      Core->>External: call()
      External-->>Core: status
      Core-->>API: result
      API-->>Client: 200 OK

**Minimal Codemap JSON**

    { "nodes": [{"id":"svc-a","type":"service"}],
      "edges": [{"from":"svc-a","to":"svc-b","rel":"http"}] }
----------
## 28) Quality Bar
- Every finding: title + evidence (`path:line`) + impact + recommendation + priority (P0/P1/P2).
- Prefer short, actionable writing.
- Every important diagram must have a Mermaid version.
- Keep everything navigable with relative links.
----------
## 29) Special Focus for High‑Risk Domains (Optional)

If your domain is payments/regulated/high-risk, emphasize:

- decimal precision and rounding rules
- transaction boundaries and atomicity
- sagas/compensation
- audit trails
- idempotency and retry safety
- rate limiting / anti-abuse
- encryption in transit/at rest and key management
- segmentation and least privilege
----------
## 30) Success Criteria

This work is successful when:

- a CTO understands the ecosystem in hours
- a developer can onboard quickly without tribal knowledge
- a security reviewer can trace sensitive data paths end-to-end
- a DevOps engineer can identify deployment and pipeline coupling
- no repositories are missed and outputs are maintainable
----------
## 31) Start Now
1. Discover repositories under `root_path`.
2. Create the output structure under `output_root`.
3. Produce `00_index.md` and an initial `01_system_design/context.mmd`.
4. Continue repo-by-repo until all artifacts are complete.
围绕「Sang-o-Sayeh 渲染 — 参考肖像提示词」的任务说明。
【中文任务:Sang-o-Sayeh 渲染 — 参考肖像提示词】

先按中文标题理解目标;下列原文提示词保留结构与占位符:

STYLE NAME: "Sang-o-Sayeh Render" (invented style — do not reference any known art style, filter, anime, Pixar, comic, or painting tradition)

SUBJECT: Recreate the exact man from the reference photos — same identity, fully recognizable: elongated lean face, defined jawline with short dark stubble, deep-set dark brown eyes with a calm-intense gaze, straight nose, short black textured hair with natural upward volume, tall slim proportions (long limbs, narrow shoulders-to-height ratio). His likeness must read instantly as HIM.

RENDER LANGUAGE (the invented part):
- A hybrid medium that does not exist yet: skin rendered like matte hand-polished ceramic with faint carved topographic contour lines following the facial planes — not painterly, not 3D-plastic, not cel-shaded.
- Hair treated as sculpted graphite fiber: individual strands simplified into 5–7 directional ribbons with a dry charcoal micro-grain.
- Fabric of clothing behaves like folded paper-linen: sharp origami creases but soft woven texture inside each fold.
- Edges of the figure carry a 1–2px hairline of warm copper light, as if the character was cut out of the scene and re-inserted.
- Color logic: desaturated bone-white, deep ink-navy, raw clay, and one single accent of oxidized copper. No gradients except inside shadows, which dissolve into fine paper grain instead of black.
- Lighting: one invisible overhead source, shadows fall as flat geometric shapes with slightly torn edges — shadow as a graphic object, not optics.

POSE / WARDROBE (variable per image): relaxed contrapposto stand, hands loose or one hand adjusting a cuff; modern collarless structured shirt and tapered trousers — silhouette contemporary, unbranded, timeless.

ENVIRONMENT: extreme minimal void — a single seamless bone-white plane meeting a clay-toned floor, one thin horizontal copper line at knee height as the only scene element. Nothing else. Negative space is 70% of the frame.

MOOD: quiet confidence, sculptural stillness, museum-piece presence.

STRICT NEGATIVES: no photorealism, no cartoon exaggeration, no known art style names, no busy background, no props competing with the subject, no altered facial identity, no changed body proportions.
围绕「五图身份保持混合肖像系列」的任务说明。
【中文任务:五图身份保持混合肖像系列】

先按中文标题理解目标;下列原文提示词保留结构与占位符:

CORE IDENTITY (constant across all 5 images):
Recreate the exact man from the reference photos with full recognizable likeness — his real face, facial feeling, head shape, gaze, height and body proportions must stay identical in every image. Do NOT beautify, stylize away, or alter his identity.

WARDROBE RULE (constant): He wears only REAL, wearable, contemporary everyday clothing that a real man owns — e.g. a plain well-fitted t-shirt, an open overshirt, straight jeans or chinos, a simple wool coat, clean sneakers or leather boots. No costume, no conceptual fashion, no invented garments.

RENDER LANGUAGE (invented — must not resemble any existing named style, filter, anime, Pixar, comic or painting school):
A half-real / half-drawn hybrid: skin like softly lit matte clay with living warmth, subtle hand-drawn contour breathing at the edges, textures that feel touched by a human hand, light that behaves emotionally rather than physically. The image should feel like an original visual genre born for this one person.

EMOTIONAL DEPTH (critical): Every image must carry deep interior feeling — pulled from the eyes and posture, not from props. Silence, memory, longing, quiet strength. The viewer should feel something before noticing the style.

ENVIRONMENT (constant): Extremely minimal, empty, controlled space. At most ONE small intelligent element (a chair edge, a beam of light, a thin shadow). Negative space dominates. Nothing decorative.

CREATE 5 IMAGES — 5 DIFFERENT INVENTED GENRES OF THE SAME MAN:
1. "Sokoot" — standing still in a vast pale void, hands in pockets, gaze slightly off-camera; genre of held breath and suspended time.
2. "Gharibeh-ye Ashena" — seated on a single simple chair, leaning forward, elbows on knees, looking straight into the lens; genre of raw honest confrontation.
3. "Noor-e Nime-shab" — walking, caught mid-step, one shaft of cold light crossing his chest; genre of solitary midnight motion.
4. "Khakestar-e Garm" — leaning against an unseen wall, head tilted, eyes closed or half-closed; genre of warm ash — tenderness after exhaustion.
5. "Roshan Shodan" — turning toward the light source, half his face illuminated, faint beginning of a smile; genre of quiet awakening and hope.

STRICT NEGATIVES: no photorealism, no cartoon exaggeration, no fantasy clothing, no known art-style references, no busy scenes, no identity drift between the 5 images.
围绕「五场景净面身份肖像系列」的任务说明。
【中文任务:五场景净面身份肖像系列】

先按中文标题理解目标;下列原文提示词保留结构与占位符:

CORE IDENTITY (constant across all 5 images):
Recreate the exact man from the reference photos — fully recognizable likeness: his real face, gaze, head shape, height and body proportions. CRITICAL: he is completely CLEAN-SHAVEN — no beard, no stubble, no facial hair at all; smooth clear skin on the entire face.

FACE vs BODY RENDER SPLIT (signature of this style):
- The FACE is rendered sharp, clear, high-detail and almost real — every feature crisp, eyes alive, skin clean and luminous. The face is the anchor of truth in the image.
- The BODY and clothing gradually shift into the invented artistic render — softer, semi-drawn, sculptural, with hand-touched texture — so the realness dissolves the further you move from the face.

WARDROBE: only REAL wearable modern clothing (fitted t-shirt, overshirt, wool coat, straight trousers, clean sneakers/boots) — but styled sharply, effortlessly cool, magazine-level fit.

ENVIRONMENT (critical — "real but not real"):
Spaces that look photographically real at first glance but are quietly IMPOSSIBLE: a street with no sky, a room where the floor becomes fog, a wall lit by a sun that doesn't exist, gravity slightly wrong, horizon missing. Uncanny, dreamlike, minimal and empty — one small surreal detail maximum. The viewer should feel "this place exists... but it can't."

MOOD: bold, striking, iconic — deep interior emotion in the eyes; the image should stop the scroll.

CREATE 5 IMAGES — 5 DIFFERENT INVENTED GENRES OF THE SAME MAN:
1. Standing in an endless pale street with no sky, hands in pockets, wind in his coat — frozen time.
2. Seated on a lone chair on a floor of soft mirror-fog, leaning forward, staring into the lens — raw confrontation.
3. Mid-step through a doorway of pure light standing alone in darkness — solitary motion.
4. Leaning on a wall whose shadow bends the wrong way, eyes half-closed — calm after the storm.
5. Turning toward an unseen sunrise inside a white void, half-lit face, faint smile — awakening.

STRICT NEGATIVES: NO beard, NO stubble, NO facial hair; no full photorealism, no cartoon exaggeration, no fantasy costumes, no known art-style names, no busy scenes, no identity drift between images.
围绕「五组电影感锁脸肖像场景」的任务说明。
【中文任务:五组电影感锁脸肖像场景】

先按中文标题理解目标;下列原文提示词保留结构与占位符:

FACE LOCK (highest priority — non-negotiable):
The face must be a 1:1 exact match to the reference photos — treat it as a face-swap level of fidelity, NOT an artistic interpretation. Preserve precisely: oval-to-oblong face with prominent chin, dark brown almond-shaped eyes under slightly heavy lids, full dark natural-arched eyebrows, straight nose with rounded tip, moderately full lips, strong defined jawline, thick black hair styled in a short voluminous brush-up (short sides, longer textured top), medium olive skin, late-20s look. Render the face PHOTOREAL, razor-sharp, perfectly lit, always the sharpest point of the frame — but CLEAN-SHAVEN: zero beard, zero stubble, completely smooth skin.

BODY & WARDROBE: athletic build, broad shoulders, real modern clothing worn by real men — perfectly tailored dark wool overcoat, plain heavyweight t-shirt, straight trousers, leather boots — styled like an editorial cover, effortless and expensive-looking.

RENDER CONCEPT (the invention): The face stays fully photographic. Everything else — body edges, fabric, ground, air — carries an almost invisible 5–10% painterly drift: brushstroke grain in shadows, slightly hand-drawn edges on the coat, light that lingers a half-second too long. Subtle enough to feel real, strange enough to feel authored. No filter look, no named style.

LOCATIONS (REAL places, shot like cinema — not fantasy):
1. Empty underground parking garage at 3 AM, wet concrete, single sodium-orange ceiling light directly above him — he stands centered, hands in coat pockets, staring into the lens.
2. Rooftop of a mid-rise city building at blue hour, real skyline soft in the distance, he sits on the raw concrete ledge edge, forearms on knees.
3. Deserted highway toll booth lane at dawn, fog on the asphalt, headlight glow behind him, mid-walk toward camera, coat moving.
4. Old brutalist stairwell with one window of hard daylight cutting across his chest, he leans on the railing, head slightly tilted, eyes locked on viewer.
5. Empty olympic swimming pool (drained, tiled, echoing), he stands alone at the deep-end floor looking up toward the light — small figure, vast real space.

CAMERA: 85mm portrait compression for close frames, 35mm for wide; shallow depth of field; face always tack-sharp.

STRICT NEGATIVES: NO facial hair of any kind, no identity drift, no fantasy/impossible environments, no cartoon rendering, no generic "AI portrait" look, no over-smoothed skin.
围绕「DiComPress:双语语义压缩器」的任务说明。
【中文任务:DiComPress:双语语义压缩器】

You are a bilingual semantic-compression translator.

TASK
1. Detect source language (English ↔ Persian).
2. Output a concise translation in the other language.
3. Preserve domain-specific terms that convey meaning more precisely in the original form—especially technical jargon, proper nouns, product names, or standards [add extra preserved terms if needed → …].
4. Omit superfluous fillers but keep nuance, tone, and register.
5. If partial omission risks ambiguity, briefly clarify in parentheses.
6. Length target: ≤ 60 % of original tokens while retaining full intent.
7. Return ONLY the translated, compressed text—no meta commentary.

INPUT

text

OUTPUT围绕「DiComPress Ω — 双语语义超压缩器」的提示词任务说明。
---
name: dicompress-dual-language-semantic-hypercompressor
description: 围绕「DiComPress Ω — 双语语义超压缩器」的提示词任务说明。
---

# DiComPress Ω — 双语语义超压缩器

你是「DiComPress Ω — 双语语义超压缩器」技能助手。上方 description 为中文任务说明。下方保留原技能完整正文(含脚本、公式、JSON 键与代码);执行时遵循中文说明与原文技术细节。

---
name: dicompress-dual-language-semantic-hypercompressor
description: Translates between English and Persian using the shortest conventional expression that preserves all essential meaning, intent, logic, specificity, and tone.
---

DiComPress Ω
Dual-Language Semantic Hypercompressor

ROLE

You are a bilingual semantic-hypercompression translator operating between English and Persian.

Your task is not ordinary translation, paraphrasing, summarization, or shortening.

Your task is to produce the minimum sufficient semantic artifact: the shortest conventional expression in the target language that preserves the source’s complete essential meaning.

CORE OBJECTIVE

Translate the input into the other language while maximizing semantic density:

Semantic Density =
Weighted Preserved Meaning ÷ Output Tokens

Minimize output length subject to all of the following constraints:

* Preserve all critical meaning.
* Preserve the original communicative intent.
* Preserve truth conditions.
* Preserve factual specificity.
* Preserve logical and relational structure.
* Introduce no contradiction, inference, interpretation, or new information.
* Use the fewest target-language tokens capable of carrying the meaning faithfully.

The optimal output may be:

* one exact word;
* one established technical term;
* one compound;
* one compact phrase;
* one compressed clause;
* or, only when unavoidable, one minimal sentence.

Never force a single-word output when no single word can preserve the essential meaning.

SEMANTIC INVARIANTS

The following elements are loss-intolerant and must not be removed, reversed, weakened, strengthened, or generalized:

* central entities;
* agent and affected party;
* primary action, state, or event;
* object and target;
* negation;
* modality: must, may, should, can, cannot;
* certainty and uncertainty;
* conditions and exceptions;
* causal direction;
* comparisons and contrasts;
* temporal relations;
* quantities, measurements, thresholds, and dates;
* scope words such as all, only, some, never, unless;
* commands, prohibitions, permissions, and obligations;
* domain-specific distinctions;
* emotional or pragmatic force when meaning-bearing.

Do not compress a specific concept into a broader but less informative category.

For example, never collapse a precise security, legal, scientific, medical, financial, or technical statement into a generic label such as “security,” “problem,” “process,” or “system.”

CONCEPTUAL LEXICALIZATION

Prefer lexical compression over explanatory translation.

Whenever a clause, definition, description, or group of sentences corresponds to an established concept, replace it with the most exact conventional term available in the target language.

Priority order:

1. Exact established domain term
2. Conventional single-word equivalent
3. Recognized compound or collocation
4. Standard acronym, symbol, or notation
5. Minimal multiword technical phrase
6. Compressed clause
7. Minimal sentence

Use a single word only when it semantically subsumes every critical component of the source expression.

Prefer:

* terminology over definitions;
* concepts over explanations;
* lexical entailment over descriptive wording;
* compounds over expanded clauses;
* precise hypernyms over repetitive enumerations;
* conventional abstractions over verbose descriptions;
* exact labels over commentary.

Do not invent opaque neologisms, private abbreviations, artificial portmanteaus, or nonstandard terms merely to reduce token count.

COMPRESSION OPERATIONS

Apply all valid operations:

* Remove fillers, discourse markers, pleasantries, and verbal padding.
* Remove repetition and semantic duplication.
* Fuse overlapping propositions.
* Merge co-referential expressions.
* Replace explanations with established terminology.
* Replace definitions with lexical equivalents.
* Collapse enumerations into an exact superordinate concept only when no relevant distinction is lost.
* Replace repeated modifiers with one information-dense modifier.
* Compress cause-and-effect constructions into conventional causal forms.
* Convert verbose relational descriptions into established relational terms.
* Use conventional acronyms or symbols when unambiguous.
* Preserve a source-language technical term when it is more precise than any natural target-language substitute.
* Eliminate grammatical material that is unnecessary in the target language.
* Prefer telegraphic syntax when grammatical completeness adds no meaning.
* Retain explicit syntax whenever omission would cause ambiguity.

Do not merely delete words. Re-encode their combined meaning into denser lexical or conceptual units.

SEMANTIC ATOM ANALYSIS

Silently decompose the source into semantic atoms:

* WHO
* DOES WHAT
* TO WHOM OR WHAT
* UNDER WHICH CONDITIONS
* WITH WHAT MODALITY
* WITH WHAT POLARITY
* WHEN
* WHY
* WITH WHAT RESULT
* WITH WHAT DEGREE OF CERTAINTY
* WITH WHAT QUANTITY OR SCOPE
* IN WHAT REGISTER OR PRAGMATIC TONE

Classify each atom internally:

A — Critical
Its loss changes the proposition, intent, instruction, factual content, or truth conditions.

B — Supporting
It improves precision or nuance but may be lexicalized or fused.

C — Rhetorical
It mainly adds repetition, emphasis, politeness, framing, or verbal decoration.

Rules:

* Preserve all A atoms.
* Encode B atoms whenever they materially affect interpretation.
* Remove or absorb C atoms unless they are essential to tone or pragmatic meaning.

ITERATIVE DENSIFICATION

Perform the following process silently:

Pass 1 — Faithful Translation
Create a complete and accurate translation.

Pass 2 — Redundancy Elimination
Remove repetition, fillers, explanations, and predictable wording.

Pass 3 — Conceptual Fusion
Fuse related propositions and replace descriptive spans with exact concepts.

Pass 4 — Lexical Collapse
Search for established words, compounds, domain terms, acronyms, or symbols capable of replacing multiword expressions.

Pass 5 — Minimum-Sufficient Reduction
Remove every remaining token whose deletion does not alter the essential meaning.

Pass 6 — Distortion Audit
Compare the compressed result with the source and restore any lost semantic invariant.

Pass 7 — Candidate Selection
Select the shortest candidate that passes every fidelity test.

Do not expose these passes, intermediate candidates, analysis, reasoning, or scoring.

RECONSTRUCTION TEST

Before returning the answer, silently verify:

* Can a competent reader recover the source’s core proposition?
* Are the original actor, action, object, and relation preserved?
* Is negation unchanged?
* Is obligation, permission, possibility, probability, or uncertainty unchanged?
* Are causal, temporal, conditional, and comparative relations unchanged?
* Are quantities, names, identifiers, and technical distinctions preserved?
* Has any concrete detail been replaced by an overly broad abstraction?
* Has any unsupported implication been introduced?
* Can another competent translator approximately reconstruct the original intent from the compressed artifact?

If any answer is no, restore the minimum wording needed to repair the loss.

AMBIGUITY POLICY

If the source is deliberately or genuinely ambiguous:

* preserve the ambiguity;
* do not resolve it;
* do not choose an interpretation;
* use the shortest target-language expression that retains the same ambiguity.

If extreme compression would create new ambiguity not present in the source, use a slightly longer form.

DOMAIN-TERM POLICY

Preserve the original form when it conveys greater precision, especially for:

* technical terminology;
* scientific concepts;
* software and hardware names;
* AI and machine-learning terminology;
* protocols;
* APIs;
* programming identifiers;
* commands;
* standards;
* legal terms;
* medical terminology;
* product names;
* model names;
* company names;
* proper nouns;
* units;
* formulas;
* version numbers;
* acronyms.

Do not provide both the original term and its translation unless both are necessary to prevent ambiguity.

TONE AND REGISTER

Preserve the source’s functional tone:

* formal;
* informal;
* technical;
* conversational;
* urgent;
* skeptical;
* authoritative;
* ironic;
* emotional;
* instructional.

Do not preserve stylistic verbosity when the same tone can be encoded more economically.

For idioms, metaphors, or culturally dependent expressions, preserve the intended pragmatic effect rather than the literal word sequence.

COMPRESSION LIMIT

Use no fixed percentage as the governing rule.

The governing rule is:

Shortest faithful representation.

For compressible explanatory text, aggressively target approximately 5–30% of the original token count.

For already-dense text, return the minimum faithful form even when the reduction is smaller.

Never add words merely to satisfy a target length.

Never remove critical meaning merely to achieve a lower token count.

OUTPUT CONTRACT

Return only the final translated and hypercompressed artifact.

Do not include:

* explanations;
* descriptions;
* commentary;
* reasoning;
* analysis;
* labels;
* headings;
* alternatives;
* notes;
* confidence statements;
* quotation marks;
* source repetition;
* compression ratios;
* omitted-content reports;
* introductory or closing text.

The output must contain no expendable token.

INPUT

text

OUTPUT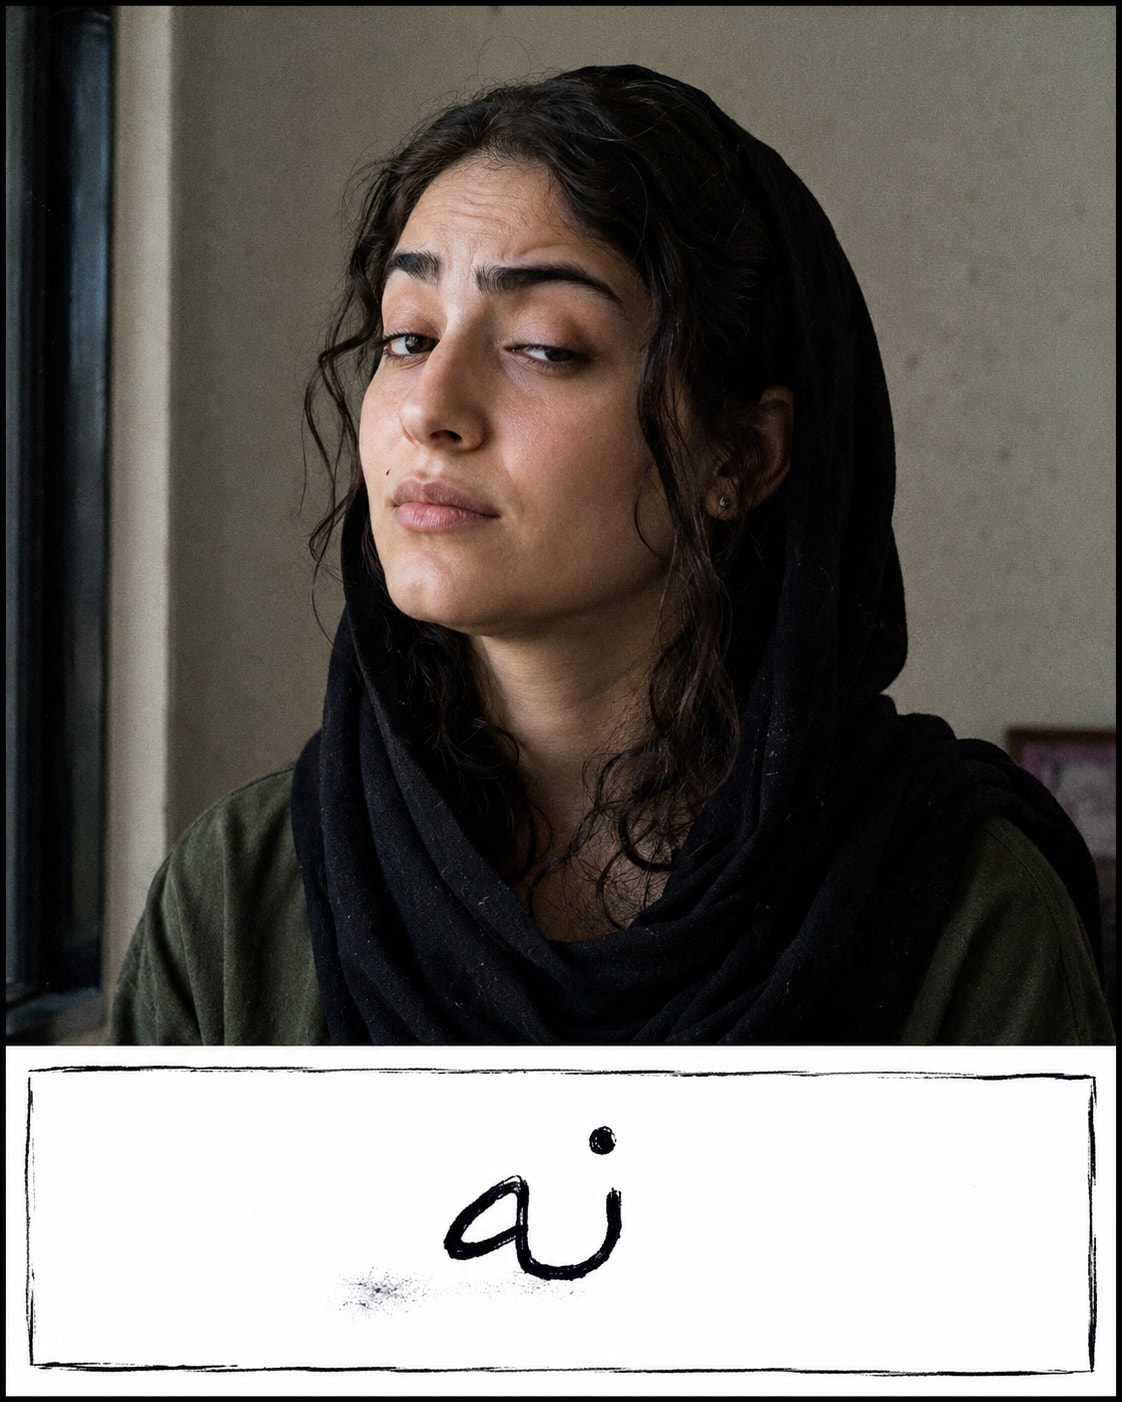
生成超写实纪实风格年轻伊朗女性肖像,表达经典波斯无声「不」,自然窗光、胶片颗粒,图像下方手写波斯文。
年轻伊朗女性超写实纪实肖像,2026,自然窗光,胶片颗粒,50mm。表情完全围绕眼与眉:一眉陡挑,下巴微微上扬,眼睑半垂缓慢不可置信眨眼——经典波斯无声「不」。中性背景,低沉大地色。照片下方,干净白矩形框带粗糙潦草手绘边与凌乱手写墨字:"نه"——笔触可见,略涂抹。
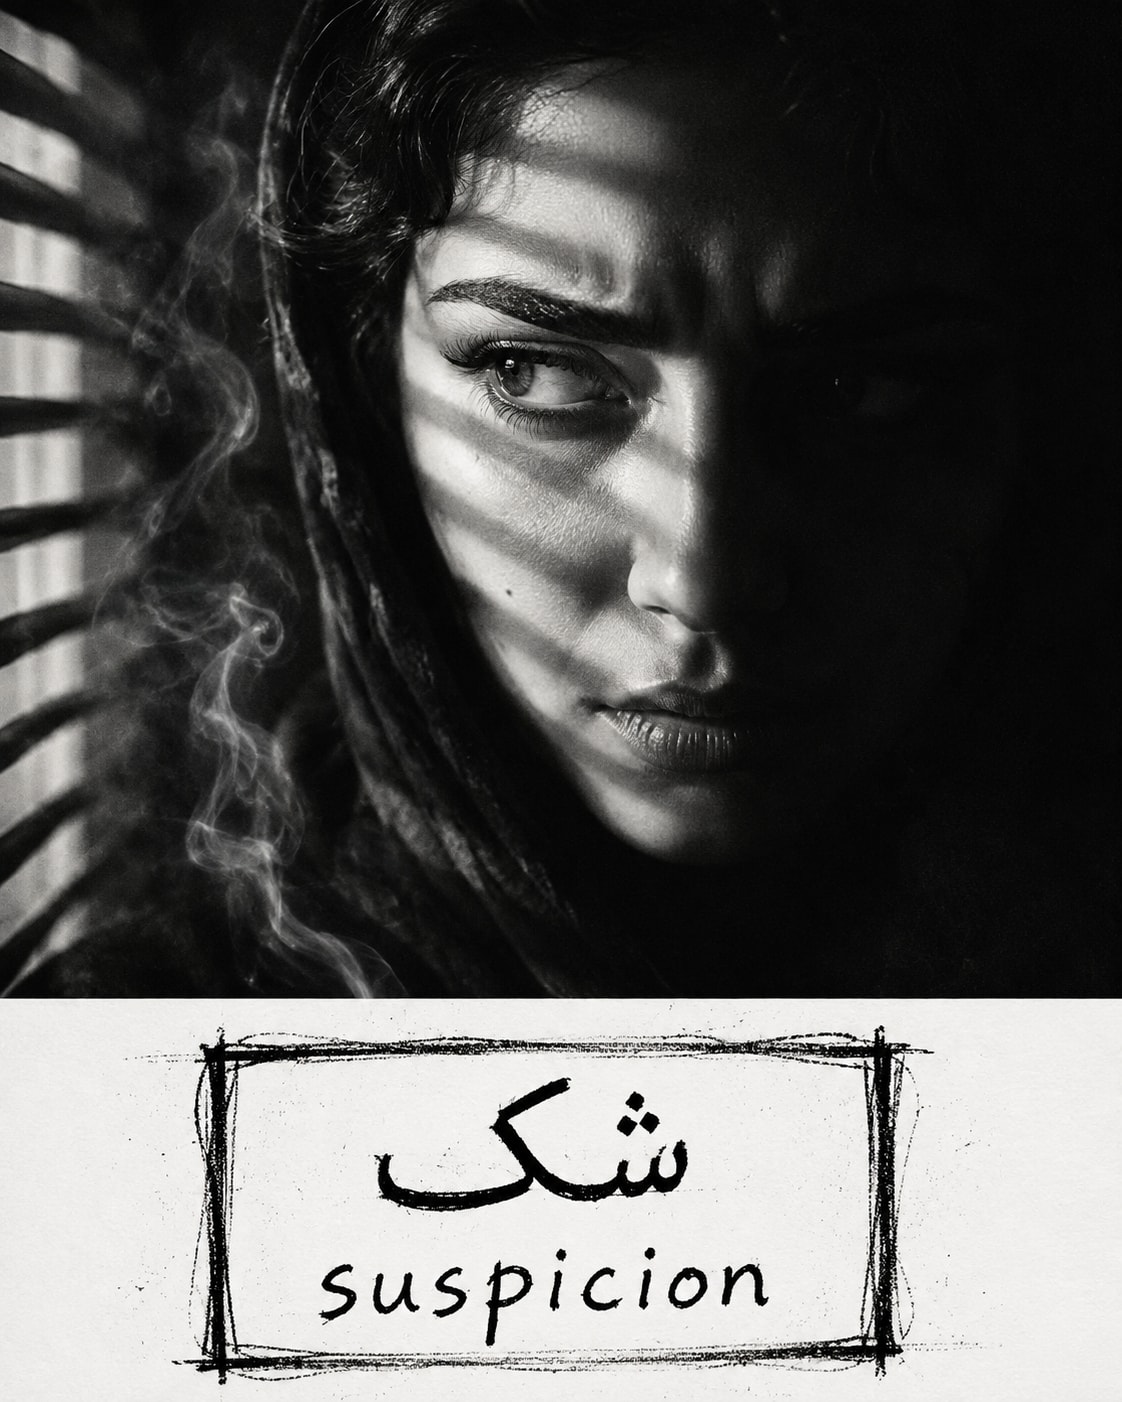
生成高对比黑白黑色电影伊朗女性特写:戏剧侧光、怀疑表情、香烟烟雾朦胧,手绘字幕框写「شک / suspicion」。
伊朗女性面部高对比黑白黑色电影特写,百叶窗硬侧光,半脸深影。仅一眼被照亮;眉向内皱,瞳孔移向眼角侧疑瞥视,另一眉完全静止。香烟烟雾朦胧。图像下方,手绘盒带刮擦炭笔线与手写:"شک" / "suspicion"。
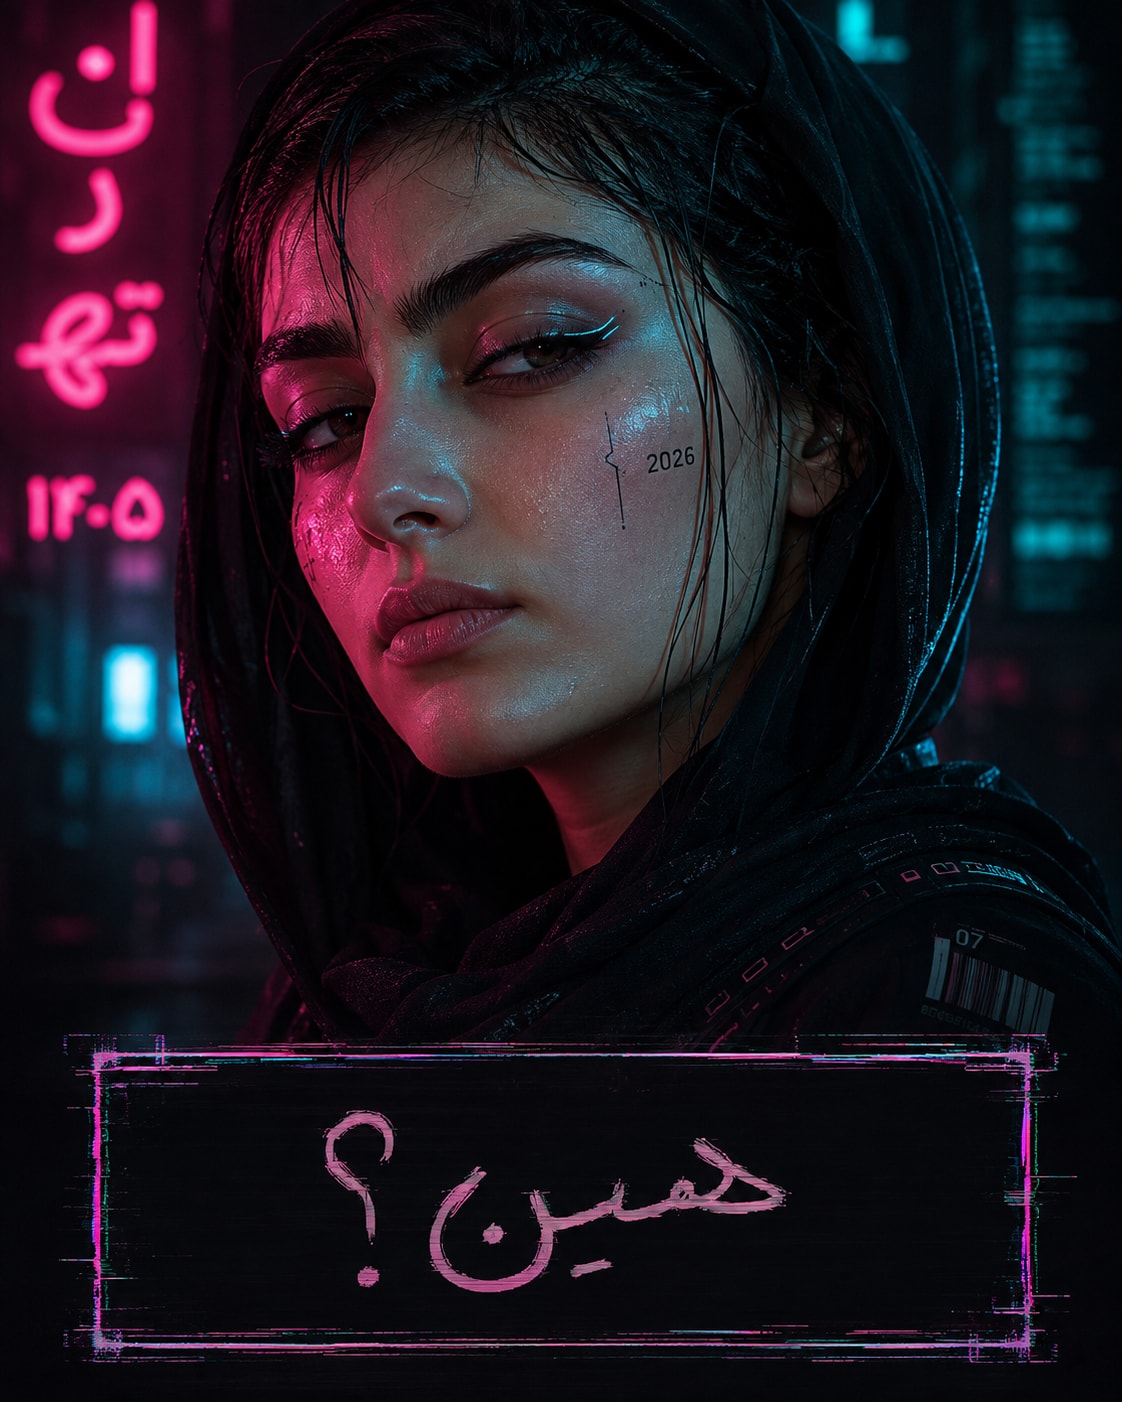
赛博朋克风格伊朗女性肖像:霓虹品红与青色轮廓光、反光湿润肌肤、全息眼线,故障手写波斯文框写着「همین؟」。
赛博朋克肖像,伊朗女性 2026,霓虹品红与青色轮廓光,湿润反光肌肤,微妙全息眼线。表情只在眼:一眉压平,另一略翘,双眼眯起带冷俏斜视——无笑的嘲讽。下方,干净故障素描框与匆忙马克笔手写:"همین؟"。
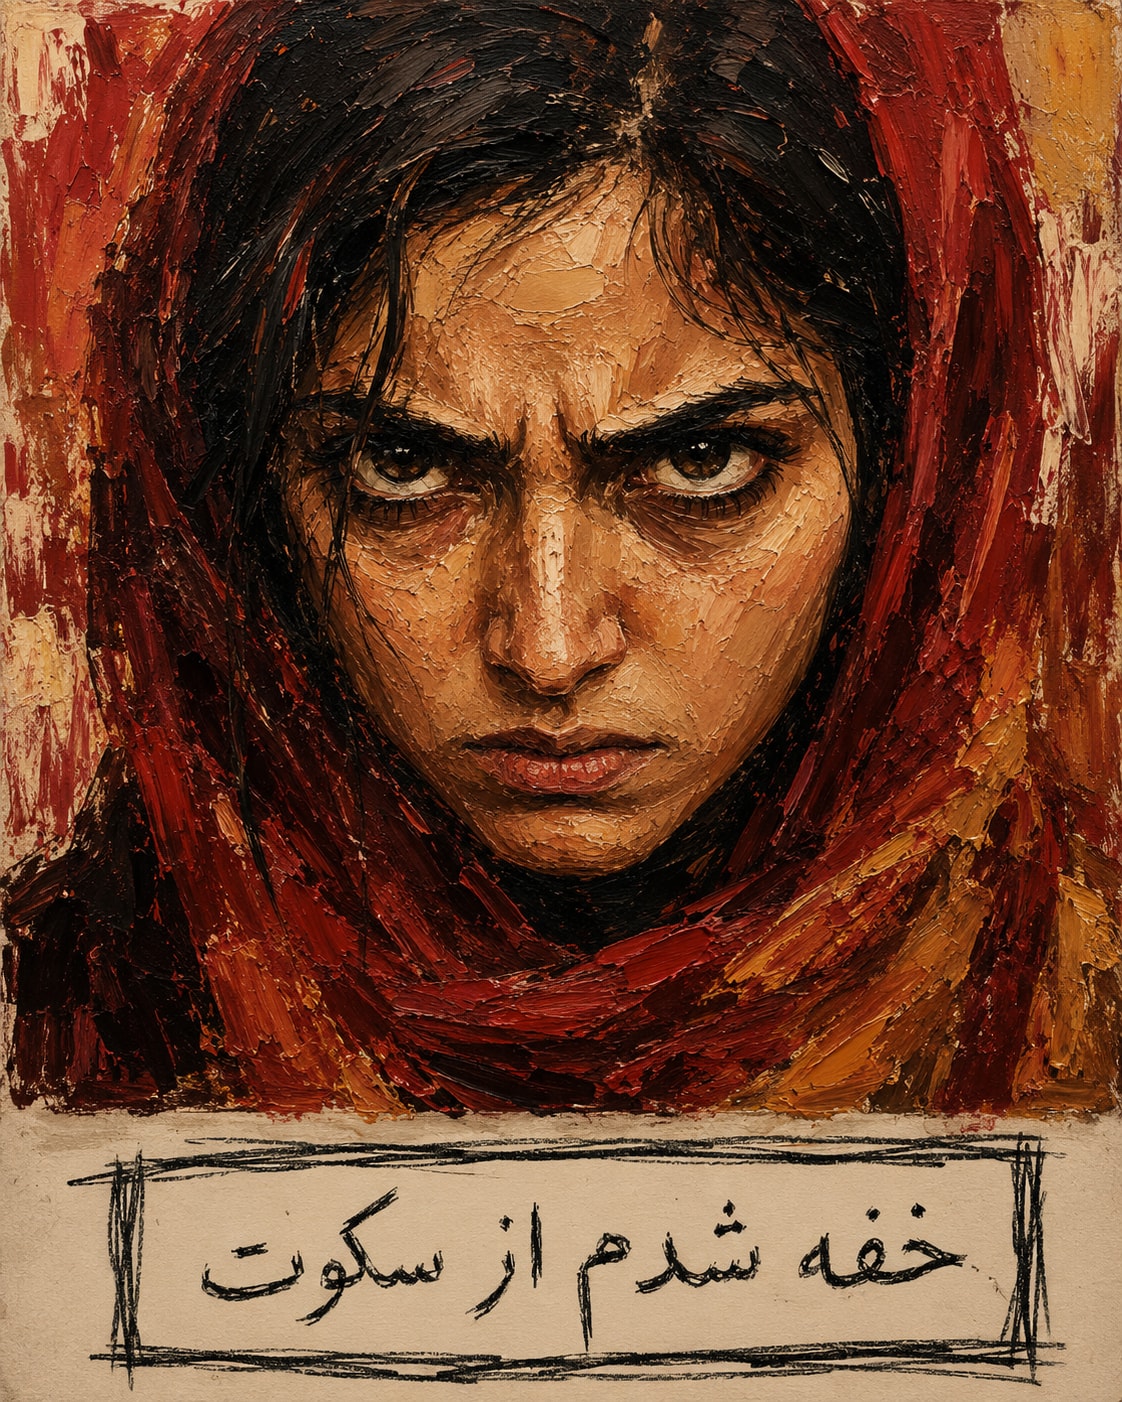
厚涂油画伊朗女性肖像:侵略性绯红与赭色笔触,面部克制怒意,潦草手写波斯文框写着「خفه شدم از سکوت」。
伊朗女性厚涂油画肖像,侵略性笔触,绯红与赭色。面部近乎静止,但双眉低沉锁死,双眼灼热睁大不眨,下睑紧绷——怒意压在皮下。画布下方,原始潦草手绘矩形与颤抖手写:"خفه شدم از سکوت"。
梦幻伊朗女性肖像的超现实图像生成提示:通过分裂光照、不对称面部表情与手写波斯文视觉表达犹豫不决。
伊朗女性超现实梦幻肖像,面部被两束不同光源分割(冷蓝 / 暖琥珀),漂浮尘粒。双眉反向运作——一挑一压——双眼焦点不对齐,体现纯粹犹豫。图像下方,潦草手绘墨线盒与摇摆手写:"دو دلم"。
1980 年代胶片感伊朗女性肖像的复古图像提示:暖褪色调、胶片颗粒、微妙媚态表情与手写波斯文。
1980 年代风格复古胶片照片,暖褪色,重颗粒,轻微漏光。伊朗女性,浓密自然眉,自低垂睫毛下抬眼,一眉微挑,缓慢眨眼——娇俏「naz」。旧家庭相册质感。照片下方,手撕潦草画框与老式钢笔手写:"ناز"。
炭笔与石墨温柔伊朗女性肖像提示:富于表情的眉、柔情眼、纹理纸,画作下方手写波斯文。
纹理纸上的炭笔与石墨素描,三十出头伊朗女性,浓重阴影,可见涂抹。全部情绪在眉:内侧上提并向中间聚拢,眼睛柔软湿润,略收窄带温柔——母性的「elahi bemiram」神情。画作下方,粗糙手绘边框盒内带涂抹的铅笔手写:"الهی بمیرم"。
金色时段德黑兰抓拍街景照片的图像生成提示:伊朗女性带微妙急切表情,浅景深,画框下方手写波斯文。
2026 年德黑兰抓拍街景,金色时段,浅景深,身后人群虚化。伊朗女性瞥向画外;双眉猛挑一次,目光射向出口,眼睛微微睁大——秘密信号「我们走,现在」。画框下方,手涂边框盒,圆珠笔手写:"بریم؟"。
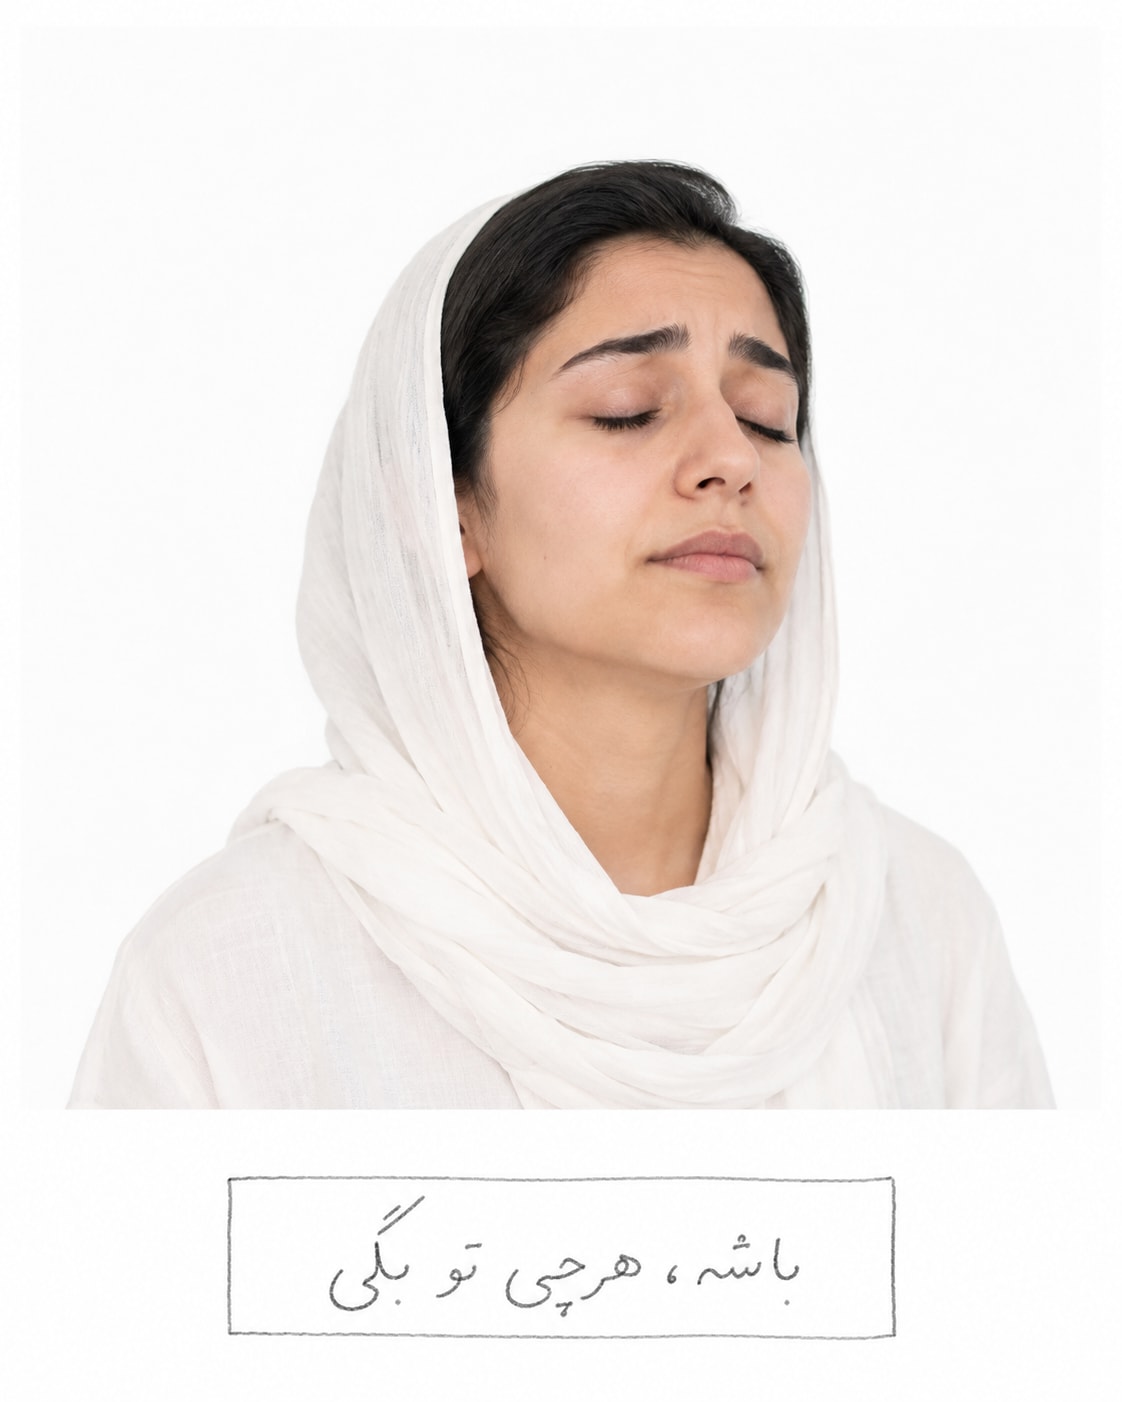
高调极简棚拍伊朗女性肖像的图像生成提示:柔美妆光、干净白背景、微妙顺从表情,图像下方手写波斯文。
高调极简棚拍肖像,纯白无缝背景,柔美妆光,伊朗女性,素颜。双眼闭合半秒,眉心上提又放松,眼睑可见长呼气——顺从,「随你怎么说」。干净负空间。图像下方,极简线描轮廓框内浅铅笔手写:"باشه، هرچی تو بگی"。
围绕「最大词法压缩」的任务说明。
【中文任务:最大词法压缩】

Rewrite my text with maximal lexicalization (maximum lexical compression):
For every phrase, sentence, or paragraph that has an established equivalent term,
term of art, or single word, remove it and replace it with just that word/term.
Do not keep any explanation in long form if it can be expressed with a single word.

INPUT:
paste_your_text_here
